Home / MLT / Week 9 / Real questions
MLT week 9 - real exam questions
39 questions pulled from past papers whose wording matches this week's topics, newest first, duplicates removed. Pick your answers, then press Check answers. Figures and answer keys are the originals.
Elapsed 00:00
Given a linearly separable dataset with margin  and radius
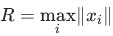 , which of the following statements about the perceptron algorithm are true?
and radius
, which of the following statements about the perceptron algorithm are true?- At a misclassified point
 , a single application of the update rule is guaranteed to classify correctly immediately after that step.
- For any linearly separable data with margin
 , the perceptron always converges to one unique separating hyperplane, independent of the order in which misclassified points are presented.
- Let
 (points in
 ,
 examples) and
 (points in
 ,
 examples) be two linearly separable datasets with
 and
 . The perceptron's worst-case mistake count is always larger for than for .
- None of these.
Consider the following dataset with two binary features 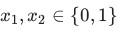 and binary label
 :
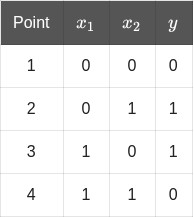 Consider the following three claims about this dataset: (i) Logistic regression (using the raw features
 , with or without a bias term) can achieve zero training error. (ii) A decision tree of depth at most
 , using axis-aligned splits on , can achieve zero training error. (iii)
 -nearest-neighbour, evaluated on this training set, achieves zero training error. Consider each point is its own nearest neighbour. Select the option that lists exactly the claims that are true.
and binary label :
Consider the following three claims about this dataset: (i) Logistic regression (using the raw features , with or without a bias term) can achieve zero training error. (ii) A decision tree of depth at most , using axis-aligned splits on , can achieve zero training error. (iii) -nearest-neighbour, evaluated on this training set, achieves zero training error. Consider each point is its own nearest neighbour. Select the option that lists exactly the claims that are true.- (i), (ii) and (iii)
- Only (ii) and (iii)
- Only (i) and (iii)
- Only (iii)
Suppose the dataset is initially linearly separable. Later, the data-generating process changes and the class boundary becomes highly nonlinear, for example:  for one class and
 for the other. Without manually creating nonlinear features, which classifier among the three is most naturally capable of representing this type of decision boundary?
for one class and for the other. Without manually creating nonlinear features, which classifier among the three is most naturally capable of representing this type of decision boundary?- Perceptron
- Logistic Regression
- Decision Tree
- None of these
Consider logistic regression on one-dimensional data, with 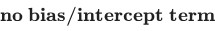 (the model is
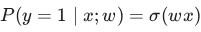 ). The current weight is
 , the training set is a single example
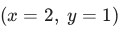 , and the step size is
 . Gradient ascent is performed directly on the log-likelihood of the data. Compute
 after one gradient-ascent step. (Round to decimal places; enter
 if it cannot be determined.)
(the model is ). The current weight is , the training set is a single example , and the step size is . Gradient ascent is performed directly on the log-likelihood of the data. Compute after one gradient-ascent step. (Round to decimal places; enter if it cannot be determined.)In logistic regression, a point is classified positive only if 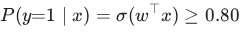 . What score threshold
 (with
 at the boundary of this rule) does this correspond to? (Round to
 decimal places.)
. What score threshold (with at the boundary of this rule) does this correspond to? (Round to decimal places.)Let 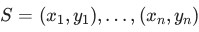 be points in
 that are linearly separable by a hyperplane through the origin. Construct
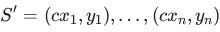 where
 is a constant. The perceptron algorithm (initialised at
 , learning rate ) is run on both
 and
 , using the same ordering of points in both runs. Which of the following statements are true?
be points in that are linearly separable by a hyperplane through the origin. Construct where is a constant. The perceptron algorithm (initialised at , learning rate ) is run on both and , using the same ordering of points in both runs. Which of the following statements are true?- The mistake bound of the perceptron on is strictly larger than its mistake bound on .
- may fail to be linearly separable.
- The perceptron is guaranteed to converge on .
- The perceptron produces exactly the same decision boundary on and on .
Consider binary classification on input features  . Define the decision boundary of a trained classifier as the set of points at which its predicted label changes. For which of the following method(s) can this decision boundary be non-linear in ?
- Perceptron.
- Logistic regression, predicting the positive class when
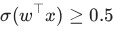 .
- -nearest-neighbour with Euclidean distance.
- A decision tree using axis-aligned splits.
- Gaussian Naïve Bayes in which the class-conditional feature variances differ between the two classes.
- A support vector machine with a linear kernel.
- A support vector machine with an RBF (Gaussian) kernel.
Let
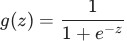 be the sigmoid (logistic) function. Select all statements below that are true for every
 .
be the sigmoid (logistic) function. Select all statements below that are true for every .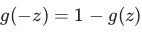 .
 is a non-decreasing function but not strictly increasing.
- is a strictly increasing function.
- is convex on all of
 .
Consider the effect of each operation below on a model's bias and variance. Which of the following statements are correct?
- Regularising the weights in a linear/logistic regression model increases bias and decreases variance.
- Increasing the maximum depth of a decision tree increases bias and decreases variance.
- Increasing the number of hidden units in a neural network decreases bias and increases variance.
- Removing all the non-support-vectors from the training set of an SVM leaves both bias and variance unchanged.
In logistic regression, a point is classified positive only if 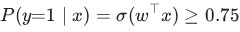 . What score threshold (with at the boundary of this rule) does this correspond to? (Round to 2 decimal places.)
Consider a binary classification dataset in which the two classes are perfectly linearly separable. You are considering a Perceptron, Logistic Regression, and a Decision Tree. If the objective is to learn a linear decision boundary and no probability estimates are required, which of the following classifiers are appropriate choices?
- Perceptron only
- Logistic Regression only
- Both Perceptron and Logistic Regression
- Decision Tree only
Two loss functions are plotted in this graph. What are the two?
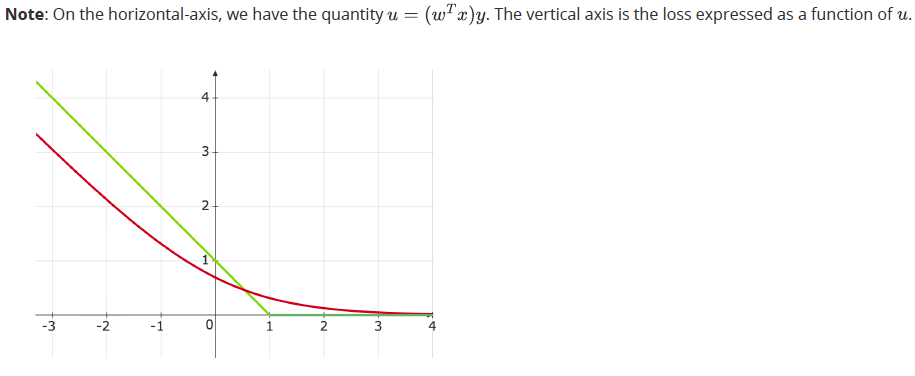
- Logistic loss
- Hinge loss
- Squared loss
- 0-1 loss
Consider a logistic regression classifier trained on a dataset for a binary classification problem with features in  and labels in
 . The weight vector learnt by the classifier is
 . Given a test data-point
 , the probability
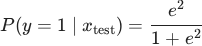 , where
 is the base of the natural logarithm. Find the value of
 and enter the nearest integer as your answer.
and labels in . The weight vector learnt by the classifier is . Given a test data-point , the probability
, where is the base of the natural logarithm. Find the value of and enter the nearest integer as your answer.Consider a dataset with two data-points for a binary classification problem with features in  .
 is a data-point from the positive class while
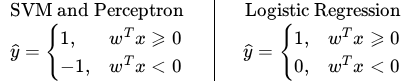
 is from the negative class. We now consider three linear classifiers: perceptron, logistic regression and SVM.
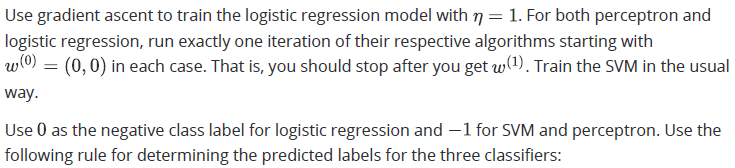 If
 is the weight vector with the largest margin, which of the following is true?
. is a data-point from the positive class while is from the negative class. We now consider three linear classifiers: perceptron, logistic regression and SVM.
If is the weight vector with the largest margin, which of the following is true?
- All three classifiers output

- Only SVM outputs
- Only SVM and perceptron output
- Only perceptron and logistic regression output
Consider a binary classification dataset in that is linearly separable. Suppose there exist two distinct weight vectors  and
 that both correctly classify all training points with a positive margin. The Perceptron algorithm is applied to this dataset. Which of the following statements are correct? (Select all that apply.)
that is linearly separable. Suppose there exist two distinct weight vectors and that both correctly classify all training points with a positive margin. The Perceptron algorithm is applied to this dataset. Which of the following statements are correct? (Select all that apply.)- The Perceptron algorithm is guaranteed to converge to .
- The final weight vector obtained by the Perceptron algorithm depends on the initialization and the order in which the data points are presented.
- The Perceptron algorithm is guaranteed to converge to some separating hyperplane in a finite number of updates.
- The Perceptron algorithm always converges to the maximum margin separator among all possible separating hyperplanes.
Consider a binary classification problem using logistic regression. The model predicts the probability of class  as:
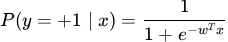 A threshold of
 is used for classification. The predicted class label is given by:
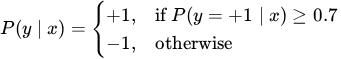 The values of
 for the following datapoints are:
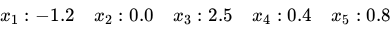 How many datapoints will be classified as class ?
as:
A threshold of is used for classification. The predicted class label is given by:
The values of for the following datapoints are: How many datapoints will be classified as class ?Consider two datasets  and
 where
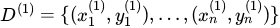 and
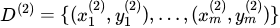 such that
 and
 , where
 and
 . The maximum number of mistakes made by the perceptron algorithm is higher on dataset than on dataset .
and where and such that and , where and . The maximum number of mistakes made by the perceptron algorithm is higher on dataset than on dataset .- True
- False
Given a two-dimensional data set where points from class 1 are: {(−2, 3), (−1, 1)} and points from class 0 are: {(1, 3), (1, 4)}. Which of the following statements are true?
- The given data points from classes 1 and 0 can be linearly separated using ahard-margin SVM.
- A perceptron model and a hard-margin SVM can give different decisionboundary for this dataset.
- A soft-margin SVM would be a more robust choice than a hard-margin SVM forthis dataset as the dataset is not linearly separable.
- The width of the separation between the two supporting hyperplanes is 4.
Consider a logistic regression model trained to detect spam emails. Emails containing harmful phishing links are labeled as spam (1), while regular emails are labeled as not spam (0).
A good spam detector should correctly identify almost all emails with phishing links. Even a single phishing email incorrectly classified as not spam could expose users to significant risks. However, the detector may classify some regular emails as spam. This trade-off is acceptable to ensure safety.
To ensure user safety, if the threshold is set to a low value to prioritize the detection of phishing emails, type 1. If the threshold is set to a high value to minimize false positives (misclassifying regular emails as spam), type 0.
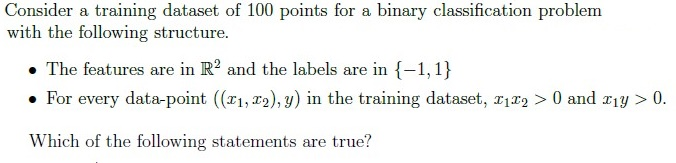
- The dataset is linearly separable with a positive margin.
- The perceptron algorithm will terminate after a finite number of iterationswhen trained on this dataset.
- The dataset is linearly separable, but the margin may be zero.
- The dataset is not linearly separable.
Comprehension passage for this question
Based on the above data, answer the given subquestions.
The weight vector output by the perceptron algorithm on this dataset can be expressed as a linear combination of the data-points where the coefficients of the linear combination are integers.
- TRUE
- FALSE
Comprehension passage for this question
Based on the above data, answer the given subquestions.
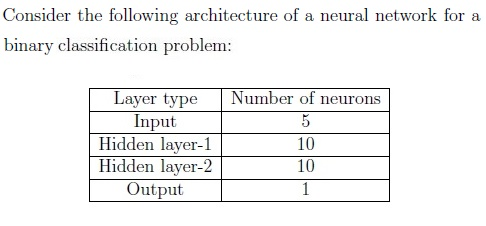
What is the most appropriate choice of activation function for the output layer if the binary cross-entropy loss is used?
- Sigmoid
- Linear
- ReLU
Comprehension passage for this question
Based on the above data, answer the given subquestions.
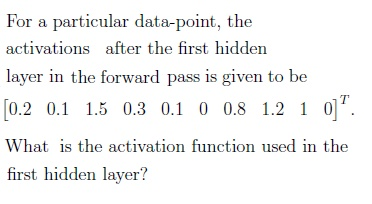
- ReLU
- Sigmoid
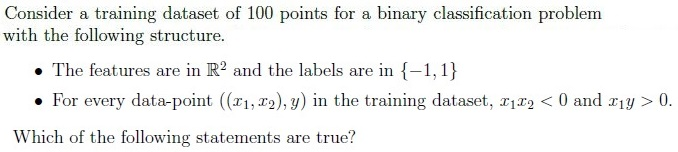
- The dataset is linearly separable with a positive margin.
- The perceptron algorithm will terminate after a finite number of iterationswhen trained on this dataset.
- The dataset is linearly separable, but the margin may be zero.
- The dataset is not linearly separable.
Comprehension passage for this question
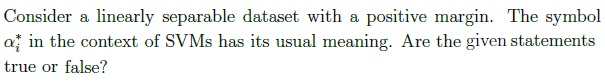
The weight vector output by the perceptron algorithm can be expressed as a linear combination of the data-points where the coefficients of the linear combination are integers.
- TRUE
- FALSE
Comprehension passage for this question
Based on the above data, answer the given subquestions.
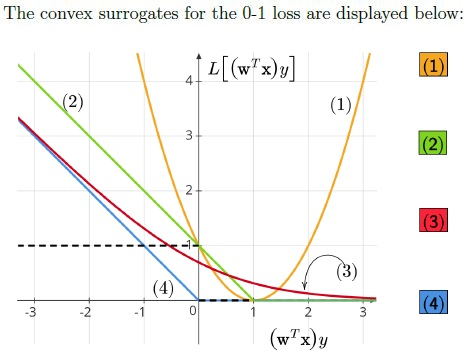
Enter the number corresponding to the logistic loss.
Comprehension passage for this question
Based on the above data, answer the given subquestions.
Enter the number corresponding to the perceptron loss.
Comprehension passage for this question
Based on the above data, answer the given subquestions.
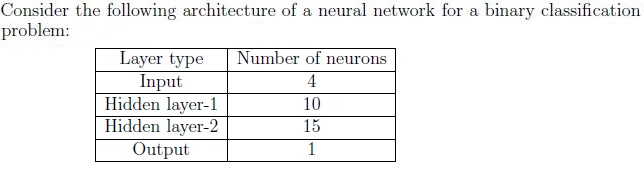
- ReLU
- Sigmoid
Consider a simple neural network with one hidden layer. The network has the following architecture: Input layer with 3 neurons. Hidden layer with 2 neurons, using the sigmoid activation function. Output layer with 1 neuron, using the linear activation function. The weights and biases for the network are as follows: Hidden Layer: Neuron 1: Weights: [0.5, -0.2, 0.8] Bias: 0.1 Neuron 2: Weights: [0.4, 0, 0.2] Bias: -0.4 Output Layer: Neuron 1: Weights: [0.2, 0.4] Bias: -0.3 Assume that the input values are [0.6, 0.3, 0.8]. Calculate output of Neuron 1 in hidden layer
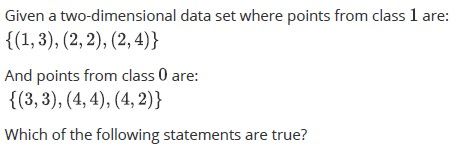
- The given data points from classes A and B can be linearly separated using aHard-margin SVM.
- Points (2, 2) from class 1 and (3, 3) from class 0 will be on the decisionboundary or support vectors.
- A Soft-margin SVM would be a more robust choice than a Hard-margin SVM forthis dataset as the dataset is not linearly separable.
- A perceptron model and a hard margin SVM will always give the same decisionboundary for this dataset.
Which of the following statements is/are true regarding logistic regression and perceptron algorithm?




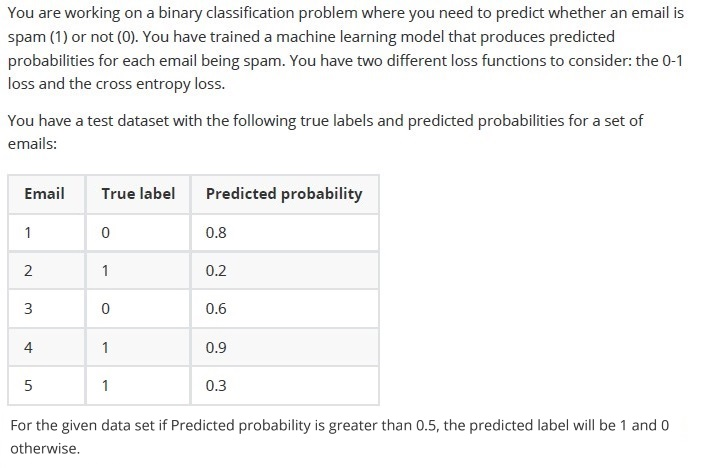
- The values of 0-1 loss function will be 3
- The values of cross entropy loss will be equals to 3.65
- The values of 0-1 loss equals 4.
- The values of cross entropy loss will be equals to 6.35
What is the maximum number of mistakes that the Perceptron algorithm can make in this data set?
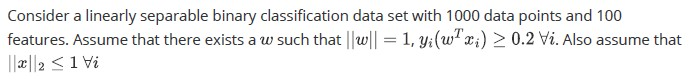
During classification of linearly separable data-set using perceptron algorithm, as the value of learning rate α is decreased,
- The number of steps required for convergence increases.
- The number of steps required for convergence decreases.
- The number of steps required for convergence is independent of the learningrate.
- The perceptron algorithm may not converge.
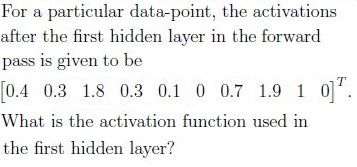
The following is the activation vector output by some hidden layer in a neural network when some input vector is given to it:
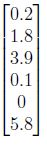 The following is the activation vector output by some hidden layer in a neural network when some input vector is given to it: Which of the following could be the activation function used in this layer?
- Softmax
- Sigmoid
- ReLU
- Tanh
You are given a linearly separable dataset with feature matrix X, for which a perceptron has been trained until it converges (perfectly separates the data). The weight vector corresponding to it is w. This dataset has 60 points from the positive class and 40 from the negative class. What is the output of the following snippet of code?
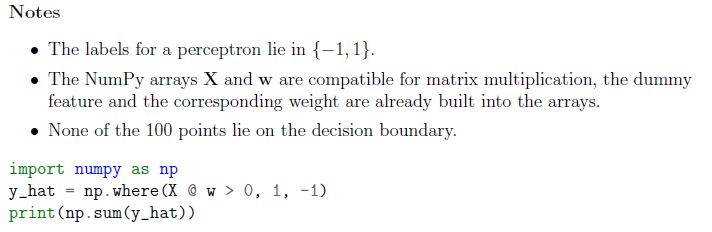 You are given a linearly separable dataset with feature matrix X, for which a perceptron has been trained until it converges (perfectly separates the data). The weight vector corresponding to it is w. This dataset has 60 points from the positive class and 40 from the negative class. What is the output of the following snippet of code?
 During classification of linearly separable data-set using perceptron algorithm, as the value of learning rate α is increased,
- The number of steps required for convergence increases.
- The number of steps required for convergence decreases.
- The number of steps required for convergence is independent of the learningrate.
- The perceptron algorithm may not converge.
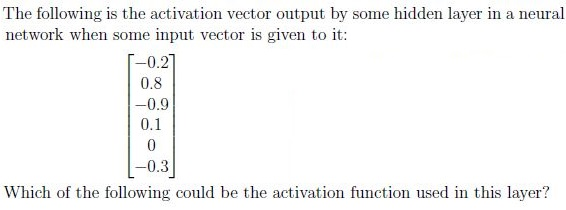
- Softmax
- Sigmoid
- ReLU
- Tanh
Consider a logistic regression model that is trained on videos to detect objectionable content. Videos with objectionable content belong to the positive class (label 1). Harmless videos belong to the negative class (label 0). A good detector should be able to correctly identify almost all videos that are objectionable. If it incorrectly classifies even a single video that has inappropriate content in it, that could have serious consequences, as millions of people might end up watching it. In this process the detector may classify some harmless videos as belonging to the positive class. But that is a price we are willing to pay. How should we choose the threshold (for inference) of this logistic regression model?
- The threshold should be a low value.
- The threshold should be a high value.
- The performance of the classifier is independent of the threshold.