Home / Past papers / MLT End Term / this paper
IIT M FOUNDATION ET1 EXAM QPF2 S2 03 Sep - 03 Sep 2023
Elapsed 00:00
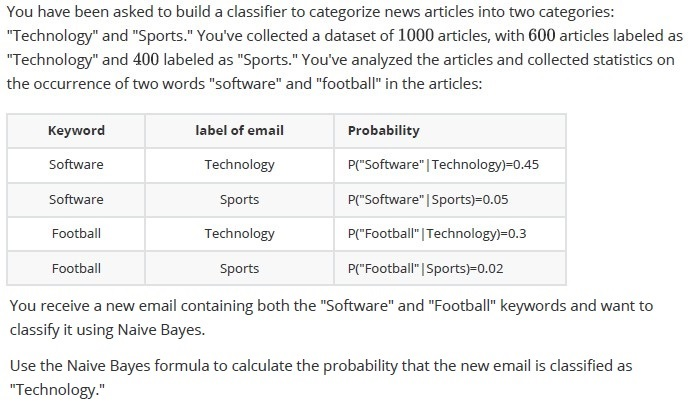
Hint: Assume that these are only two possible words (that is there are only two features)



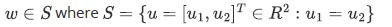
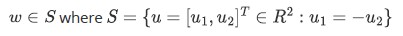
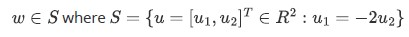
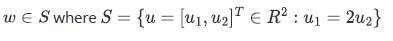






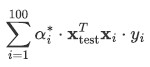
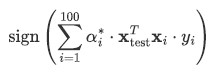
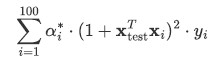
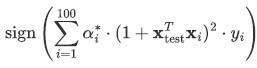
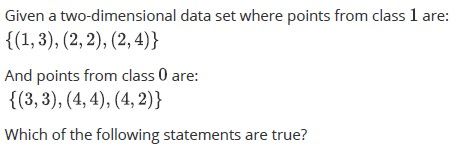
- The given data points from classes A and B can be linearly separated using aHard-margin SVM.
- Points (2, 2) from class 1 and (3, 3) from class 0 will be on the decisionboundary or support vectors.
- A Soft-margin SVM would be a more robust choice than a Hard-margin SVM forthis dataset as the dataset is not linearly separable.
- A perceptron model and a hard margin SVM will always give the same decisionboundary for this dataset.


Which of the following statements is/are true regarding logistic regression and perceptron algorithm?








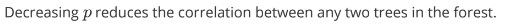



Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
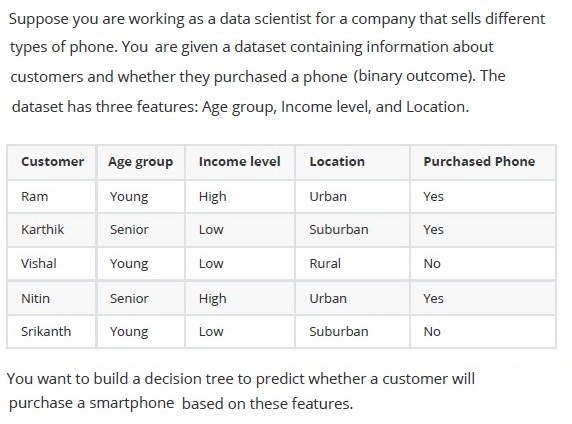
Calculate the information gain for the "Age Group" feature.
Calculate the information gain for the "Income level" feature.
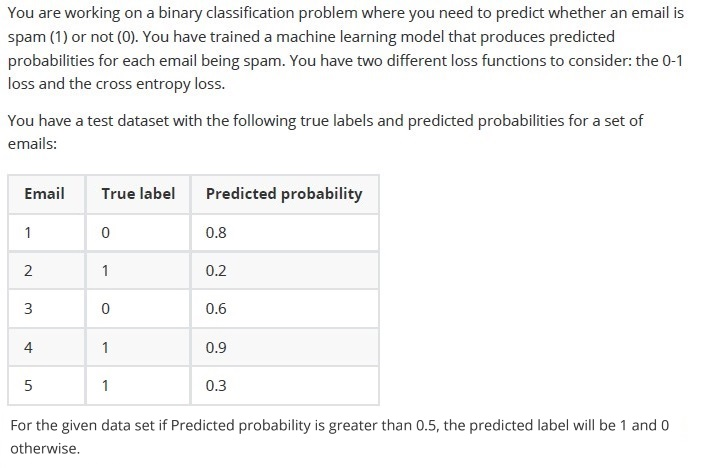
- The values of 0-1 loss function will be 3
- The values of cross entropy loss will be equals to 3.65
- The values of 0-1 loss equals 4.
- The values of cross entropy loss will be equals to 6.35
Answer key
- Q1 (SA, 6 marks): 0
- Q2 (SA, 6 marks): 0.20 to 0.40
- Q3 (SA, 6 marks): 0.98 to 1
- Q4 (MCQ, 6 marks): C
- Q5 (MCQ, 6 marks): A
- Q6 (MCQ, 6 marks): A
- Q7 (MCQ, 6 marks): B
- Q8 (MCQ, 6 marks): D
- Q9 (MCQ, 6 marks): A
- Q10 (MSQ, 6 marks): A, B
- Q11 (MSQ, 6 marks): A, B, D
- Q12 (MSQ, 6 marks): A, C, E
- Q13 (MSQ, 6 marks): B, C, D
- Q14 (SA, 4 marks): 0.20 to 0.60
- Q15 (SA, 4 marks): 0.20 to 0.60
- Q16 (MSQ, 7 marks): B, C
- Q17 (SA, 7 marks): 0.60 to 0.80
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Concepts
1. Principal Component Analysis (PCA)
- Purpose: Dimensionality reduction while preserving variance.
Steps:
- Compute the covariance matrix of the data.
- Compute eigenvalues and eigenvectors .
- Project data onto the top eigenvectors (principal components).
Reconstruction Error:
- If you retain the first components, the reconstruction error for a point is the sum of the squared projections onto the discarded components:
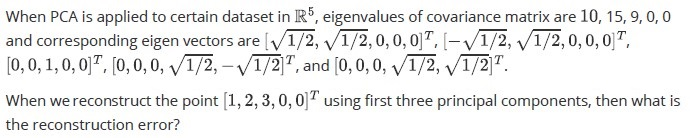
- For the given problem (Q2), since the last two eigenvalues are 0, the reconstruction error for any point in the span of the first 3 eigenvectors is 0.
2. Bayesian Estimation (Beta-Binomial Model)
- Prior: Beta distribution .
- Likelihood: Binomial distribution .
Posterior:
- Update parameters: , .
- Posterior mean:
Example (Q3):
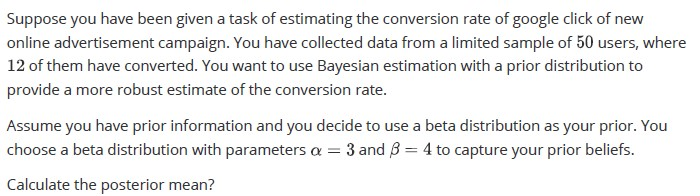
- Prior: .
- Data: , .
- Posterior: .
- Mean: .
3. Naive Bayes Classifier
- Assumption: Features are conditionally independent given the class.
- Posterior Probability:
Example (Q4):
- Classes: "Technology" (), "Sports" ().
- Words: "Software" and "Football".
- Compute using:
- Normalize by dividing by .
4. Gram Matrix & Positive Semidefiniteness
- Gram Matrix: for some data matrix .
Properties:
- Symmetric: .
- Positive Semidefinite: for all .
Example (Q5):
- Matrices A (non-symmetric), B (negative eigenvalue), and D (non-symmetric) cannot be Gram matrices.
5. Linear Regression
- Model: .
Solution: Minimize .
- Closed-form: .
Example (Q6):
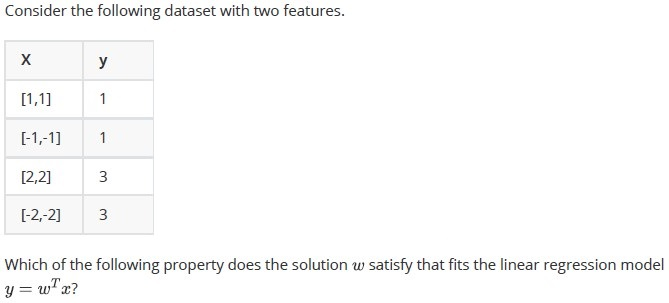
- The dataset is symmetric (), so the solution must satisfy .
6. Ridge Regression
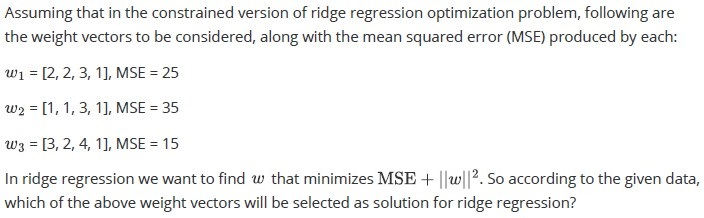
- Objective: Minimize .
- Trade-off: Balances fit (MSE) and complexity ().
Example (Q7):
- Compare for .
- has the lowest combined score.
7. Perceptron Algorithm
- Update Rule:
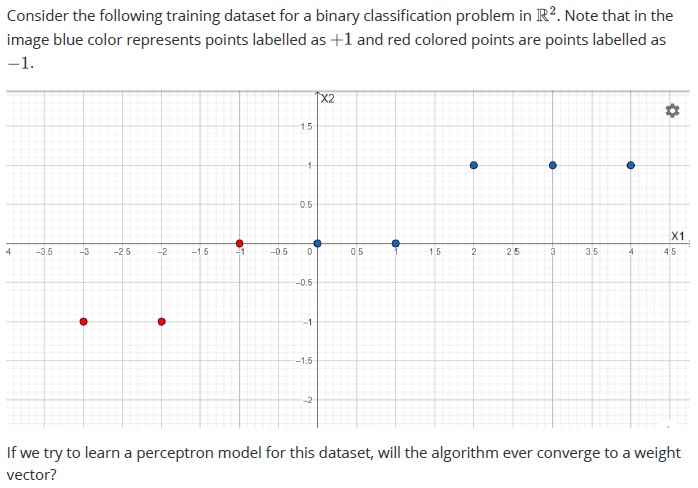
- Convergence: Guaranteed if data is linearly separable.
Example (Q8):
- The dataset is not linearly separable, so convergence depends on initialization .
8. Kernel SVM
- Decision Function:
- Polynomial Kernel (Degree 2):
Example (Q9):
- Predicted label: .
9. Linear Separability & SVM
- Hard-Margin SVM: Requires linear separability.
- Soft-Margin SVM: Allows misclassification (robust to noise).
Example (Q10):
- The dataset is linearly separable, so a hard-margin SVM works.
10. K-Means Clustering (Lloyd’s Algorithm)
- Objective: Minimize within-cluster variance.
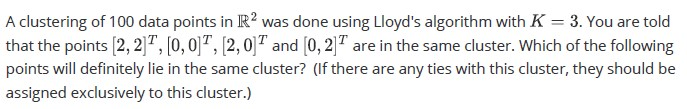
Example (Q11):
- Points , , , form a cluster centered at .
- and are closer to than other centers.
11. Logistic Regression vs. Perceptron
| Property | Logistic Regression | Perceptron |
|---|---|---|
| Output | Probability | Binary label |
| Loss | Cross-entropy | 0-1 loss (misclassification) |
| Convergence | Always (convex optimization) | Only if linearly separable |
| Nonlinear Data | Works (with kernel trick) | Fails |
Example (Q12):
- A, B, D are correct.
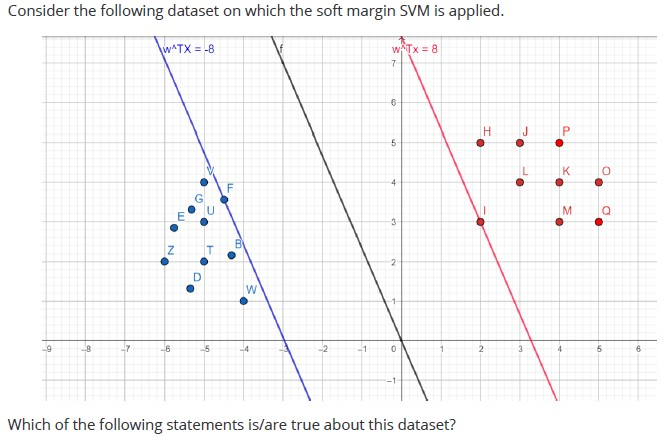
12. Soft-Margin SVM
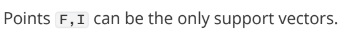
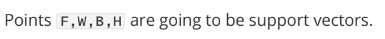
- Support Vectors: Points on the margin or misclassified.
Example (Q13):
- Only and are support vectors.
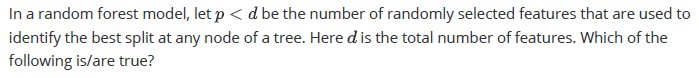
13. Random Forest
Feature Subsampling: Reduces correlation between trees.
- Decreasing (number of features) reduces correlation but may underfit individual trees.
- Increasing increases variance of the model.
Example (Q14):
- B, C, D are correct.
14. Decision Trees (Information Gain)
- Entropy:
- Information Gain:
Example (Q15 & Q16):
- Compute IG for "Age Group" and "Income Level".
15. Loss Functions
| Loss | Formula | Example (Q17) |
|---|---|---|
| 0-1 Loss | Value = 3 | |
| Cross-Entropy | Value ≈ 3.65 |
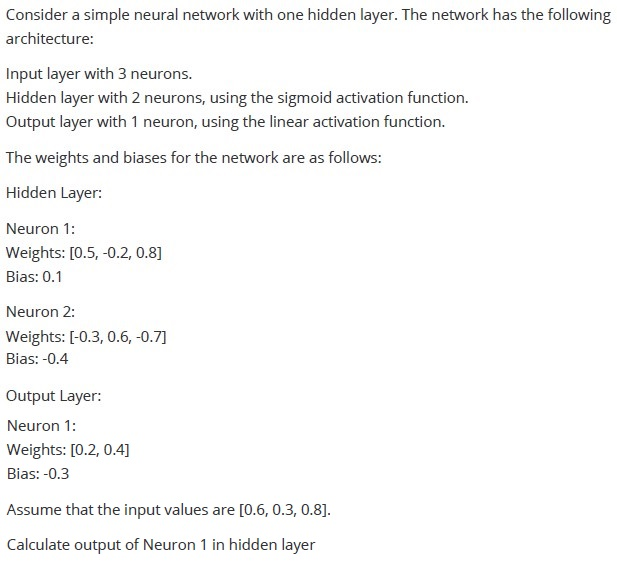
16. Neural Networks (Forward Pass)
- Sigmoid Activation:
Example (Q18):
- Compute output of Neuron 1 in the hidden layer: