Home / Past papers / MLT End Term / this paper
IIT M FOUNDATION DIPLOMA AN EXAM - 01 Sep 2024
Elapsed 00:00


- 1
- 2
- 3
- 6
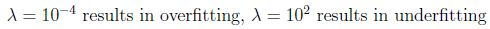
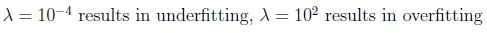
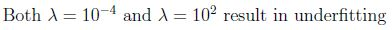
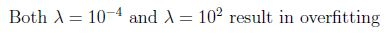
Match the characteristics given below with the appropriate ensemble technique. 1. Decision stumps 2. Deep decision trees 3. Parallel execution 4. Sequential execution
- Bagging → (2), (3); Boosting → (1), (4)
- Bagging → (1), (4); Boosting → (2), (3)
- Bagging → (1), (3); Boosting → (2), (4)
- Bagging → (2), (4); Boosting → (1), (3)
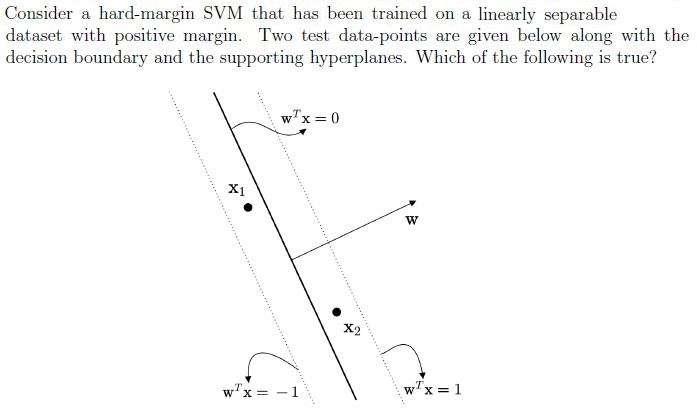
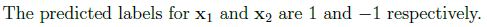
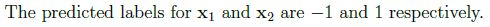
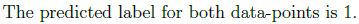
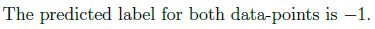

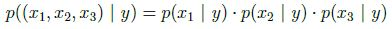
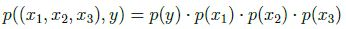
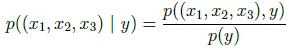
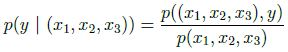
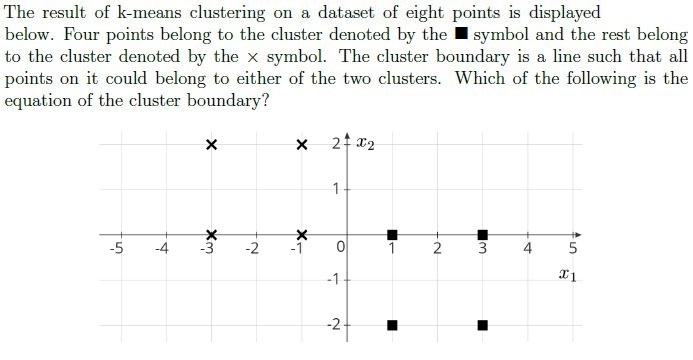
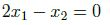
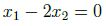
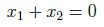
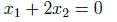
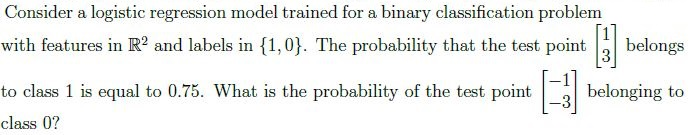
- 0.75
- 0.25
- 0.5
- 0.15
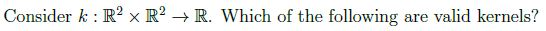
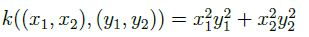
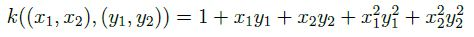
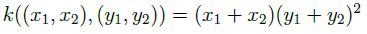
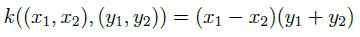
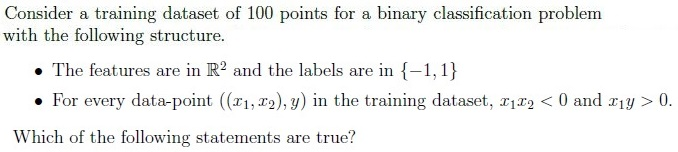
- The dataset is linearly separable with a positive margin.
- The perceptron algorithm will terminate after a finite number of iterationswhen trained on this dataset.
- The dataset is linearly separable, but the margin may be zero.
- The dataset is not linearly separable.
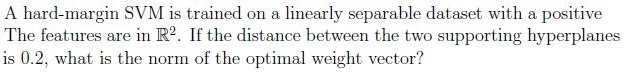
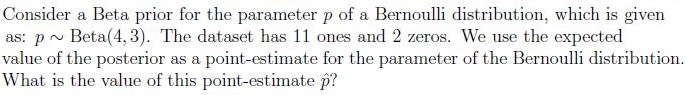
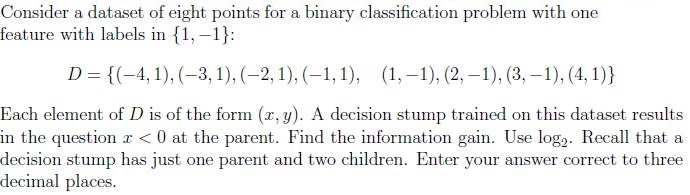
Comprehension passage - the questions below it refer to this
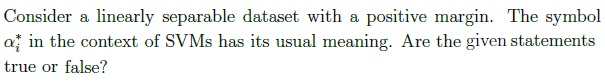
The weight vector output by the perceptron algorithm can be expressed as a linear combination of the data-points where the coefficients of the linear combination are integers.
- TRUE
- FALSE
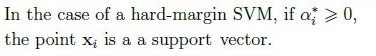
- TRUE
- FALSE
If a soft-margin SVM is trained on this dataset, the optimal weight vector it returns will be the same as the one returned by a hard-margin SVM, irrespective of the value of the hyperparameter C.
- TRUE
- FALSE
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
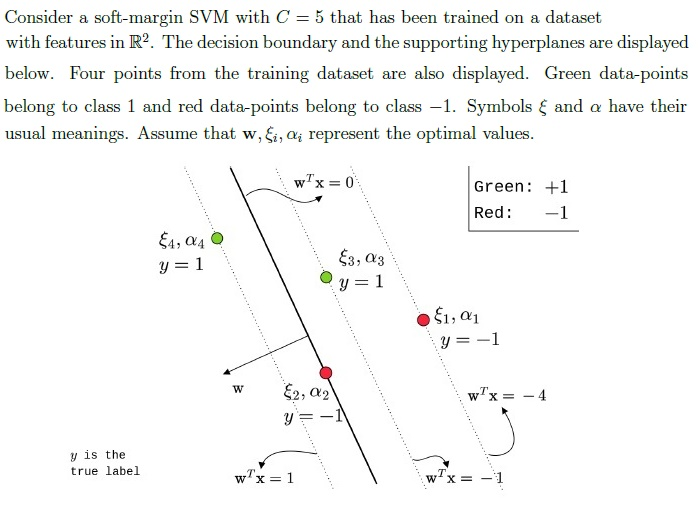


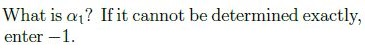
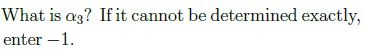
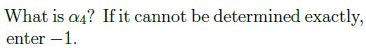
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
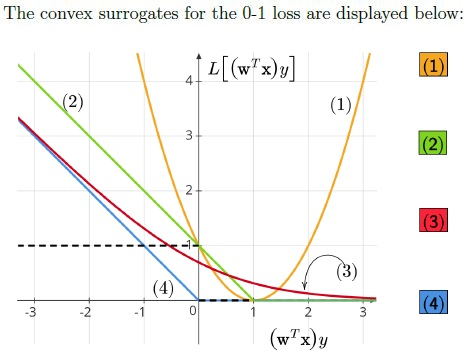
Enter the number corresponding to the logistic loss.
Enter the number corresponding to the (SVM) hinge loss.
Enter the number corresponding to the perceptron loss.
Enter the number corresponding to the squared loss.
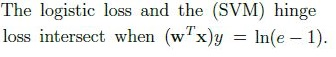
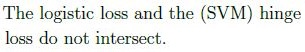
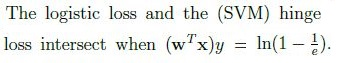
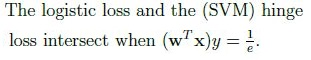
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
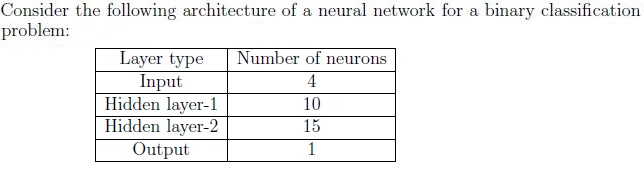
How many learnable parameters does this network have? Ignore the biases in the computation.
What is the most appropriate choice of activation function for the output layer if the binary cross-entropy loss is used?
- Sigmoid
- Linear
- ReLU
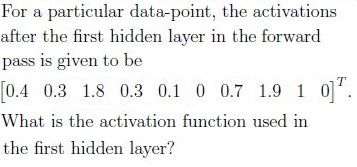
- ReLU
- Sigmoid
Answer key
- Q1 (MCQ, 2 marks): A
- Q2 (MCQ, 3 marks): C
- Q3 (MCQ, 3 marks): A
- Q4 (MCQ, 3 marks): A
- Q5 (MCQ, 3 marks): B
- Q6 (MCQ, 3 marks): A
- Q7 (MCQ, 3 marks): A
- Q8 (MCQ, 3 marks): A
- Q9 (MSQ, 3 marks): A, B
- Q10 (MSQ, 3 marks): A, B
- Q11 (SA, 3 marks): 10
- Q12 (SA, 3 marks): 0.75
- Q13 (SA, 3 marks): 0.50 to 0.60
- Q14 (MCQ, 1 marks): A
- Q15 (MCQ, 1 marks): B
- Q16 (MCQ, 1 marks): B
- Q17 (SA, 0.5 marks): 0
- Q18 (SA, 0.5 marks): 1
- Q19 (SA, 0.5 marks): 2
- Q20 (SA, 0.5 marks): 0
- Q21 (SA, 0.5 marks): 5
- Q22 (SA, 0.5 marks): -1
- Q23 (SA, 0.5 marks): 3
- Q24 (SA, 0.5 marks): 2
- Q25 (SA, 0.5 marks): 4
- Q26 (SA, 0.5 marks): 1
- Q27 (MCQ, 1 marks): A
- Q28 (SA, 1 marks): 205
- Q29 (MCQ, 1 marks): A
- Q30 (MCQ, 1 marks): A
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations for the Diploma Level: Machine Learning Techniques exam, along with Mermaid knowledge graphs to visualize relationships.
1. Core Topics & Concepts
A. Linear Regression & Gradient Descent
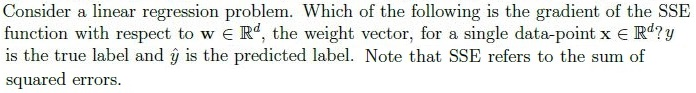
- Sum of Squared Errors (SSE):
- Gradient of SSE w.r.t. (for a single data point):
- Key Idea: Minimize SSE using gradient descent.
B. Principal Component Analysis (PCA)
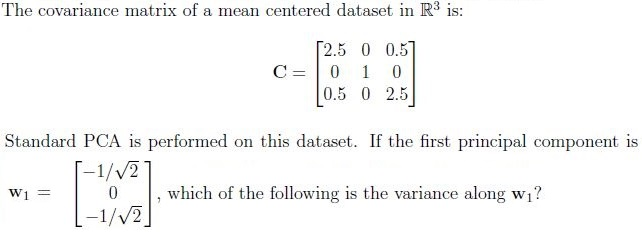
- Covariance Matrix :
- Variance along Principal Component :
- Eigenvalue Decomposition:
where contains eigenvectors (principal components) and contains eigenvalues (variances).
C. Regularization (Ridge/Lasso)
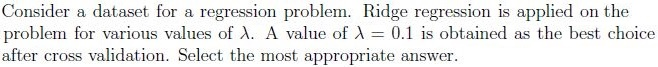
- Ridge Regression (L2):
- Small : Overfitting (high variance).
Large : Underfitting (high bias).
- Lasso (L1):
- Encourages sparsity (feature selection).
D. Support Vector Machines (SVM)
- Hard-Margin SVM (linearly separable data):
- Margin: .
Support Vectors: Points where .
- Soft-Margin SVM (non-separable data):
- Slack Variables : Measure misclassification.
Lagrange Multipliers :
- : Support vector.
- : Misclassified point.
E. Ensemble Methods
| Method | Key Characteristics | Example Models |
|---|---|---|
| Bagging | - Parallel execution | Random Forest |
| - Uses deep trees | ||
| - Reduces variance | ||
| Boosting | - Sequential execution | AdaBoost, Gradient Boosting |
| - Uses weak learners (e.g., decision stumps) | ||
| - Reduces bias |
F. Naive Bayes
- Class Conditional Independence:
- Posterior Probability:
G. Clustering (k-Means)
- Objective: Minimize within-cluster sum of squares (WCSS).
Cluster Boundary: Perpendicular bisector between centroids.
- For 1D data: Midpoint between centroids.
- For 2D data: Line equidistant to centroids.
H. Logistic Regression
- Sigmoid Function:
- Probability Interpretation:
- Symmetry Property:
I. Kernel Methods
- Valid Kernels must satisfy Mercer’s Condition (positive semi-definite Gram matrix).
Examples of Valid Kernels:
- Linear:
- Polynomial:
- RBF/Gaussian:
J. Decision Trees & Information Gain
- Entropy:
- Information Gain:
- Decision Stump: Tree with 1 split (2 leaves).
K. Neural Networks
- Learnable Parameters (ignoring biases):
Activation Functions:
- Output Layer (Binary Classification): Sigmoid (with cross-entropy loss).
- Hidden Layers: ReLU, tanh, etc.
- ReLU Property:
- If any activation is 0, the input to ReLU was ≤ 0.
L. Loss Functions
| Loss Function | Formula | Use Case |
|---|---|---|
| 0-1 Loss | Classification (non-convex) | |
| Hinge Loss (SVM) | SVM | |
| Logistic Loss | Logistic Regression | |
| Perceptron Loss | Perceptron | |
| Squared Loss | Regression |
- Intersection of Logistic & Hinge Loss:
M. Bayesian Learning
Beta-Bernoulli Model:
- Prior:
- Posterior:
- Point Estimate (Expected Value):
Graph 2: Unsupervised Learning Relationships
Graph 3: Ensemble Methods
Graph 4: SVM Components
Graph 5: Neural Network Architecture
Graph 6: Loss Functions
Graph 7: Bayesian Learning
3. Key Equations Summary
| Topic | Equation |
|---|---|
| SSE Gradient | |
| PCA Variance | |
| Ridge Regression | |
| SVM Hard-Margin | s.t. |
| SVM Soft-Margin | s.t. |
| Logistic Regression | |
| Information Gain | |
| k-Means Objective | |
| Neural Network Params | (ignoring biases) |
| Beta Posterior |
4. Exam Tips
- Linear Algebra: Focus on eigenvalues, gradients, and matrix operations (PCA, SVM).
- Optimization: Understand gradient descent, Lagrange multipliers (SVM), and regularization.
- Probability: Naive Bayes, Bayesian updating (Beta-Bernoulli).
- Geometry: SVM margins, cluster boundaries (k-Means), decision boundaries.
- Loss Functions: Know when to use which loss (hinge for SVM, logistic for classification, squared for regression).
- Ensemble Methods: Bagging vs. Boosting (parallel vs. sequential, deep trees vs. stumps).
- Neural Networks: Parameter counting, activation functions, output layer choices.