Home / MLP / Week 1 / Real questions
MLP week 1 - real exam questions
60 questions pulled from past papers whose wording matches this week's topics, newest first, duplicates removed. Pick your answers, then press Check answers. Figures and answer keys are the originals.
Elapsed 00:00
In the following question an Assertion (A) is followed by a Reason (R). Choose the correct option. Assertion (A): In a scikit-learn  , the last step must be a transformer that implements both
 and
 . Reason (R): Only the intermediate steps of a are required to implement ; the final estimator only needs to implement .
, the last step must be a transformer that implements both and . Reason (R): Only the intermediate steps of a are required to implement ; the final estimator only needs to implement .- Both A and R are true, and R is the correct explanation of A
- Both A and R are true, but R is not the correct explanation of A
- A is true, but R is false
- A is false, but R is true
- Both A and R are false
A news article dataset contains 10,000 documents. The word "government" appears in 9,500 documents, while the word "cryptocurrency" appears in only 200 documents. A TF-IDF vectorizer is applied to this dataset. Which of the following statements is most likely true?
- The TF value of "government" will always be lower than the TF value of "cryptocurrency" because it appears in more documents.
- The IDF contribution of "cryptocurrency" will be higher than that of "government", even if both words occur the same number of times in a document.
- If "government" appears 50 times in one article, its TF-IDF score must be higher than "cryptocurrency" appearing once in the same article.
- Removing "government" from the vocabulary will always decrease model performance because it appears in most documents.
What is the output of the following code? import pandas as pd from sklearn.preprocessing import OneHotEncoder df = pd.DataFrame({ "Color": ["Red", "Blue", "Green", "Blue", "Red"], "Size": ["S", "M", "L", "XL", "M"] }) encoder = OneHotEncoder(drop="first", sparse_output=False) X = encoder.fit_transform(df) print(X.shape[1])
The following categorical-encoding transformers are available in scikit-learn: 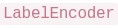 ,
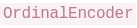 ,
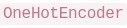 ,
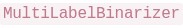 . Select ALL statements that are correct.
, , , . Select ALL statements that are correct.- can transform only 1-D data, whereas can operate on multi-dimensional (multi-feature) data.
- By default (with no dropping), creates K binary columns for a feature with K distinct categories.
- is designed to encode samples where each sample is associated with a set of labels.
- is preferred over for nominal (unordered) categories because it prevents the model from assuming any ordering among the categories.
Which of the following parameters of a DecisionTreeClassifier in Sklearn can be adjusted if the model has a high varience?
- ccp_alpha
- random_state
- min_samples_split
- max_depth
Consider two regularization models, Model A (Ridge) and Model B (Lasso), trained on a dataset where two input features are highly collinear ( X1≈X2 ).
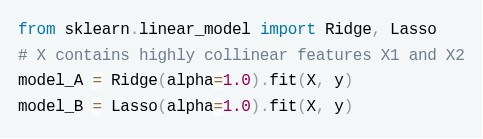 Which of the following statements accurately describe the expected behavior of these models and their evaluation metrics under severe collinearity?
- Model B (Lasso) will distribute the regression coefficients evenly across both X1 and X2 to balance the penalty, while Model A (Ridge) will force one of the coefficients to be exactly zero.
- Model A (Ridge) will shrink the coefficients of X1 and X2 toward zero but keep them roughly equal, whereas Model B (Lasso) will unstablely select one feature to keep and drive the coefficient of the other exactly to zero.
- If the target variable y contains extreme outliers, evaluating these models using Mean Squared Error (MSE) will penalize those large errors more heavily than Mean Absolute Error (MAE).
- Minimizing the MSE loss function during the training of Model A and Model B mathematically guarantees that the sum of the residual errors ( y−ŷ ) will always equal zero.
In the following question an Assertion (A) is followed by a Reason (R). Choose the correct option. Assertion (A): The order in which training samples are presented to the Perceptron can affect the final learned weight vector, even when the training data is linearly separable. Reason (R): If a dataset is linearly separable, the Perceptron algorithm is guaranteed to converge after a finite number of weight updates.
- Both A and R are true, and R is the correct explanation of A.
- Both A and R are true, but R is not the correct explanation of A.
- A is true, but R is false.
- A is false, but R is true.
A hospital develops a machine learning model to identify patients who may have a rare but life-threatening disease. Only about 1% of patients actually have the disease. Every patient predicted as positive is referred for an inexpensive follow-up blood test. However, missing an actual patient with the disease could delay treatment and have severe consequences. Which evaluation metric should be given the highest priority while selecting the model?
- Accuracy
- Precision
- Recall
- F1-score
After training a KMeans clustering algorithm on a dataset we find a data point is sitting exactly on or extremely close to the decision boundary between two neighboring clusters. Which of the following values will the silhouette score be close / equal to?
- 1
- 0
- -1
- infinity
Consider the following pandas DataFrame representing employee training records:
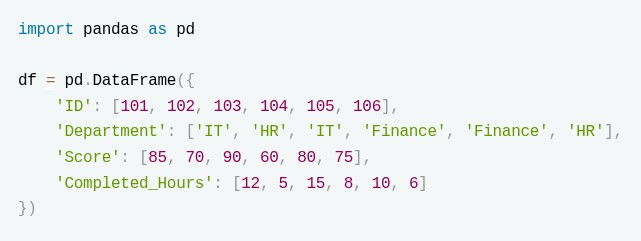 We want to retrieve all records of employees who belong to departments where the average training score is strictly greater than 75. Which of the following code snippets correctly achieves this?
- df[df['Score'] > 75]
- df.groupby('Department').filter(lambda x: x['Score'].mean() > 75)
- df[df.groupby('Department')['Score'].transform('mean') >= 75]
- df.groupby('Department').apply(lambda x: x[x['Score'] > 75])
Determine the output of the following text preprocessing pipeline:
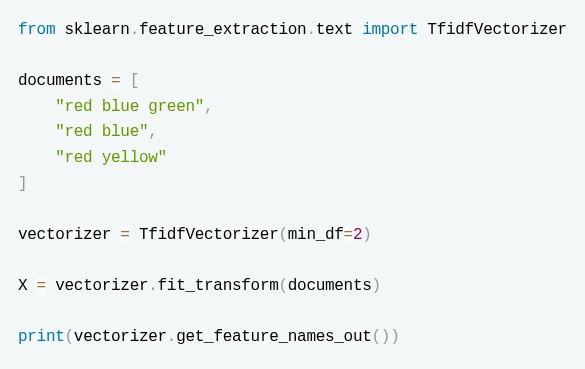
- ['red','blue','green','yellow']
- ['blue' 'red','yellow']
- ['blue' 'red']
- ['red','blue','green']
A genre-based content recommender uses the 19 one-hot genre columns of each movie:
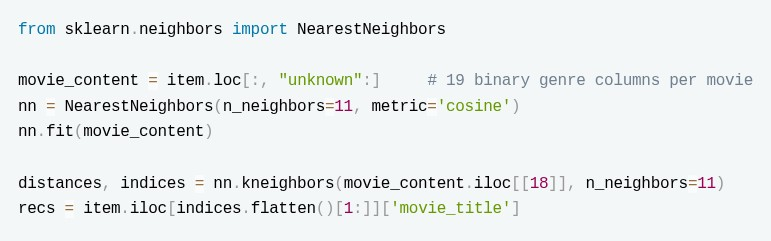 Which of the following statements is TRUE?
- With
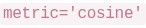 , the
 returned by
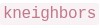 are cosine similarities lying in
 .
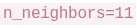 is used instead of
 because the nearest neighbour of any movie is the movie itself, which is then dropped via `indices.flatten()[1:]
- Because the genre vectors are binary, two movies that share no genre still receive a positive cosine similarity.
- Fitting
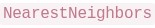 on the genre vectors additionally requires the user–item ratings matrix.
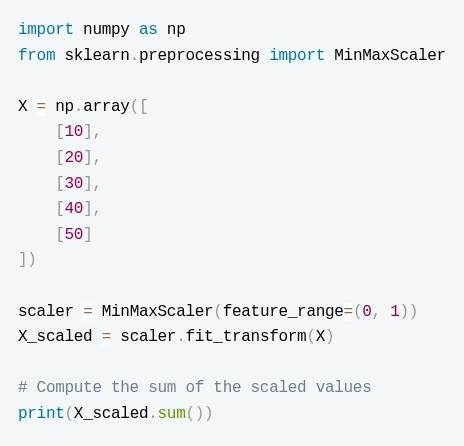
What is the output of the following preprocessing pipeline code? (Round off to 2 decimal places if applicable)
Suppose the orginal dataset has 10 rows (1 to 10) Which row/rows of the dataset will be printed if the following code is executed?
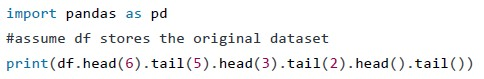 Enter the line number (1,2...,10) of the printed row. If multiple lines are printed enter the sum of the row numbers (i.e. if line 1 and 2 are printed enter 3)
The pipeline first imputes the missing value with the (mean) strategy and then standardizes the column. What is the value of 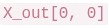 (the transformed value of the first sample, whose original value is 2)? (Enter up to 2 decimals)
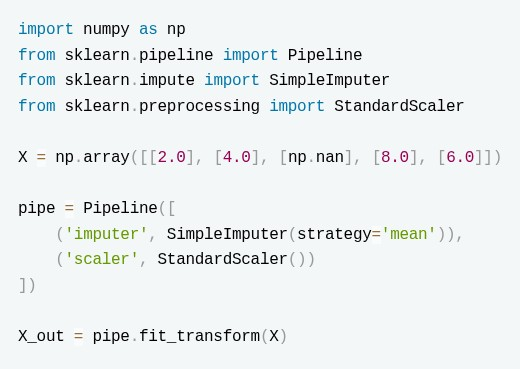
(the transformed value of the first sample, whose original value is 2)? (Enter up to 2 decimals)
Consider a 3 class classification problem where the training dataset contains 10 features. The given model is trained on the dataset. What is the output of the code given below?
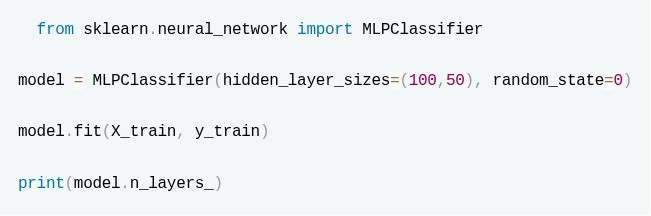
Assume both models in the code given below are fit on the same dataset (X_train) containing 10 features.
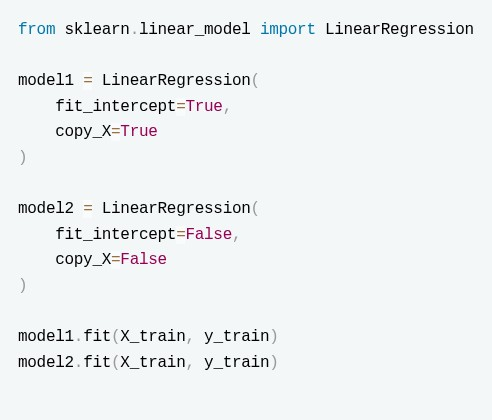 Enter the difference between the total number of learnable parameters in both the models. (Enter the absolute value of the difference)
What is the output of the following code? (Round Upto one decmimal) X = [[0], [1], [2], [3]] y = [0, 0, 1, 1] from sklearn.neighbors import RadiusNeighborsRegressor neigh = RadiusNeighborsRegressor(radius=1.0) neigh.fit(X, y) print(neigh.predict([[1.5]]))
Consider the following feature matrix with one missing entry, imputed using 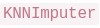 :
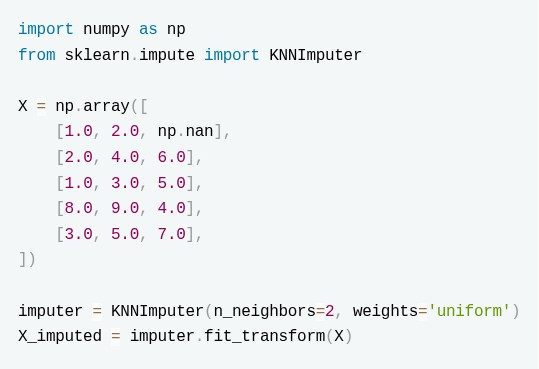 The nearest neighbours are decided using the nan-aware (weighted) Euclidean distance computed over the present coordinates. What is the imputed value at position
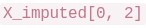 ? (Enter up to 2 decimals)
:
The nearest neighbours are decided using the nan-aware (weighted) Euclidean distance computed over the present coordinates. What is the imputed value at position ? (Enter up to 2 decimals)A binary classification model was evaluated on a test set with 500 samples. The model correctly identified 90 positive samples and 360 negative samples. Out of all the samples predicted as positive, 120 were predicted as positive. There were 100 actual positive samples in the dataset. Compute the F1-score of the model. (Round to 2 decimals)
Select the false statements:
- StandardScaler ensures the features correspond to a uniform distribution after scaling.
- MinMaxScaler ensures that feature values follow a Gaussian Distribution
- OridnalEncoder is best for data which contains values corresponding to a Normal Distribution.
- Pipeline helps us apply separate transformations to numerical and categorical columns directly.
Regarding building pipelines with and  , select all statements that are correct.
and , select all statements that are correct.- Every intermediate step of a must be a transformer, i.e. it must implement both and .
- The final estimator of a only needs to implement .
- requires the user to supply an explicit name for each step, just like .
- A object exposes the interface (e.g.
 ) of its last step.
Consider the following two ensemble regression architectures trained on the same dataset:
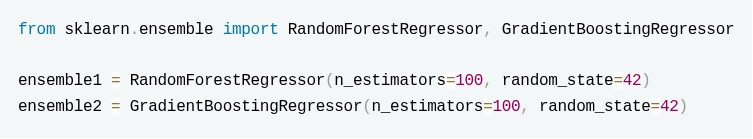 How do these two models differ in their output strategy to produce the final prediction
 for a given test instance, and how does adding more estimators affect them?
How do these two models differ in their output strategy to produce the final prediction for a given test instance, and how does adding more estimators affect them?- ensemble1 computes a weighted sum of predictions where later trees have higher weights; ensemble2 takes a simple arithmetic mean of all trees.
- ensemble1 reduces variance by averaging independent predictions from 100 trees, meaning increasing n_estimators to 500 will ideally not cause overfitting.
- ensemble2 reduces bias sequentially, meaning increasing n_estimators to 500 carries no risk of overfitting.
- Both models output predictions by calculating the majority vote across the terminal leaf nodes of all individual base estimators.
Consider the following code:
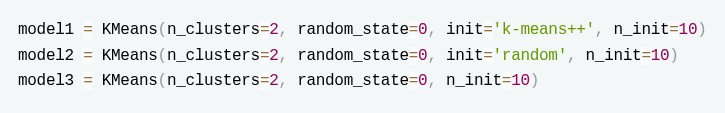 Assuming the all the models are trained on the same dataset, which of the models is likely to converge the slowest?
- model1
- model2
- model3
- code sinppet for model3 is incorrect
A company uses K-Means clustering to divide its customers into 4 groups based on their purchasing behavior. After training the model, the data science team observes the following: Two different runs of K-Means on the same dataset produce different customer groups. One cluster contains customers that are much farther away from their assigned cluster center compared to other clusters. Which of the following statements are most likely to explain these observations?
- K-Means can converge to different solutions because the initial placement of cluster centroids can affect the final clusters.
- The cluster with customers far from its centroid may indicate that the chosen value of K does not represent the natural grouping structure of the data.
- K-Means guarantees finding the globally optimal clustering solution regardless of initialization.
- K-Means assigns clusters by maximizing the distance between points within the same cluster.
Which variant of the Naive Bayes Classifier will be most suitable to predict the Gender in the given dataset?
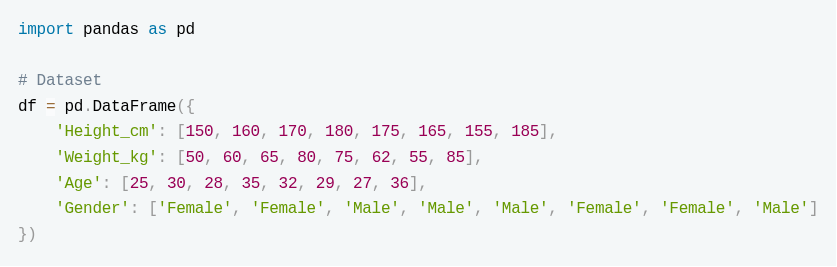
- CategoricalNB
- BernoulliNB
- MultinomialNB
- GaussianNB
Analyze the following code snippet:
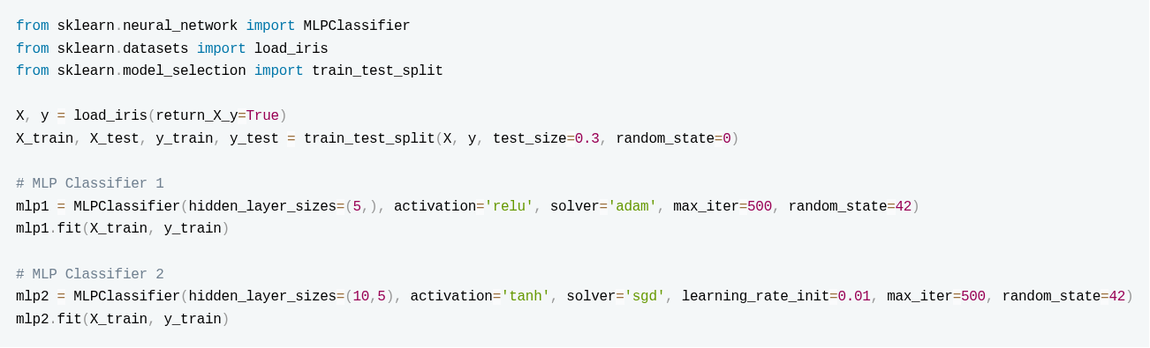 Which of the following statements are correct?
- mlp2 has more trainable parameters than mlp1.
- Changing random_state may change predictions even with the same dataset.
- Using 'sgd' solver always gives higher accuracy than 'adam'.
- 'tanh' activation guarantees better performance than 'relu'.
Select all the false statements amongst the given statements:
- RandomForest uses sampling without replacement for bagging.
- Boosting reduces bias by sequentially training models
- Bagging reduces bias by training multiple models on different subsets of data and averaging their predictions.
- Boosting trains all base models independently in parallel.
Consider the given 2 different lasso regression models trained on the same dataset:
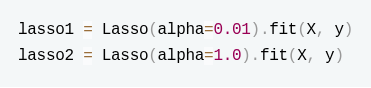 Statements: 1. The coefficients of lasso2 are more likely to be smaller in magnitude than those of lasso1. 2. lasso1 may have fewer zero coefficients than lasso2. 3. The predictions of lasso1 on the training data will exactly match y. 4. Increasing alpha always increases model accuracy on unseen data. Which of the given statements are correct?
- 2 and 3
- 1 and 2
- 3 and 4
- 1 and 4
We create the following ml pipeline:
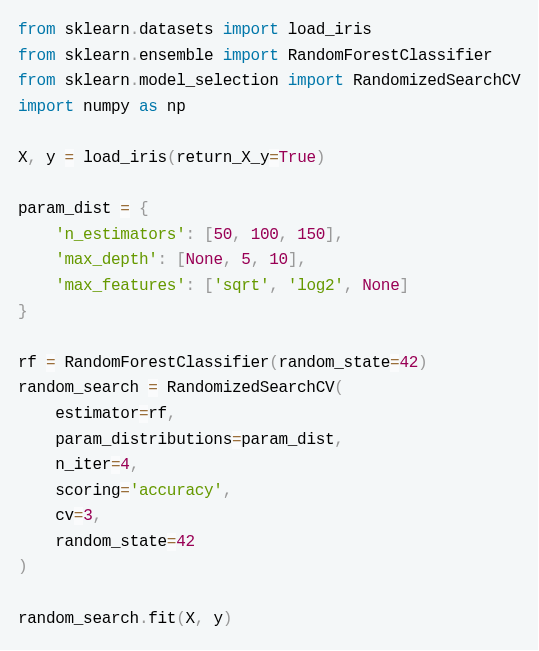 Which of the following statements is true?
- RandomizedSearchCV tries all possible combinations of hyperparameters in param_dist.
- Only 4 random combinations of hyperparameters will be tested.
- Changing random_state has no effect on the hyperparameter search results.
- Changing cv to 8 will be computationally cheaper.
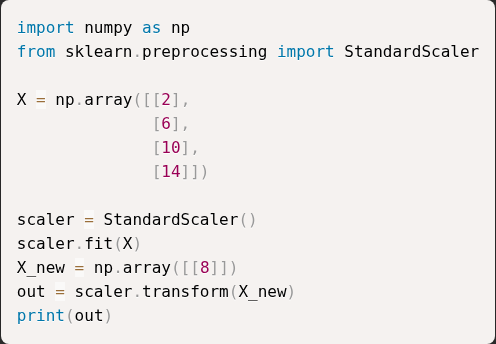
What is the output of the following standard scaler transformation?
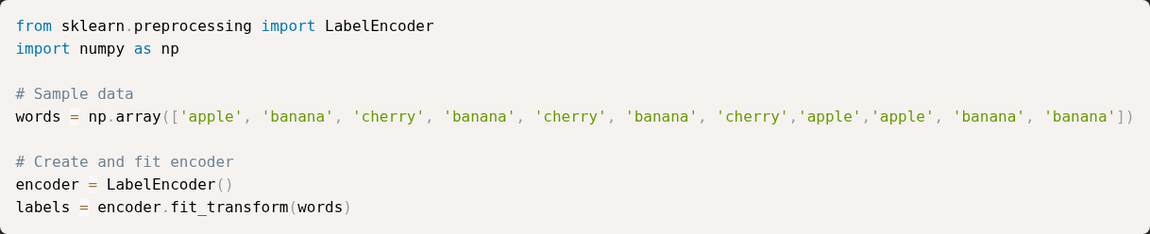
Consider the following data preprocessing code. What are the number of zero(s) in the transformed labels vector after applying label encoding?
Identify the datatypes of the two datasets given below: (Assume all library imports are correctly done)
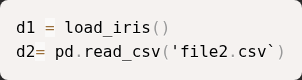
- bunch , bunch
- bunch , dataframe
- dataframe , bunch
- series, dataframe
You are using a ColumnTransformer to preprocess a dataset before training a model:
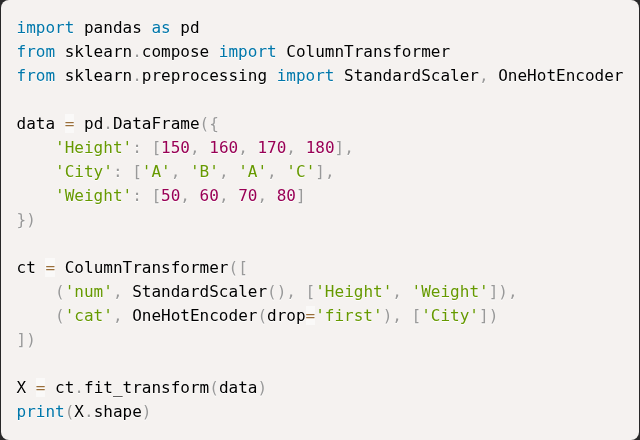 What will be the shape of the transformed matrix X?
- (3,2)
- (4,4)
- (3,4)
- (4,3)
You are given the following dataset and model:
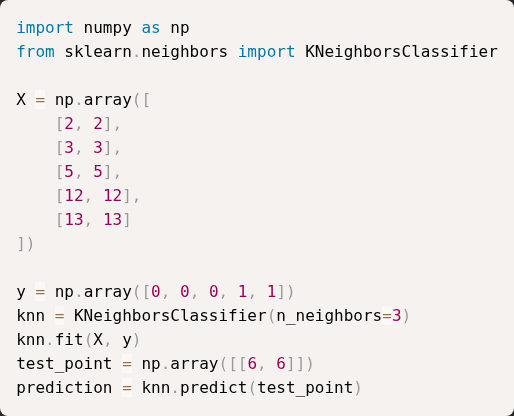 What is the value of prediction after running this code?
Consider the following code snippet. Assume that all required libraries have been imported correctly.
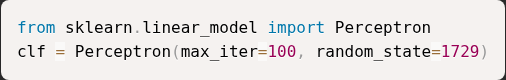 A practitioner observes that each time the fit() method is called on clf, the model is trained from scratch and the parameters learned in the previous training call are discarded. Which of the following changes should be made so that the model continues training from the previously learned parameters when fit() is called again?
- Set warm_start=True
- Combine training data from all training sessions into a single dataset
- Set retain_parameters=True
- This behavior cannot be changed for Perceptron
Consider the following cases for splitting train and test data for some real world dataset.
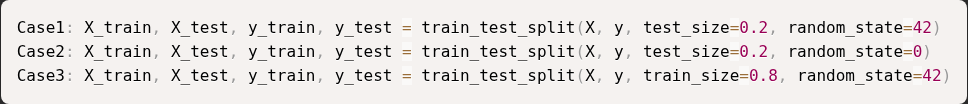 Which of the following hold true?
- The selected samples(rows) in X_train will always be same for all the cases.
- The selected samples(rows) in X_train will always be different for all the cases.
- The selected samples(rows) in X_train will always be different for case 1 and case 2.
- The selected samples(rows) in X_train will always be different for case 1 and case 3.
What does the following pandas code do ?
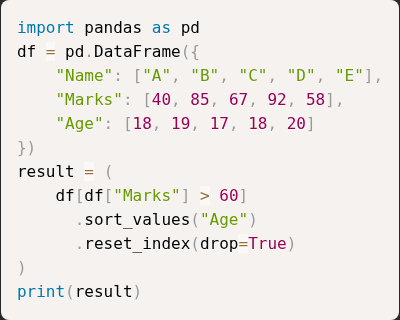
- All rows where Age < 18, sorted by Marks, index unchanged.
- Only rows where Marks > 60, sorted by Age, and index reset.
- All rows sorted first by Marks, then by Age.
- Drops the Age column and sorts remaining data.
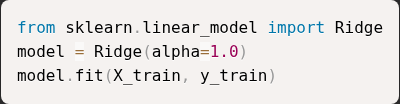
What is the role of the alpha=1.0 parameter in the given sklearn code to build a regression model?
- It applies L1 regularization and sets some coefficients to zero.
- It removes regularization completely and behaves like Linear Regression.
- It adds L2 regularization that penalizes large coefficients to prevent overfitting.
- It makes the model ignore the intercept term.
Consider the following code snippet that trains a Decision Tree classifier using scikit-learn:
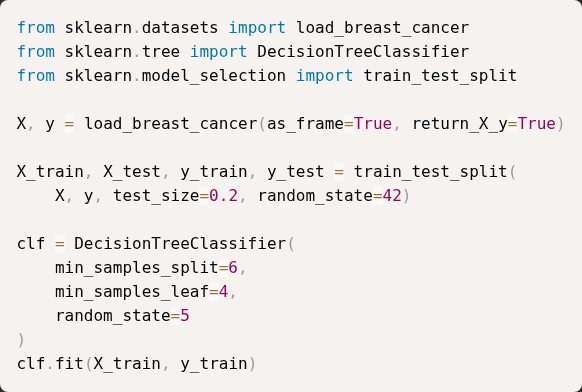 A node in the trained decision tree is split only if both of the following conditions are satisfied: • The node contains at least min_samples_split samples. • Each child node created after the split contains at least min_samples_leaf samples. Assume node (N) is a non-leaf node being considered for splitting. In which of the following cases will the split at node (N) be allowed?
- Node (N) contains 15 samples. After splitting, the left child has 9 samples and the right child has 6 samples.
- Node (N) contains 6 samples. After splitting, the left child has 4 samples and the right child has 2 samples.
- Node (N) contains 12 samples. After splitting, the left child has 3 samples and the right child has 9 samples.
- Node (N) contains 8 samples. After splitting, the left child has 4 samples and the right child has 4 samples.
You are given a dataset where each row represents a customer using two numerical features. You apply K-means clustering with K=3 clusters using the following code:
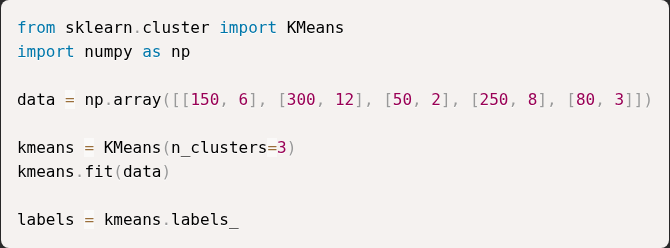 What does the variable labels represent after the model is fitted?
- The values of the input features used for clustering.
- The cluster index assigned to each data point.
- The total number of clusters formed.
- The coordinates of the cluster centroids.
Identify the errors in the following code:
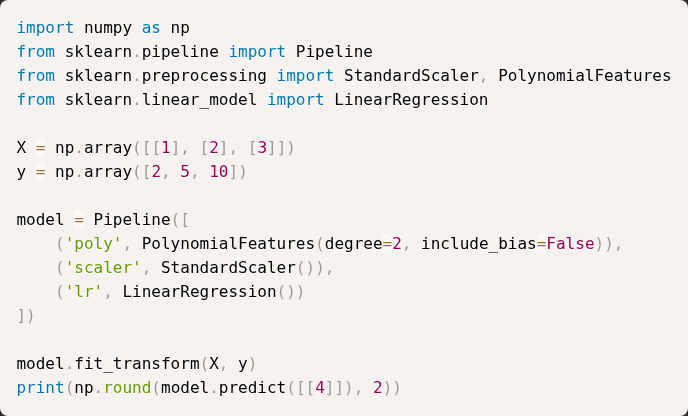
- include_bias has to be kept true for polynomial features.
- MinMaxScalar should be used for simple LinearRegression Models
- model.fit_transform should be replace with model.fit
- model.predict should be replaced with model.predict_proba
You are given the following DataFrame:
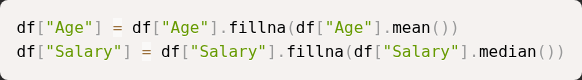
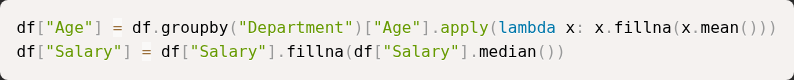
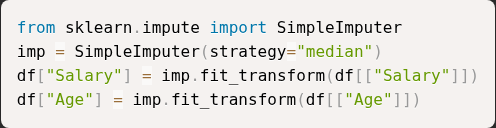
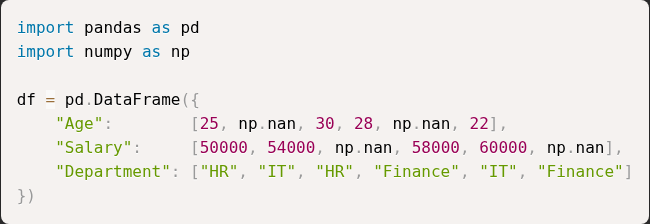 You want to perform the following imputation strategy: • Age → Replace missing values with the mean Age of each Department • Salary → Replace missing values with the median Salary of the entire column • Department → No imputation Which of the following code snippets correctly performs the above imputation?
You are training a RandomForestRegressor on a dataset with 20 features and 10,000 samples. Consider the following code:
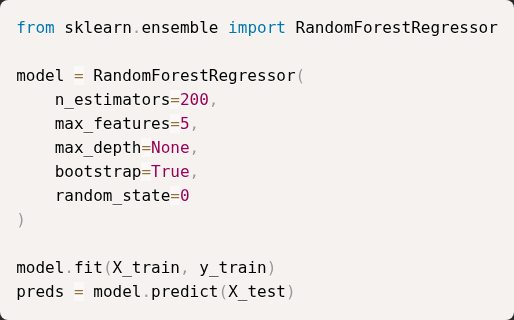 Which of the following statements is TRUE about how this Random Forest model will behave?
- With bootstrap=True, every tree sees the entire dataset, but the samples are shuffled randomly for each tree.
- The forest will use all 20 features for each split, but only 5 trees out of the 200 will be trained on bootstrap samples.
- Setting max_features=5 means only 5 trees out of 200 will use feature subsets, while the rest use all features.
- Each tree will consider only 5 randomly chosen features when looking for the best split at every node.
Select the correctly matched pairs of sklearn functions with the use of fit, fit_transform and transform.
- Learning the weights of logistic regression model on training data - fit_transform
- Creating a decision tree on the training data - fit
- fitting MinMaxScaler on test data - fit_transform
- fitting MinMaxScaler on train data - fit_transform
Given below a y_train list which consists of coffee order's preference by the customers in a cafe.
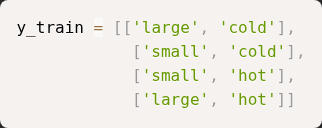 MultiLabelBinarizer from sklearn library has been used to convert the y_train into numbers, so which of the following option matches with the output of the following code ?
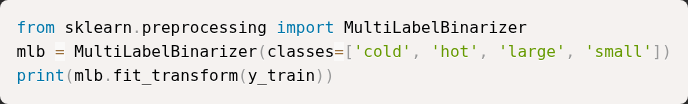
MultiLabelBinarizer from sklearn library has been used to convert the y_train into numbers, so which of the following option matches with the output of the following code ?
- [[1 0 1 0],[1 0 0 1],[0 1 0 1],[0 1 1 0]]
- [[0 0],[1 0],[0 1],[1 1],[1 0],[0 0],[0 0],[0 0]]
- [[1 0 1 0 0 1 0 0],[1 0 0 1 1 0 0 0]]
- [[1 0][1 0],[1 0] [0 1],[0 1] [0 1],[0 1][1 0]]

- Saves computation time by reusing results of expensive transformations wheninputs and parameters have not changed.
- Helps speed up repeated runs of cross-validation involving the sametransformation steps.
- Reduces CPU usage by running transformations in parallel threadsautomatically.
- Improves efficiency in hyperparameter search by avoiding redundantcomputations in pipeline steps.
- Guarantees better generalization performance on the test set.
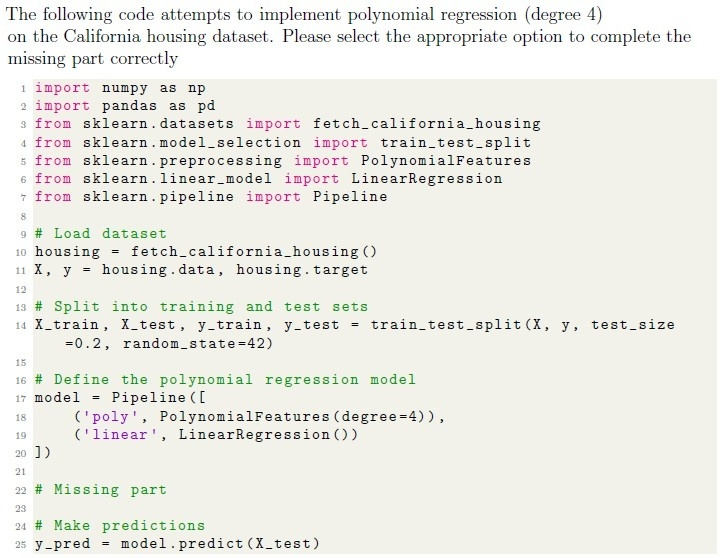
Which of the following correctly fills the missing part blank while ensuring correct preprocessing and avoiding common pitfalls?
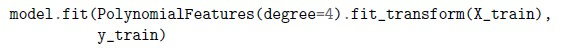
- It can only be used with classifiers that output probabilities.
- When voting=‘hard’, it chooses the class with the highest sum of predictedprobabilities.
- When voting=‘soft’, it averages the predicted probabilities and picks the classwith the highest probability.
- It cannot be used with Pipeline objects.
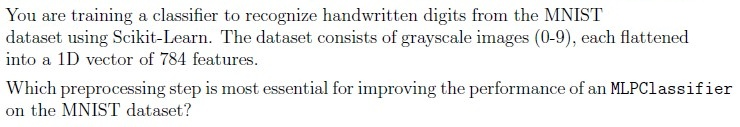
- Convert images to grayscale.
- Scaling the data using Min-Max Scaling
- Apply PCA to reduce feature dimensions.
- One-Hot encode the target labels (digits 0-9)
Comprehension passage for this question
Based on the above data, answer the given subquestions.
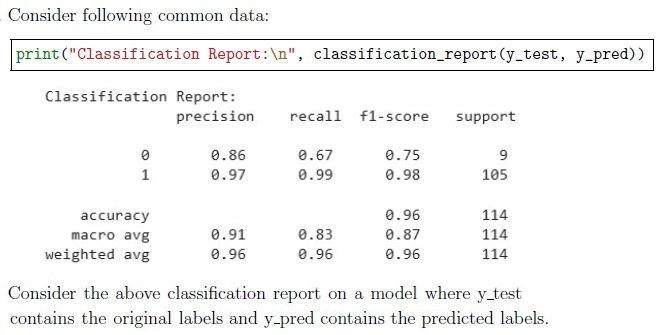
Consider the following assertion & reason and select the correct option:
Assertion: This is a good model as we see a very high accuracy of 96% Reason: In the case of imbalanced datasets, accuracy might not be the best metric for evaluating a model
- Both the assertion and reason are correct, and the reason is a correctexplanation of the assertion
- Both the assertion and reason are correct, but the reason is not a correctexplanation of the assertion.
- The assertion is correct, but the reason is incorrect.
- The assertion is incorrect, but the reason is correct.
Comprehension passage for this question
Based on the above data, answer the given subquestions.
How many points belong to class 1 in the original dataset?
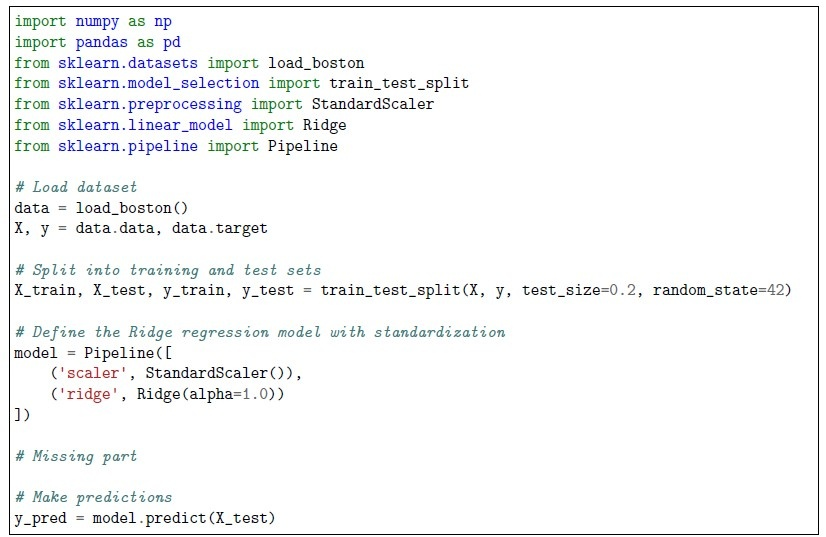
The following code attempts to implement Ridge regression on the Boston housing dataset but contains an error. The missing part should be correctly filled in to avoid issues during training.
 The following code attempts to implement Ridge regression on the Boston housing dataset but contains an error. The missing part should be correctly filled in to avoid issues during training.
Which of the following correctly fills the missing part while ensuring proper preprocessing?
The following code attempts to implement Ridge regression on the Boston housing dataset but contains an error. The missing part should be correctly filled in to avoid issues during training.
Which of the following correctly fills the missing part while ensuring proper preprocessing?
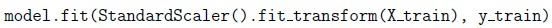
Which of the following techniques can be used for hyperparameter tuning in SGD Regression?
- GridSearchCV
- ElasticNetCV
- SelectKBest
- Feature Scaling with StandardScaler
Comprehension passage for this question
Based on the above data, answer the given subquestions.
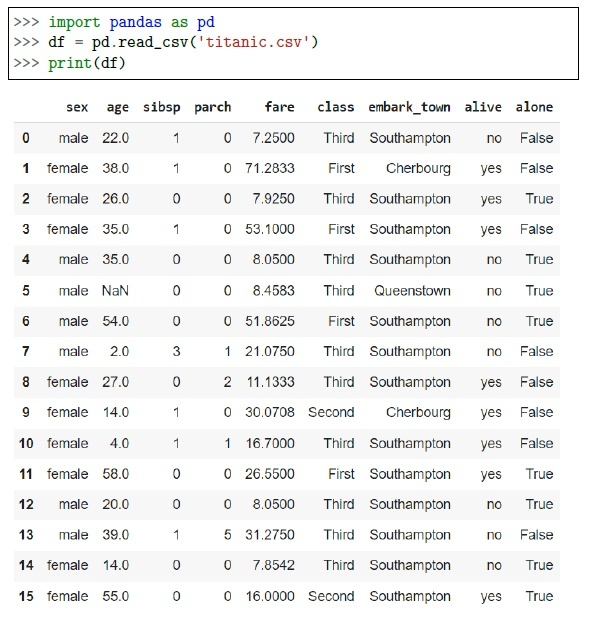
What is the given code below trying to accomplish for the given titanic dataset ?
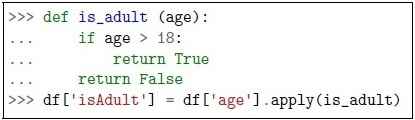 What is the given code below trying to accomplish for the given titanic dataset ?
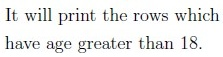
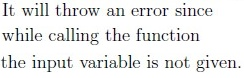
Comprehension passage for this question
Based on the above data, answer the given subquestions.
Consider the following and select the corrrect option:
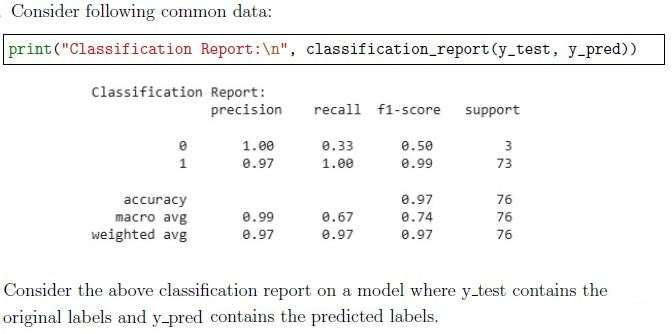
Assertion: This is a good model as we see a very high accuracy of 97% Reason: In the case of imbalanced datasets, accuracy might not be the best metric for evaluating a model
- Both the assertion and reason are correct, and the reason is a correctexplanation of the assertion
- Both the assertion and reason are correct, but the reason is not a correctexplanation of the assertion.
- The assertion is correct, but the reason is incorrect.
- The assertion is incorrect, but the reason is correct.
What is the primary risk of not performing a train-test split in a machine learning workflow?
- The training time will increase.
- The model might overfit the training data and perform poorly on new data.
- The dataset may become unbalanced.
- The model may fail to converge.
Why is data preprocessing necessary before using it for model building?
- The data may contain outliers or missing values due to errors in datacollection.
- Features may have different scales, affecting model performance.
- The dataset may include non-numerical features that need to be converted tonumerical representations.
- All of these
Suppose we want to transform features in a dataset using polynomial transformation. The sklearn API provides the functionality in which of the following modules?
- sklearn.dataset
- sklearn.model_selection
- sklearn.preprocessing
- sklearn.featureSelection
- sklearn.featureExtraction
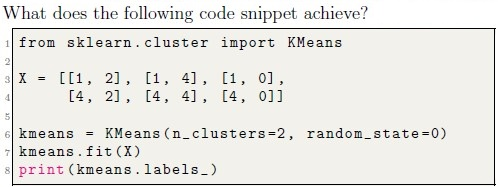
- Performs hierarchical clustering and outputs cluster distances.
- Outputs the silhouette score for the data points.
- Groups data points into 2 clusters and outputs the labels of the clusters foreach data point.
- Reduces the dimensionality of the dataset to 2 dimensions.