Home / Past papers / MLP Quiz 1 / this paper
IIT M IMPROVEMENT AN EXAM QIP4 23 Feb - 23 Feb 2025
- The training time will increase.
- The model might overfit the training data and perform poorly on new data.
- The dataset may become unbalanced.
- The model may fail to converge.
- The data may contain outliers or missing values due to errors in datacollection.
- Features may have different scales, affecting model performance.
- The dataset may include non-numerical features that need to be converted tonumerical representations.
- All of these
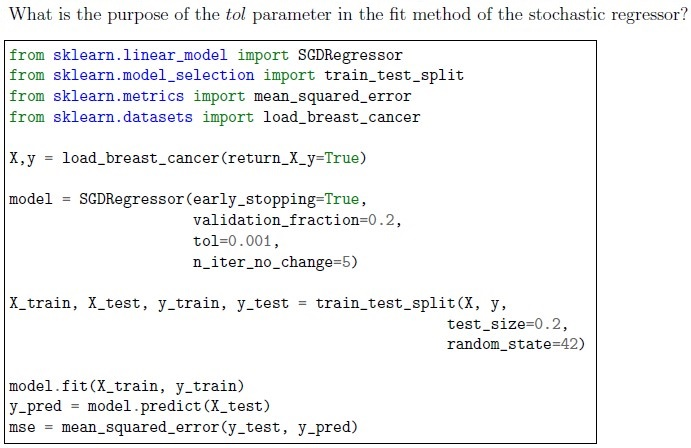
- It specifies the tolerance level for early stopping based on the change in thevalidation error.
- It controls the learning rate of the stochastic regressor during training.
- It determines the maximum number of iterations for the training process.
- It defines the fraction of the validation set used for early stopping.
- sklearn.dataset
- sklearn.model_selection
- sklearn.preprocessing
- sklearn.featureSelection
- sklearn.featureExtraction
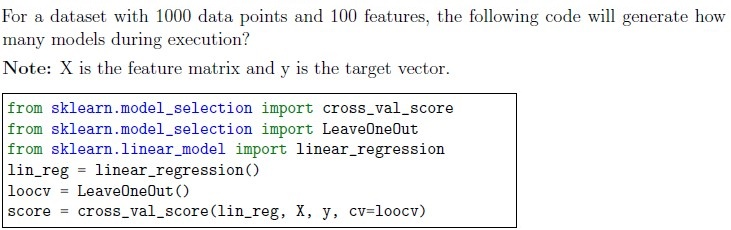
- 1000
- 100
- 99
- 999


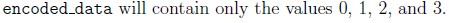
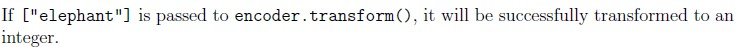
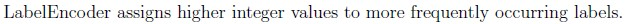
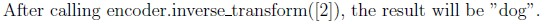
- Mean Squared Error
- Accuracy
- F1-Score
- Mean Absolute Error
- credit score
- CGPA
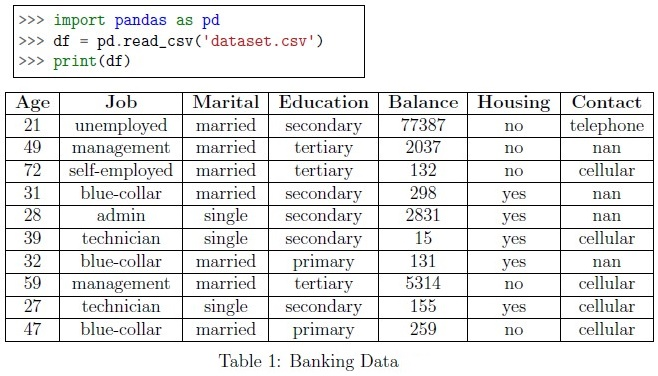 Consider the given Table 1: Banking data for the given subquestions stored as pandas dataframe in variable df
Based on the above data, answer the given subquestions.
- Job
- Marital
- Education
- Housing
- Contact
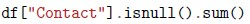
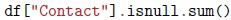
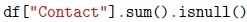
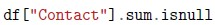
- Mean
- Median
- Mode
- Variance
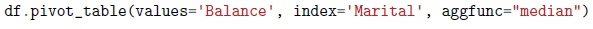
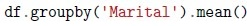
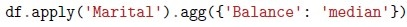
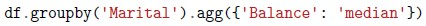
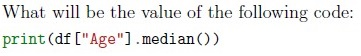
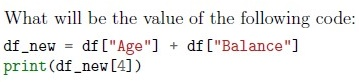
- secondary
- 329
- 2859
- Error: Datatype not matching
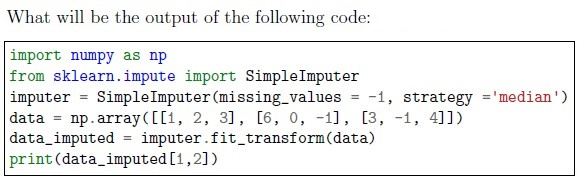
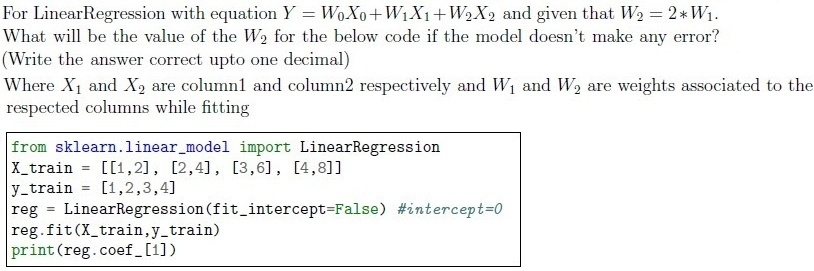
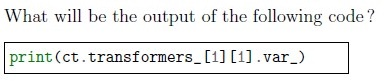
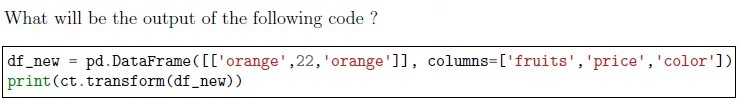
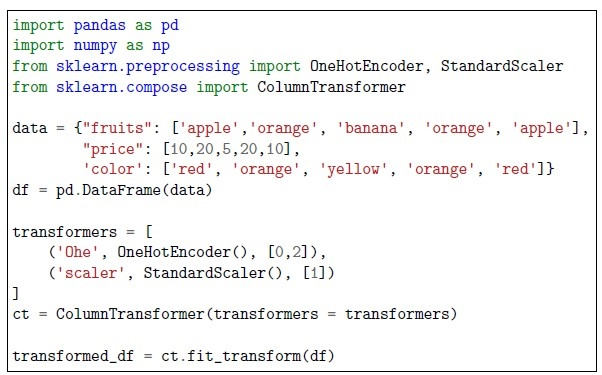 Consider the Following codeblock for the given subquestions.
Based on the above data, answer the given subquestions.
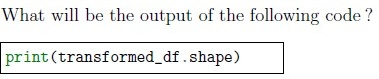
- (7,5)
- (3,5)
- (5,3)
- (5,7)
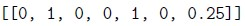
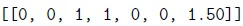
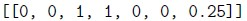
Answer key
- Q1 (MCQ, 2 marks): B
- Q2 (MCQ, 2 marks): D
- Q3 (MCQ, 2 marks): A
- Q4 (MCQ, 2 marks): C
- Q5 (MCQ, 3 marks): A
- Q6 (MCQ, 3 marks): B
- Q7 (MSQ, 2 marks): A, D
- Q8 (MSQ, 2 marks): A, D
- Q9 (SA, 2 marks): 3.5
- Q10 (SA, 3 marks): 0.4
- Q11 (MSQ, 2 marks): A, B, D, E
- Q12 (MCQ, 2 marks): A
- Q13 (MCQ, 2 marks): C
- Q14 (MSQ, 2 marks): A, D
- Q15 (SA, 1 marks): 35.5
- Q16 (MCQ, 1 marks): C
- Q17 (MCQ, 2 marks): D
- Q18 (SA, 1 marks): 13
- Q19 (SA, 2 marks): 36
- Q20 (MCQ, 2 marks): D
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
1. Machine Learning Workflow
Train-Test Split: Essential to avoid overfitting and evaluate model performance on unseen data.
- Risk of not performing train-test split: Model might overfit the training data and perform poorly on new data.
Data Preprocessing: Necessary for cleaning and preparing data for model building.
Reasons for preprocessing:
- Handling outliers or missing values.
- Scaling features.
- Converting non-numerical features to numerical representations.
2. Model Evaluation and Optimization
Tolerance Parameter (
tol): Used in optimization algorithms to specify the threshold for stopping criterion.- Equation: If the change in loss or parameters is less than
tol, the optimization stops. - Example:
SGDRegressor(tol=0.001)
- Equation: If the change in loss or parameters is less than
Cross-Validation: Techniques like Leave-One-Out Cross-Validation (LOOCV) for robust model evaluation.
- LOOCV: Generates
nmodels forndata points, leaving one out each time.
- LOOCV: Generates
3. Data Transformation
Polynomial Transformation: Used to create polynomial features.
- Module:
sklearn.preprocessing
- Module:
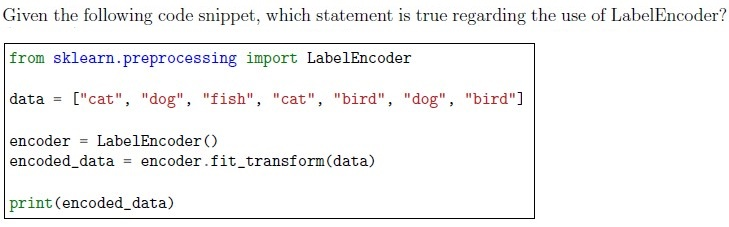
Label Encoding: Converting categorical data into numerical codes.
- Example:
LabelEncoder().fit_transform(data)
- Example:
4. Evaluation Metrics
Regression Metrics:
- Mean Squared Error (MSE):
- Mean Absolute Error (MAE):
5. Handling Missing Data
Imputation: Techniques to handle missing values.
- Example:
SimpleImputer(strategy='median')
- Example:
6. Statistical Measures
Median: Used to replace missing values in categorical data.
- Example:
df["Contact"].median()
- Example:
7. Data Manipulation and Analysis
Pandas Operations: Techniques for data manipulation and analysis.
- Example:
df.groupby('Marital').agg({'Balance': 'median'})
- Example:
8. Data Transformation Pipelines
ColumnTransformer: Used to apply different transformations to different columns.
Example:
transformers = [
    ('Ohe', OneHotEncoder(), [0, 2]),
    ('scaler', StandardScaler(), [1])
]
ct = ColumnTransformer(transformers=transformers)