Home / Past papers / MLT End Term / this paper
IIT M DEGREE AN EXAM QDB4 31 Aug 2025 - 31 Aug 2025
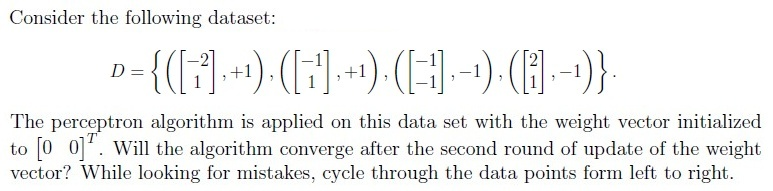
- Yes
- No
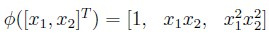
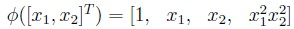
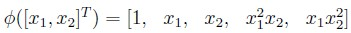
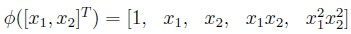
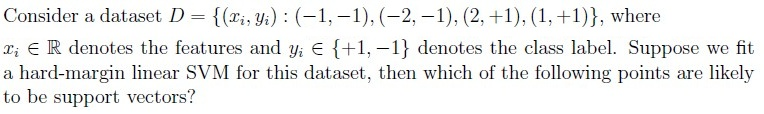
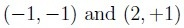
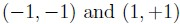
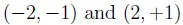
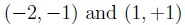
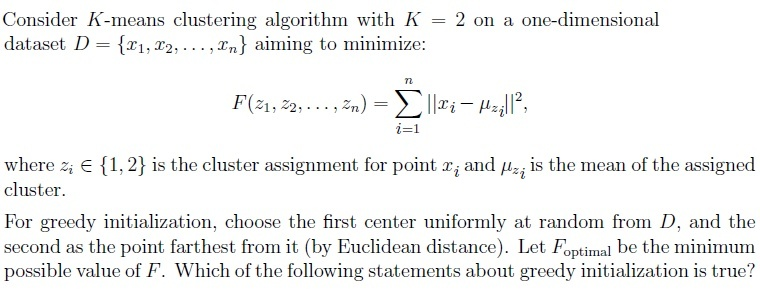
- Greedy initialization always achieves F = Foptimal by maximizing the distancebetween initial centers.
- Greedy initialization may achieve F = Foptimal or a larger value depending onthe dataset and the initial choice.
- Greedy initialization does not ensure convergence for K-means clustering.
- Greedy initialization ensures convergence to a unique solution for any dataset.
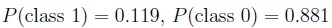
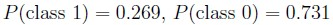
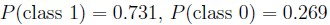
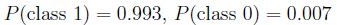
- Decision trees are prone to overfitting if the maximum depth is set tooshallow.
- Decision trees are not affected by the order of features in the dataset.
- Decision trees are sensitive to small perturbations in the dataset and canresult in different tree structures.
- Decision trees can handle both numerical and categorical features.
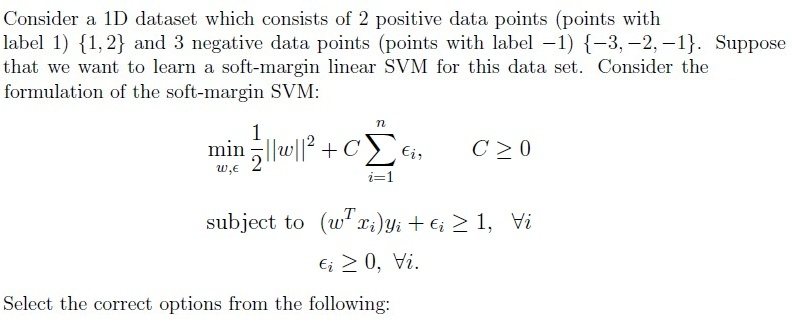
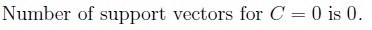
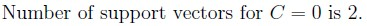
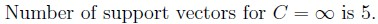
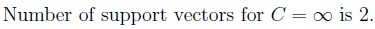
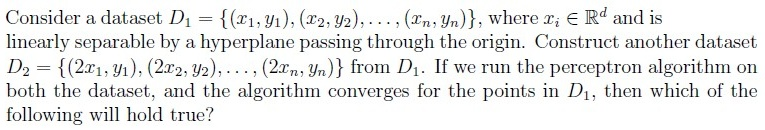
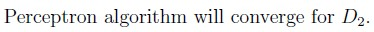
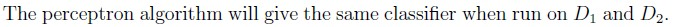
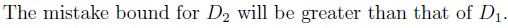
- The given data points from classes 1 and 0 can be linearly separated using ahard-margin SVM.
- A perceptron model and a hard-margin SVM can give different decisionboundary for this dataset.
- A soft-margin SVM would be a more robust choice than a hard-margin SVM forthis dataset as the dataset is not linearly separable.
- The width of the separation between the two supporting hyperplanes is 4.
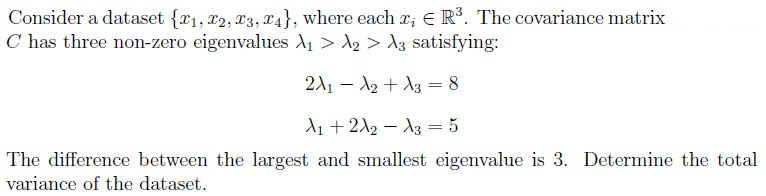
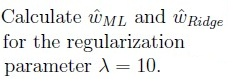
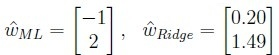
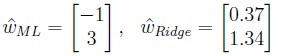
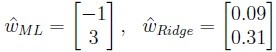
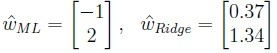
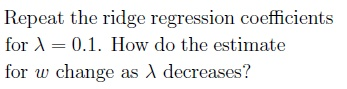
- The coefficients shrinks towards zero.
- The coefficients increases in magnitude.
- The coefficients remain unchanged.
Answer key
- Q1 (MCQ, 3 marks): B
- Q2 (MCQ, 3 marks): C
- Q3 (MCQ, 2 marks): B
- Q4 (MCQ, 2 marks): B
- Q5 (MCQ, 4 marks): D
- Q6 (MSQ, 3 marks): C, D
- Q7 (MSQ, 3 marks): A, D
- Q8 (MSQ, 3 marks): A, B
- Q9 (MSQ, 4 marks): A, B
- Q10 (SA, 3 marks): 6
- Q11 (SA, 3 marks): 1.10 to 1.14
- Q12 (SA, 3 marks): 1
- Q13 (SA, 4 marks): 0.28 to 0.34
- Q14 (MCQ, 4 marks): C
- Q15 (MCQ, 2 marks): B
- Q16 (SA, 1 marks): 7
- Q17 (SA, 3 marks): 0.0625
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of the core topics, concepts, principles, and equations essential for the Diploma Level: Machine Learning Techniques exam, along with Mermaid knowledge graphs to visualize relationships.
1. Core Topics & Concepts
A. Supervised Learning
Perceptron Algorithm
- Concept: Linear classifier for binary classification. Updates weights iteratively if misclassification occurs.
Key Equation:
- Update rule: (if ).
- Convergence: Guaranteed if data is linearly separable (Novikoff’s theorem).
- Example: Question 2 (convergence analysis), Question 9 (scaling data).
Support Vector Machines (SVM)
- Concept: Maximizes the margin between classes. Hard-margin (no misclassification) vs. soft-margin (allows slack variables ).
Key Equations:
- Hard-margin: s.t. .
- Soft-margin: s.t. .
- Kernel trick: .
- Example: Question 3 (kernel transformation), Question 4 (support vectors), Question 8 (soft-margin SVM), Question 10 (decision boundary).
Logistic Regression
- Concept: Probabilistic classifier using sigmoid activation.
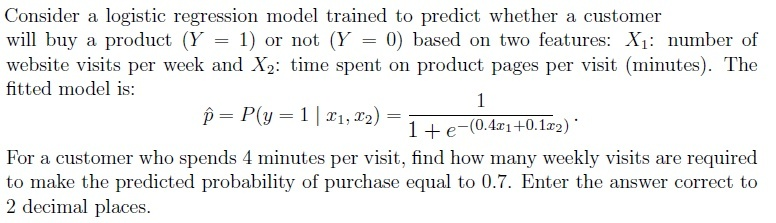
Key Equation:
- .
- Example: Question 12 (probability threshold).
Neural Networks
- Concept: Multi-layer perceptron (MLP) with activation functions (ReLU, sigmoid).
Key Equations:
- Forward pass: , .
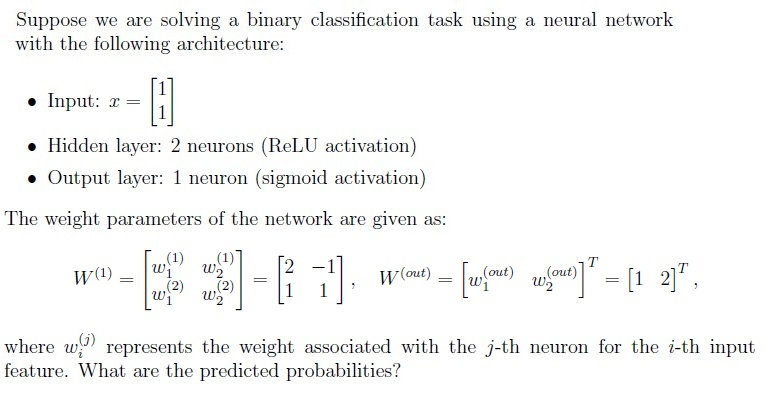
- Example: Question 6 (probability prediction).
Linear Regression & Ridge Regression
- Concept: Fits a linear model to data. Ridge adds L2 regularization.
Key Equations:
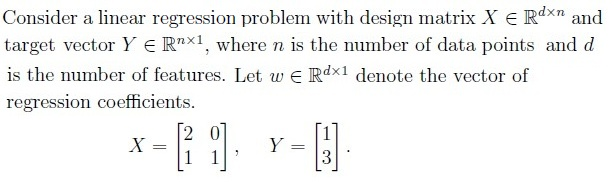
- OLS: .
- Ridge: .
- Example: Question 15 (coefficient calculation), Question 16 (effect of ).
B. Unsupervised Learning
K-Means Clustering
- Concept: Partitions data into clusters by minimizing within-cluster variance.
Key Equation:
- Objective: .
- Example: Question 5 (greedy initialization).
Principal Component Analysis (PCA)
- Concept: Dimensionality reduction via eigen decomposition of covariance matrix.
Key Equation:
- Covariance matrix: .
- Total variance: .
- Example: Question 11 (eigenvalues and variance).
C. Probabilistic Models
Naive Bayes
- Concept: Assumes feature independence given the class. Uses MLE for parameter estimation.
Key Equation:
- .
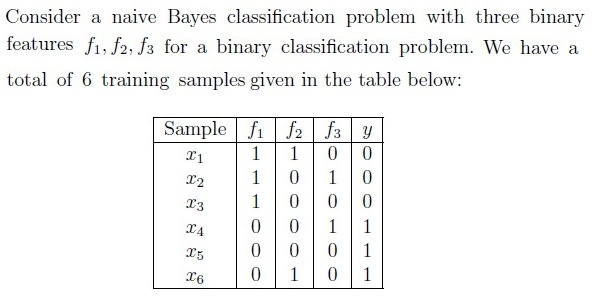
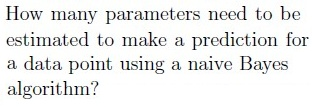
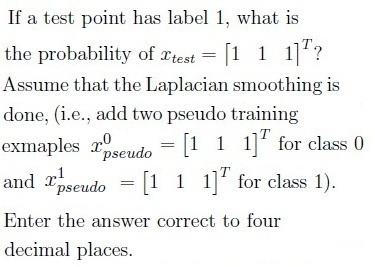
- Example: Question 17 (parameter counting), Question 18 (prediction with Laplace smoothing).
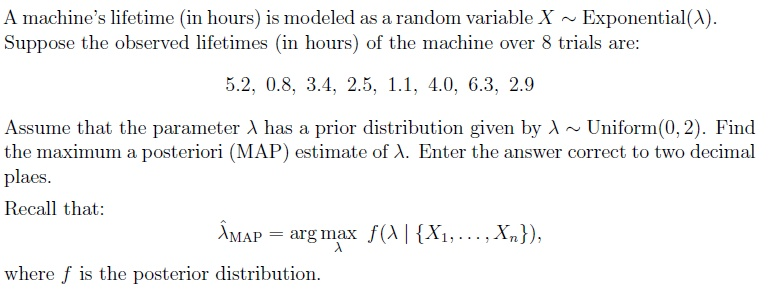
Maximum A Posteriori (MAP) Estimation
- Concept: Bayesian parameter estimation with a prior.
Key Equation:
- .
- Example: Question 14 (exponential distribution with uniform prior).
D. Ensemble Methods
Random Forest
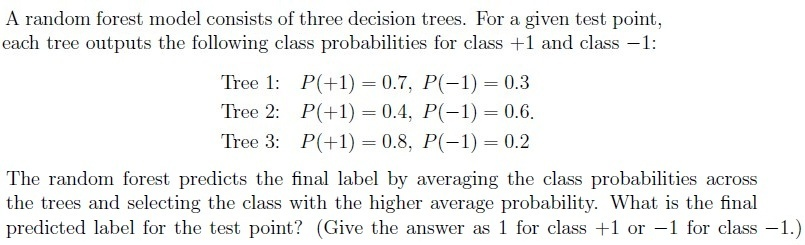
- Concept: Aggregates predictions from multiple decision trees via averaging (regression) or voting (classification).
- Example: Question 13 (probability averaging).
E. Decision Trees
Decision Tree Algorithm
- Concept: Recursively splits data based on feature thresholds. Prone to overfitting if unconstrained.
Key Points:
- Handles numerical/categorical features.
- Sensitive to data perturbations.
- Example: Question 7 (properties of decision trees).
2. Key Equations Summary
| Topic | Equation | Notes |
|---|---|---|
| Perceptron Update | (if misclassified) | Converges if linearly separable. |
| SVM (Hard-Margin) | s.t. | Support vectors lie on margin. |
| SVM (Soft-Margin) | s.t. | : Trade-off between margin and error. |
| Logistic Regression | Sigmoid activation. | |
| Kernel Trick | Enables non-linear decision boundaries. | |
| K-Means Objective | NP-hard; sensitive to initialization. | |
| Ridge Regression | : Regularization strength. | |
| Naive Bayes | Assumes conditional independence. | |
| MAP Estimation | Combines likelihood and prior. | |
| PCA Total Variance | : Eigenvalues of covariance. |
Graph 2: Unsupervised Learning & Probabilistic Models
Graph 3: Ensemble Methods & Decision Trees
Graph 4: Key Equations Flow
4. Exam-Specific Tips
Perceptron/SVM:
- For convergence (Question 2), cycle through data points and update weights manually.
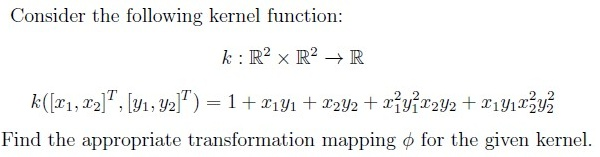
- For kernels (Question 3), match terms in to .
- Support vectors (Question 4) are points where .
K-Means:
- Greedy initialization (Question 5) does not guarantee optimality but can achieve depending on data.
Neural Networks:
- Compute hidden layer outputs step-by-step (Question 6). ReLU: ; Sigmoid: .
Decision Trees:
- Overfitting (Question 7) is controlled by max depth/pruning. Trees handle mixed feature types.
Probabilistic Models:
- For Naive Bayes (Questions 17–18), count parameters as (where = features, = classes).
- MAP estimation (Question 14) for exponential distribution: .
Regression:
- Ridge regression (Questions 15–16): As , coefficients approach OLS solution.
PCA:
- Total variance (Question 11) is the sum of eigenvalues. Solve the system of equations for .