Home / Past papers / MLT End Term / this paper
IIT M FOUNDATION FN EXAM QDF1 13 Apr - 13 Apr 2025
Elapsed 00:00
For a given dataset, a 1-Nearest Neighbor (1-NN) and a 3-Nearest Neighbor (3-NN) classifier are applied. Which classifier is likely to exhibit a higher Leave-One-Out Cross Validation (LOOCV) error? In case of tie-breaker, assign a positive class (+) to the data point.
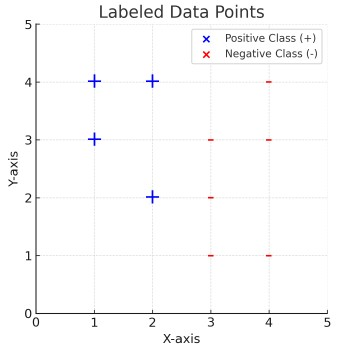 For a given dataset, a 1-Nearest Neighbor (1-NN) and a 3-Nearest Neighbor (3-NN) classifier are applied. Which classifier is likely to exhibit a higher Leave-One-Out Cross Validation (LOOCV) error? In case of tie-breaker, assign a positive class (+) to the data point.
- 1-NN
- 3-NN
- Both have the same error.
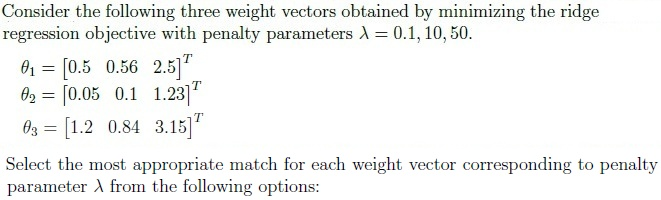
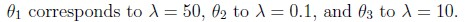
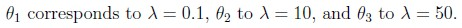
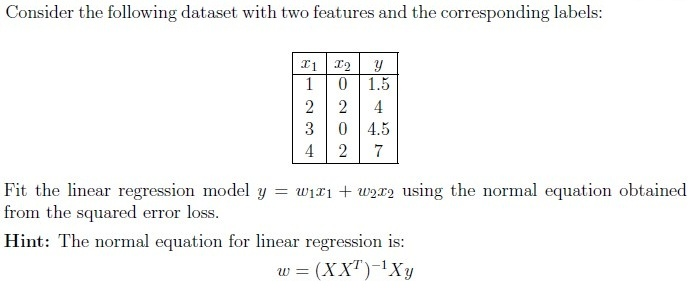
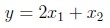
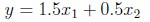
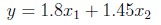
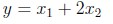
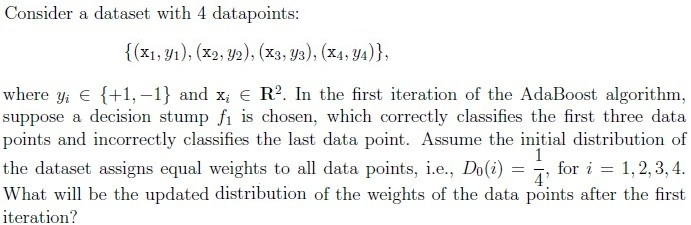
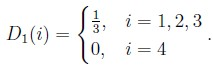
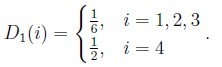
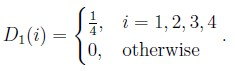
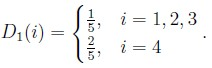
Which of the following statements correctly differentiates PCA and Kernel PCA?
- PCA maximizes variance in the original feature space, while Kernel PCAmaximizes variance in a higher-dimensional transformed space.
- PCA finds principal components using linear transformations in the originalspace, while Kernel PCA uses non-linear transformations to find principal components in a higher-dimensional space.
- Kernel PCA can capture non-linear patterns in data, making it useful when PCAfails to represent complex structures in a linear space.
- PCA and Kernel PCA always yield identical results regardless of the datasetstructure.
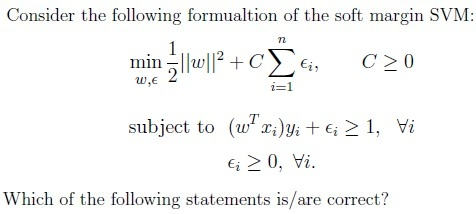
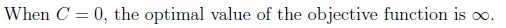
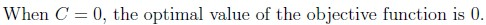
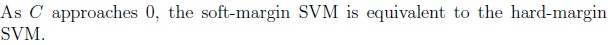
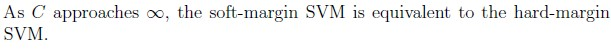
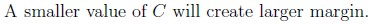
Which of the following statements are true for bagging?
- The final model has lesser variance than the individual learners.
- The final model has a higher variance than the individual learners.
- Estimators in bagging can be trained parallely.
- If the number of data points is large, typically two-third of the data pointsremain unselected in bags.
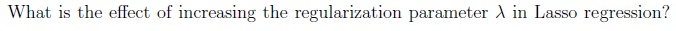
- It penalizes large coefficients to reduce overfitting.
- It shrinks the coefficients but does not set them to zero.
- It forces more coefficients to be exactly zero, performing feature selection.
- It has no effect on the regression model.
For a decision tree, each node has exactly two child nodes (balanced tree). If the tree has a depth of 3, how many leaf nodes are there?
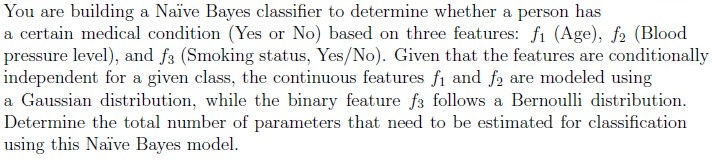
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
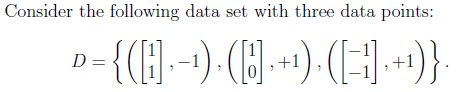
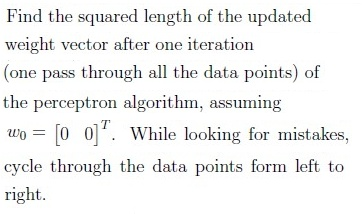
Will the algorithm converge after this update?
- YES
- NO
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
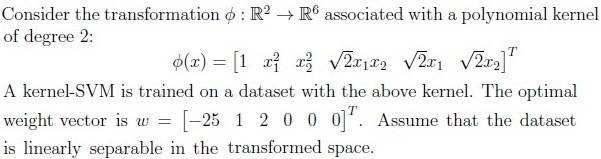
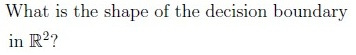
- It is a circle.
- It is a straight line.
- It is an ellipse.
- It is a parabola.
Which of the following training data points are certainly not support vectors?


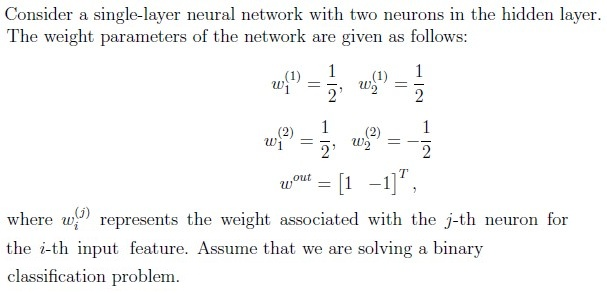
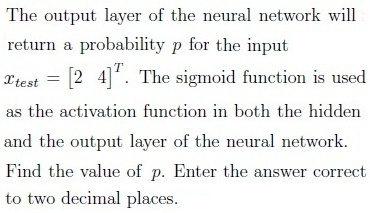
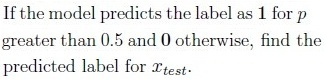
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
Answer key
- Q1 (MCQ, 3 marks): A
- Q2 (MCQ, 3 marks): C
- Q3 (MCQ, 4 marks): B
- Q4 (MCQ, 4 marks): B
- Q5 (MSQ, 3 marks): A, B, C
- Q6 (MSQ, 3 marks): B, D, E
- Q7 (MSQ, 2 marks): A, C
- Q8 (MSQ, 2 marks): A, C
- Q9 (SA, 2 marks): 8
- Q10 (SA, 3 marks): 24
- Q11 (SA, 3 marks): 20
- Q12 (SA, 3 marks): 11
- Q13 (SA, 3 marks): 1
- Q14 (MCQ, 2 marks): A
- Q15 (MCQ, 2 marks): C
- Q16 (MSQ, 3 marks): A, C
- Q17 (SA, 3 marks): 0.64 to 0.68
- Q18 (SA, 2 marks): 1
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations for the Diploma-Level Machine Learning Techniques Exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Key Concepts
1. Supervised Learning
A. k-Nearest Neighbors (k-NN)
- Concept: Classifies a data point based on the majority class of its k nearest neighbors.
Key Points:
- 1-NN: High variance (overfits), sensitive to noise.
- Higher k (e.g., 3-NN): Smoother decision boundaries, lower variance, but may underfit.
- Leave-One-Out Cross-Validation (LOOCV): Evaluates model by leaving one data point out as validation.
- Tie-Breaker: Default to positive class (+) if votes are tied.
Equation:
- Distance metric (Euclidean):
B. Linear Regression
- Concept: Models the relationship between features (X) and target (y) as a linear equation.
Key Points:
- Normal Equation: Closed-form solution for weights (w).
- Assumptions: Linear relationship, no multicollinearity, homoscedasticity.
Equations:
- Model:
- Normal Equation (for squared error loss):
- Ridge Regression (L2 Regularization):
Effect of λ:
- High λ: Shrinks coefficients toward zero (underfitting).
- Low λ: Coefficients remain large (overfitting).
C. Logistic Regression & Perceptron
Perceptron Algorithm:
- Update Rule (for misclassified point):
- Convergence: Guaranteed if data is linearly separable.
D. Support Vector Machines (SVM)
- Concept: Finds the hyperplane maximizing the margin between classes.
Key Points:
- Hard-Margin SVM: No misclassifications allowed.
- Soft-Margin SVM: Allows misclassifications via slack variables (ξ).
- Kernel Trick: Transforms data into higher dimensions for non-linear separation.
Equations:
- Primal Problem (Soft-Margin):
Subject to:
Effect of C:
- High C: Strict margin (hard-margin-like).
- Low C: Wider margin (more misclassifications allowed).
E. AdaBoost
- Concept: Ensemble method that combines weak learners (e.g., decision stumps) into a strong classifier.
Key Points:
- Weight Update: Increases weights for misclassified points.
- Error Calculation:
- Weight Update Rule:
where .
2. Unsupervised Learning
A. K-Means Clustering
- Concept: Partitions data into K clusters by minimizing within-cluster variance.
Key Points:
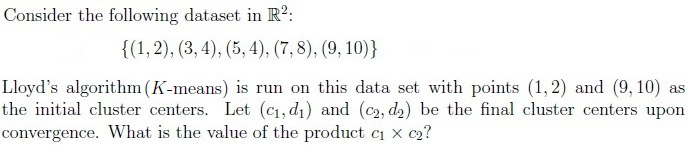
Lloyd’s Algorithm:
- Initialize centroids.
- Assign points to nearest centroid.
- Recompute centroids.
- Repeat until convergence.
- Sensitive to Initialization: Use k-means++ for better centroids.
B. Principal Component Analysis (PCA) & Kernel PCA
PCA:
- Concept: Linear dimensionality reduction by maximizing variance.
Steps:
- Standardize data.
- Compute covariance matrix.
- Eigenvalue decomposition.
- Project data onto top k eigenvectors.
Kernel PCA:
- Concept: Non-linear PCA using kernel functions (e.g., polynomial, RBF).
- Key Point: Works in higher-dimensional feature space.
3. Ensemble Methods
A. Bagging (Bootstrap Aggregating)
- Concept: Reduces variance by averaging multiple models trained on bootstrapped samples.
Key Points:
- Parallel Training: Models are independent.
- Example: Random Forest (bagging + decision trees).
- Out-of-Bag (OOB) Error: Estimates generalization error.
B. Boosting (AdaBoost, Gradient Boosting)
- Concept: Sequentially corrects errors of previous models.
Key Points:
- AdaBoost: Focuses on misclassified points.
- Gradient Boosting: Fits residual errors.
4. Neural Networks
- Concept: Computational graph with layers of neurons.
Key Points:
- Activation Functions: Sigmoid, ReLU, tanh.
- Forward Propagation:
- Backpropagation: Computes gradients via chain rule.
5. Probabilistic Models
A. Naïve Bayes
- Concept: Classifies using Bayes’ theorem with feature independence assumption.
Key Points:
- Gaussian Naïve Bayes: Continuous features modeled as normal distributions.
- Bernoulli Naïve Bayes: Binary features.
Parameters to Estimate:
- For Gaussian: Mean (μ) and variance (σ²) per class per feature.
- For Bernoulli: Probability (p) per class per feature.
- Class priors (P(y)).
B. Maximum Likelihood Estimation (MLE)
- Concept: Estimates parameters by maximizing the likelihood function.
Example (Uniform Distribution):
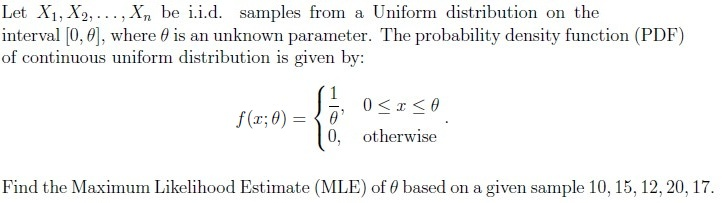
- PDF:
- MLE for θ: .
6. Model Evaluation & Regularization
A. Bias-Variance Tradeoff
- Bias: Error due to overly simplistic model (underfitting).
- Variance: Error due to overly complex model (overfitting).
Regularization:
- L1 (Lasso): Penalizes absolute coefficients (sparse solutions).
- L2 (Ridge): Penalizes squared coefficients (smooth solutions).
B. Cross-Validation
- LOOCV: Special case of k-fold CV where k = n (number of samples).
7. Decision Trees
- Concept: Recursively splits data based on feature thresholds.
Key Points:
- Entropy/Information Gain: Measures split quality.
- Pruning: Reduces overfitting.
- Leaf Nodes: In a balanced binary tree of depth d, number of leaves = 2^d.
Graph 2: Unsupervised Learning & Ensemble Methods
Graph 3: Probabilistic Models & Neural Networks
Graph 4: Model Evaluation & Regularization
Key Equations Summary
| Topic | Equation |
|---|---|
| Linear Regression | |
| Ridge Regression | |
| Perceptron Update | |
| SVM (Soft-Margin) | |
| AdaBoost Weight Update | |
| Gaussian Naïve Bayes | |
| MLE (Uniform Dist.) | |
| K-Means Objective | |
| PCA | |
| Kernel PCA | (e.g., polynomial kernel) |