Home / Past papers / MLT Quiz 1 / this paper
IIT M IMPROVEMENT AN EXAM QIM2 26 Oct - 26 Oct 2025
Elapsed 00:00
Which among the following is true with respect to the Lloyds’ algorithm?
- It always converges.
- It may fail to converge for an initialization while it may converge for otherinitialization.
- It is sensitive to outliers.
- The solution produced is always the optimal.

- There will be 50 non-zero eigenvalues of the covariance matrix.
- There will be 6 non-zero eigenvalues of the covariance matrix.
- Using the first 5 principal components, the dataset can be reconstructed withzero residue.
- The variance captured by the top 6 principal components equals the totalvariance of the dataset.
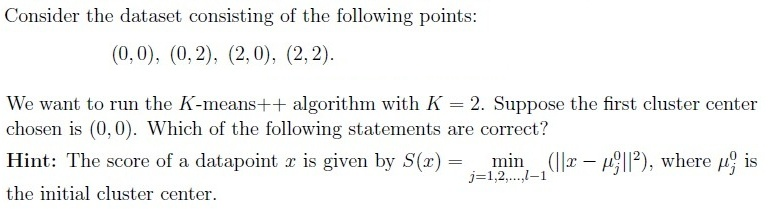
- The points (0, 2), (2, 0), and (2, 2) have the equal probability of being chosen asthe second cluster center.
- The probability of selecting (2, 2) as the second cluster center is twice that ofselecting (0, 2).
- If (2, 2) is chosen as the second cluster center, the algorithm will alwaysconverge in one iteration.
- The tie-breaking rule will affect the final cluster centers.
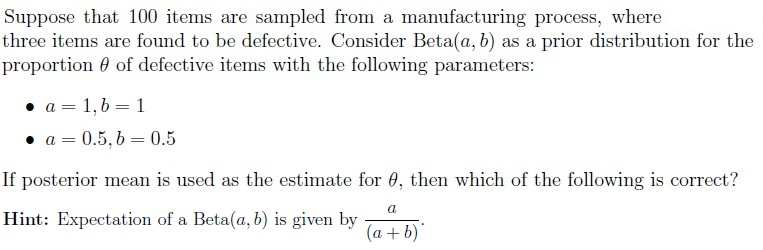
- Posterior mean for Beta(1, 1) is 0.039.
- Posterior mean for Beta(1, 1) is 0.03.
- Posterior mean for Beta(0.5, 0.5) is 0.025.
- Posterior mean for Beta(0.5, 0.5) is 0.034.
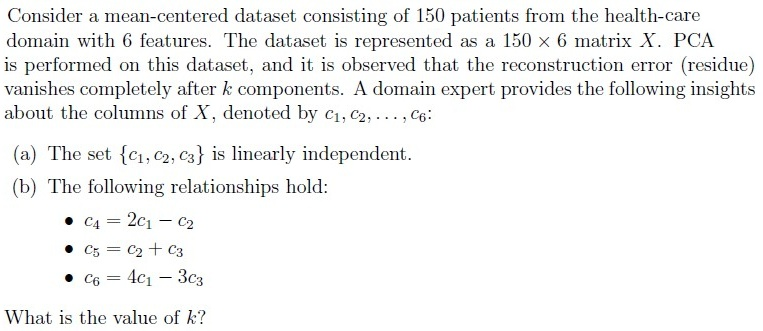
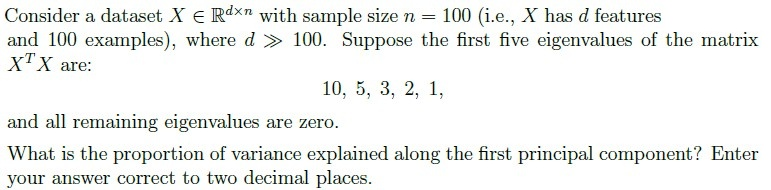
Which of the following are valid kernel functions? Select all that apply.
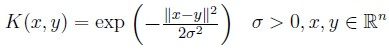
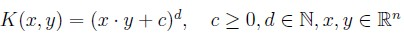
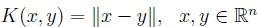
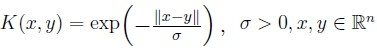
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
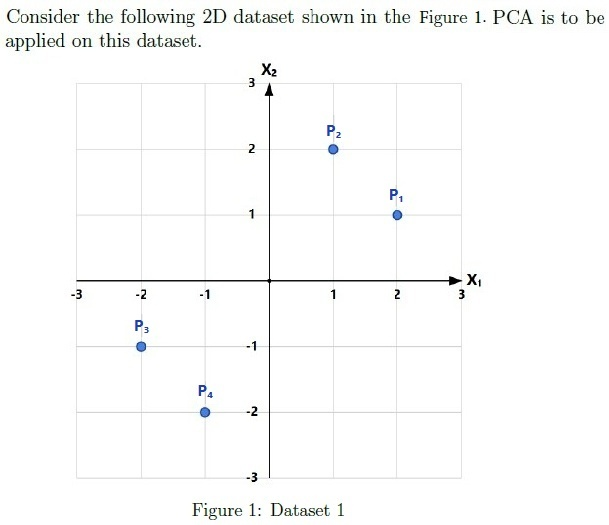
What is the covariance matrix of the dataset?


If standard PCA is performed on this dataset, what is the variance along the first principal component? Enter the answer correct to one decimal place.
If standard PCA is performed on this dataset, what is the variance along the second principal component? Enter the answer correct to one decimal place.
Comprehension passage - the questions below it refer to this
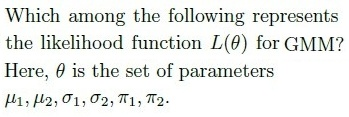
Based on the above data, answer the given subquestions.
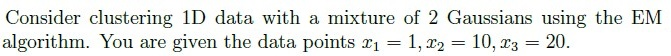
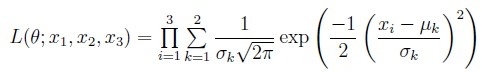
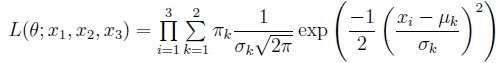
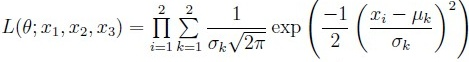
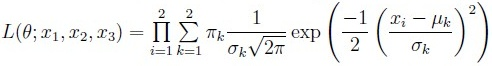
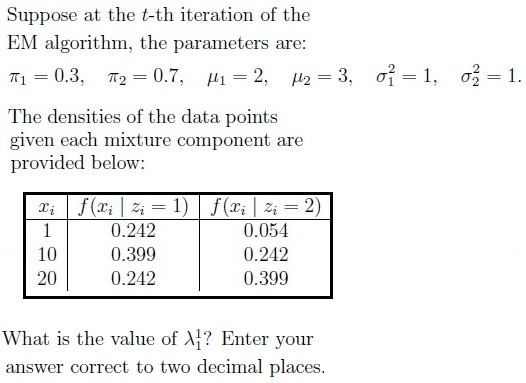
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
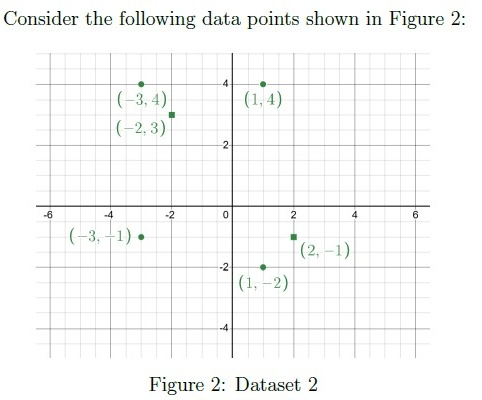
Perform K-means clustering with K = 2 and initial cluster centers at (−2, 3) and (2,−1). What are the final means of clusters after convergence?
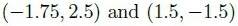
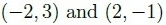
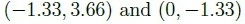
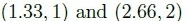
Suppose we introduce a new data point (0, 0) to the existing dataset and perform K means with the same initial cluster centers. How many iterations would it require now for convergence?
Answer key
- Q1 (MSQ, 2 marks): A, C
- Q2 (MSQ, 4 marks): B, D
- Q3 (MSQ, 4 marks): B, C, D
- Q4 (MSQ, 4 marks): A, D
- Q5 (MSQ, 3 marks): A, B, D
- Q6 (SA, 3 marks): 3
- Q7 (SA, 3 marks): 0.45 to 0.50
- Q8 (MCQ, 2 marks): B
- Q9 (SA, 2 marks): 4.5
- Q10 (SA, 2 marks): 0.5
- Q11 (MCQ, 3 marks): B
- Q12 (SA, 3 marks): 0.64 to 0.68
- Q13 (MCQ, 3 marks): A
- Q14 (SA, 2 marks): 1
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of the core topics, concepts, principles, and equations essential for the Diploma-Level Machine Learning Techniques exam, along with Mermaid knowledge graphs to visualize relationships.
1. Core Topics & Key Concepts
A. Clustering Algorithms
1. K-Means & K-Means++
Lloyd’s Algorithm (Standard K-Means)
- Convergence: Always converges (monotonically decreases objective function).
- Sensitivity: Sensitive to outliers (uses Euclidean distance).
- Optimality: May converge to local optima (not guaranteed global optimum).
- Initialization Dependency: Performance depends on initial centroids.
K-Means++ Initialization
- Goal: Spread out initial centroids to improve convergence.
Selection Probability:
- First centroid: Randomly chosen.
- Subsequent centroids: Chosen with probability proportional to , where is the distance to the nearest existing centroid.
- Score Function:
- Convergence: Faster convergence than random initialization.
2. Gaussian Mixture Models (GMM) & EM Algorithm
- Likelihood Function for GMM:
where:
- : Mixing coefficient (prior probability of cluster ).
- : Gaussian PDF for cluster .
EM Algorithm Steps:
- E-Step: Compute responsibilities ():
- M-Step: Update parameters () using responsibilities.
- Convergence: Monotonically increases log-likelihood.
B. Dimensionality Reduction (PCA)
1. Principal Component Analysis (PCA)
- Goal: Find orthogonal directions (principal components) that maximize variance.
Steps:
- Center the Data: Subtract the mean.
- Compute Covariance Matrix: .
Eigen Decomposition: Solve , where:
- : Matrix of eigenvectors (principal components).
- : Diagonal matrix of eigenvalues (variances).
- Project Data: (top components).
Key Properties:
- Eigenvalues: Number of non-zero eigenvalues = intrinsic dimensionality.
- Reconstruction Error: Zero if intrinsic dimension.
- Variance Explained: Proportion of variance by top components:
Example:
- If data lies in a 6D subspace of , PCA will yield 6 non-zero eigenvalues.
- If 50 eigenvalues are non-zero, data is full-rank.
2. Covariance Matrix & Eigenvalues
- Covariance Matrix ():
- Eigenvalues: Represent variance along principal components.
- Trace: Total variance = sum of eigenvalues.
C. Bayesian Statistics
1. Beta-Binomial Model (Bayesian Inference for Proportions)
- Prior: .
- Likelihood: .
- Posterior: .
- Posterior Mean (Estimate for ):
where:
- : Number of successes.
- : Total trials.
Example:
- Prior: (uniform).
- Data: 3 defects out of 100.
- Posterior Mean: .
D. Kernel Methods
1. Valid Kernel Functions
A function is a valid kernel if it satisfies Mercer’s condition (symmetric and positive semi-definite).
Common Kernels:
- Gaussian (RBF) Kernel:
- Polynomial Kernel:
- Laplacian Kernel:
- Invalid Kernel Example: (not PSD).
E. Linear Algebra for ML
1. Rank & Linear Independence
- Rank: Number of linearly independent rows/columns.
Example:
- Given , , , the intrinsic dimension is 3 (since are linear combinations of ).
2. Eigenvalues & Variance
- Proportion of Variance Explained:
- Example: If eigenvalues are , the first PC explains (48%).
2. Key Equations Summary
| Topic | Equation |
|---|---|
| K-Means++ Score | |
| GMM Likelihood | |
| PCA Covariance | |
| PCA Projection | |
| Variance Explained | |
| Beta Posterior Mean | |
| Gaussian Kernel | |
| Polynomial Kernel |
Graph 2: Dimensionality Reduction (PCA)
Graph 3: Bayesian Inference
Graph 4: Kernel Methods
Graph 5: Linear Algebra for ML
4. Exam Tips
PCA:
- If data lies in a k-dimensional subspace, PCA will have k non-zero eigenvalues.
- Reconstruction error is zero if intrinsic dimension.
K-Means++:
- The second centroid is chosen with probability proportional to .
- Tie-breaking can affect final clusters.
GMM:
- The likelihood function involves a product of sums (not sum of products).
- Responsibilities () are soft assignments.
Bayesian Estimation:
- Beta-Binomial is used for proportion estimation.
- Posterior mean is a weighted average of prior and data.
Kernels:
- RBF, Polynomial, Laplacian are valid.
- Absolute difference () is not a valid kernel.