Home / Past papers / MLT Quiz 1 / this paper
IIT M IMPROVEMENT AN EXAM QIB2 26 Oct - 26 Oct 2025
Elapsed 00:00
Which among the following is true with respect to the Lloyds’ algorithm?
- It always converges.
- It may fail to converge for an initialization while it may converge for otherinitialization.
- It is sensitive to outliers.
- The solution produced is always the optimal.

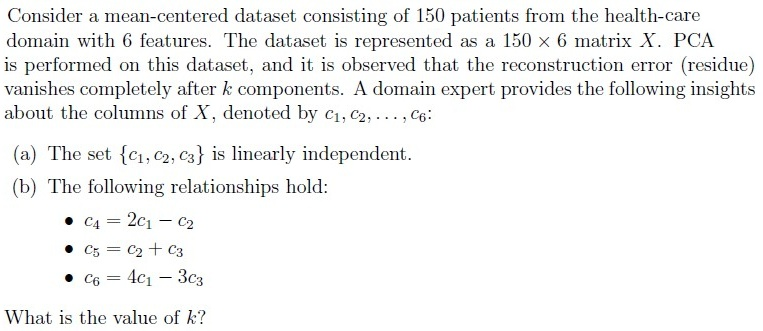
- There will be 50 non-zero eigenvalues of the covariance matrix.
- There will be 6 non-zero eigenvalues of the covariance matrix.
- Using the first 5 principal components, the dataset can be reconstructed withzero residue.
- The variance captured by the top 6 principal components equals the totalvariance of the dataset.
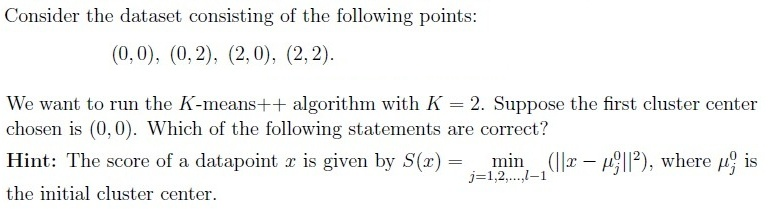
- The points (0, 2), (2, 0), and (2, 2) have the equal probability of being chosen asthe second cluster center.
- The probability of selecting (2, 2) as the second cluster center is twice that ofselecting (0, 2).
- If (2, 2) is chosen as the second cluster center, the algorithm will alwaysconverge in one iteration.
- The tie-breaking rule will affect the final cluster centers.
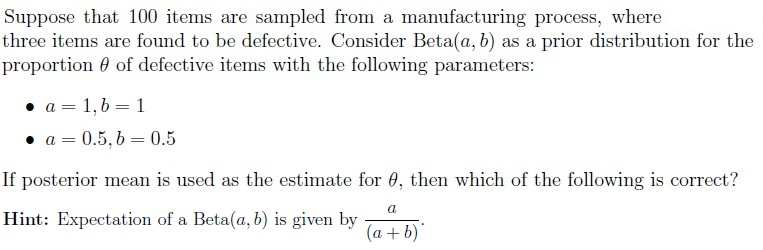
- Posterior mean for Beta(1, 1) is 0.039.
- Posterior mean for Beta(1, 1) is 0.03.
- Posterior mean for Beta(0.5, 0.5) is 0.025.
- Posterior mean for Beta(0.5, 0.5) is 0.034.
Which of the following are valid kernel functions? Select all that apply.
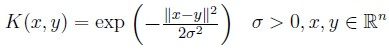
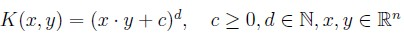
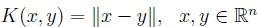
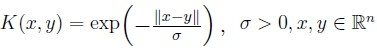
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
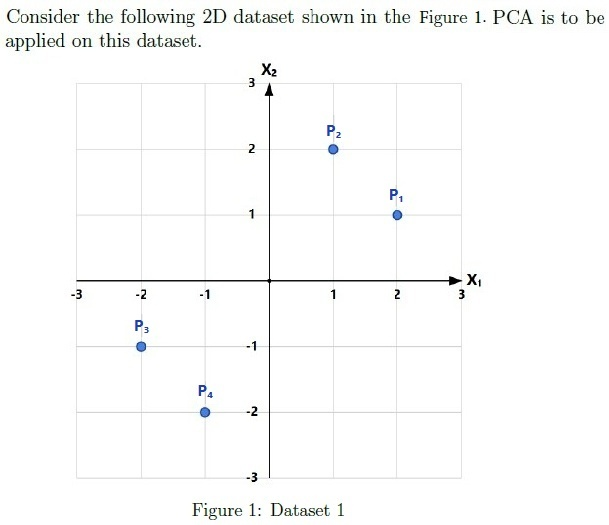
What is the covariance matrix of the dataset?


If standard PCA is performed on this dataset, what is the variance along the first principal component? Enter the answer correct to one decimal place.
If standard PCA is performed on this dataset, what is the variance along the second principal component? Enter the answer correct to one decimal place.
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
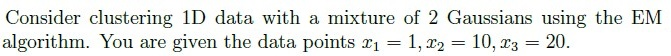
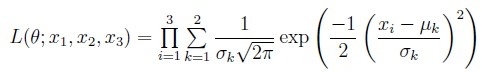
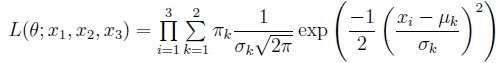
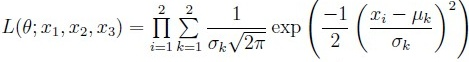
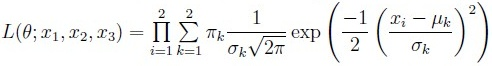
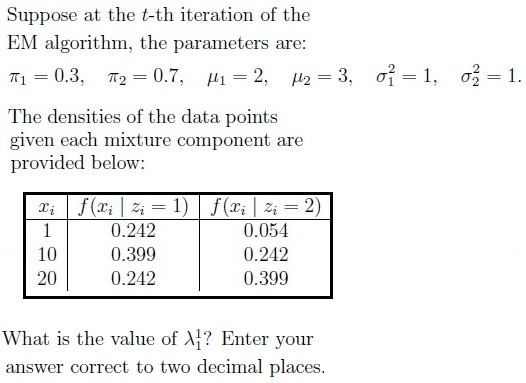
Comprehension passage - the questions below it refer to this
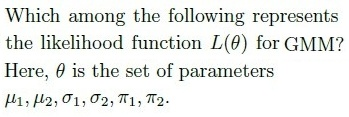
Based on the above data, answer the given subquestions.
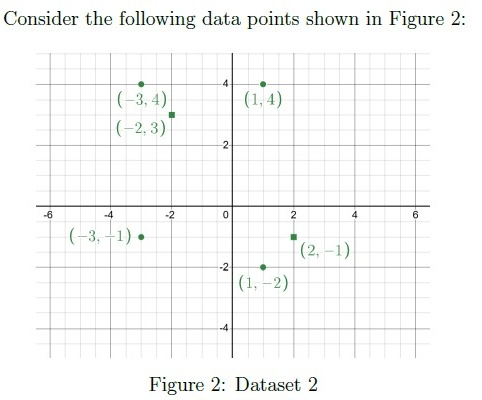
Perform K-means clustering with K = 2 and initial cluster centers at (−2, 3) and (2,−1). What are the final means of clusters after convergence?
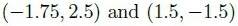
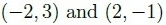
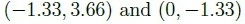
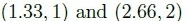
Suppose we introduce a new data point (0, 0) to the existing dataset and perform K means with the same initial cluster centers. How many iterations would it require now for convergence?
Answer key
- Q1 (MSQ, 2 marks): A, C
- Q2 (MSQ, 4 marks): B, D
- Q3 (MSQ, 4 marks): B, C, D
- Q4 (MSQ, 4 marks): A, D
- Q5 (MSQ, 3 marks): A, B, D
- Q6 (SA, 3 marks): 3
- Q7 (SA, 3 marks): 0.45 to 0.50
- Q8 (MCQ, 2 marks): B
- Q9 (SA, 2 marks): 4.5
- Q10 (SA, 2 marks): 0.5
- Q11 (MCQ, 3 marks): B
- Q12 (SA, 3 marks): 0.64 to 0.68
- Q13 (MCQ, 3 marks): A
- Q14 (SA, 2 marks): 1
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Key Concepts
1. Clustering (K-Means, K-Means++, Lloyd’s Algorithm)
K-Means Algorithm:
- Iterative partitioning into K clusters by minimizing within-cluster variance.
Steps:
- Initialize centroids (randomly or via K-Means++).
- Assign points to nearest centroid (Euclidean distance).
- Recompute centroids as mean of assigned points.
- Repeat until convergence (centroids stabilize).
- Convergence: Guaranteed (monotonically decreases objective function), but may converge to local optima.
- Sensitivity to Outliers: Yes (outliers can skew centroids).
K-Means++ Initialization:
- Improves convergence by spreading initial centroids.
- Probability of selection: Proportional to squared distance from existing centroids.
- Score function:
- Tie-breaking: Affects final clusters if distances are equal.
Lloyd’s Algorithm:
- Synonym for standard K-Means.
Properties:
- Converges for any initialization (but may not be globally optimal).
- Sensitive to outliers.
2. Principal Component Analysis (PCA)
- Goal: Dimensionality reduction while preserving variance.
Steps:
- Center the data (subtract mean).
- Compute covariance matrix .
Eigen decomposition: , where:
- : Eigenvectors (principal components, PCs).
- : Eigenvalues (variances along PCs).
- Project data onto top-k PCs.
Key Properties:
- PCs are orthogonal.
- First PC captures maximum variance.
- Reconstruction error: Zero if .
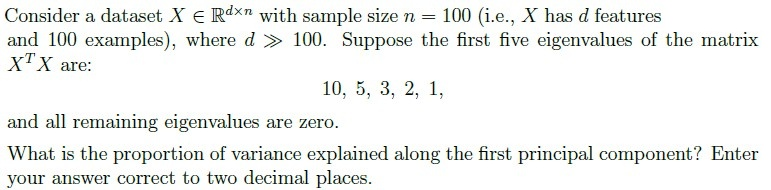
- Variance explained by PC_i:
- Linear Subspace: If data lies in a k-dimensional subspace, only k eigenvalues are non-zero.
Example:
- For a dataset in lying in a 6D subspace, PCA yields 6 non-zero eigenvalues.
3. Gaussian Mixture Models (GMM) & EM Algorithm
GMM: Probabilistic model assuming data is generated from K Gaussian distributions.
- Parameters: Means , covariances , mixing coefficients .
- Likelihood function:
where is the Gaussian PDF.
EM Algorithm:
- E-step: Compute responsibilities ():
- M-step: Update parameters:
Posterior Mean (Beta Prior):
- For Beta(a, b) prior, posterior mean (Bayesian estimate):
Example: 3 defects in 100 items:
- Beta(1,1) posterior mean = .
- Beta(0.5,0.5) posterior mean = .
4. Kernel Methods
- Kernel Trick: Map data to higher-dimensional space via kernel function .
Valid Kernels (must satisfy Mercer’s condition):
- Gaussian (RBF) Kernel:
- Polynomial Kernel:
- Laplacian Kernel:
- Invalid Kernel: (not positive semi-definite).
5. Covariance Matrix & PCA on Toy Datasets
- Covariance Matrix:
For centered data, .
- Example (2D Dataset):
- Points: .
- Covariance Matrix:
- Eigenvalues: 4.5 (1st PC), 0.5 (2nd PC).
Variance Explained:
- 1st PC: (90%).
- 2nd PC: 10%.
2. PCA & Dimensionality Reduction
3. Probabilistic Models (GMM & Bayesian Estimation)
4. Kernel Methods
Key Equations Summary
| Topic | Equation |
|---|---|
| K-Means++ Score | |
| PCA Variance | |
| GMM Likelihood | |
| EM Responsibility | |
| Beta Posterior Mean | |
| Gaussian Kernel | |
| Polynomial Kernel |
Exam Tips
- K-Means: Know convergence properties, initialization (K-Means++), and sensitivity to outliers.
- PCA: Focus on eigenvalues/variance explained, reconstruction error, and linear subspaces.
- GMM/EM: Understand the likelihood function, responsibilities, and parameter updates.
- Kernels: Memorize valid kernels (RBF, polynomial, Laplacian) and invalid ones (e.g., ).
- Bayesian Estimation: Practice calculating posterior means for Beta priors.
- Toy Datasets: Compute covariance matrices and PCA manually for small datasets (e.g., 2D points).