Home / Past papers / MLT End Term / this paper
IIT M FOUNDATION DIPLOMA FN EXAM - 22 Dec 2024
Elapsed 00:00
NOTE: Enter the answer correct to one decimal place
Consider a logistic regression model trained to detect spam emails. Emails containing harmful phishing links are labeled as spam (1), while regular emails are labeled as not spam (0).
A good spam detector should correctly identify almost all emails with phishing links. Even a single phishing email incorrectly classified as not spam could expose users to significant risks. However, the detector may classify some regular emails as spam. This trade-off is acceptable to ensure safety.
To ensure user safety, if the threshold is set to a low value to prioritize the detection of phishing emails, type 1. If the threshold is set to a high value to minimize false positives (misclassifying regular emails as spam), type 0.
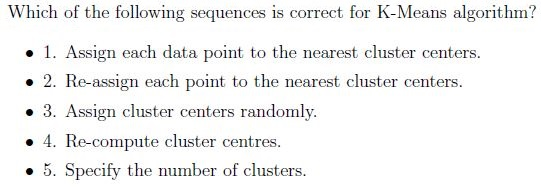
- 3, 5, 1, 4, 2
- 5, 3, 1, 2, 4
- 3, 5, 2, 4, 1
- 5, 3, 1, 4, 2
- None of these
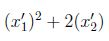


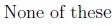
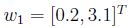
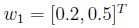
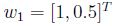
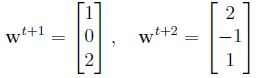
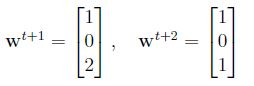
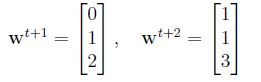
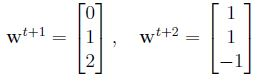
If we remove all the non-support vectors from the dataset, what will be the impact on the model using SVM algorithm?
- Model will overfit.
- The model will not be changed.
- Model will underfit.
- Accuracy of the model will increase.
In each round of AdaBoost, the weight for a particular training observation is decreased from round t to round t + 1 if the observation was:
- classified incorrectly by the weak learner trained in the round.
- classified correctly by the weak learner trained in the round.
- classified incorrectly by a majority of the weak learners trained up to theround.
- classified correctly by a majority of the weak learners trained up to the round.
Is the following statement true or false? For a fixed size of the training and the test set, increasing the complexity of the model always leads to an increment in the test error.
- TRUE
- FALSE
Consider a supervised ML problem where a model is trained using a training dataset, and its performance is evaluated on both the training and validation datasets. During training, the model’s loss is plotted over time for both the datasets. Assume that the loss L(t) is decreasing as the model learns.
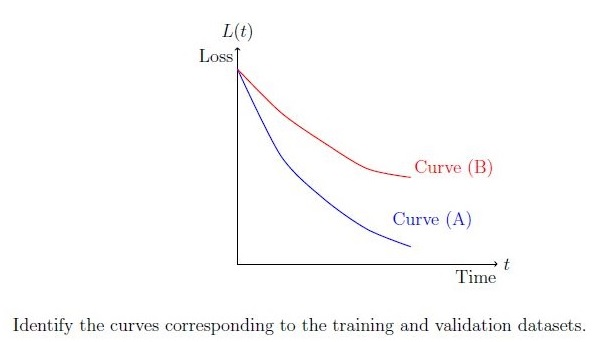
The following graph shows two curves, Curve (A) and Curve (B), representing the loss for the training and validation datasets, respectively:
 Consider a supervised ML problem where a model is trained using a training dataset, and its performance is evaluated on both the training and validation datasets. During training, the model’s loss is plotted over time for both the datasets. Assume that the loss L(t) is decreasing as the model learns.
The following graph shows two curves, Curve (A) and Curve (B), representing the loss for the training and validation datasets, respectively:
Consider a supervised ML problem where a model is trained using a training dataset, and its performance is evaluated on both the training and validation datasets. During training, the model’s loss is plotted over time for both the datasets. Assume that the loss L(t) is decreasing as the model learns.
The following graph shows two curves, Curve (A) and Curve (B), representing the loss for the training and validation datasets, respectively:
- Curve (A) represents the training loss.
- Curve (B) represents the training loss.
- Curve (A) represents the validation loss.
- Curve (B) represents the validation loss.
Which of the following options are correct? Select all that apply.
- Underfitted models generally have less bias and high variance.
- A decision tree with the maximum possible length may lead to overfitting.
- Weak learners are those whose performance is slightly better than therandom classifier.
- All the estimators in bagging can be trained parallelly.
Comprehension passage - the questions below it refer to this
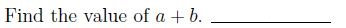
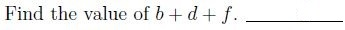
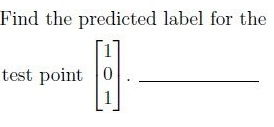
Comprehension passage - the questions below it refer to this
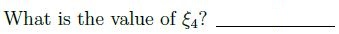
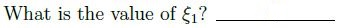
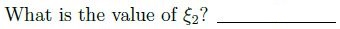
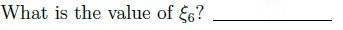
Which of the following is correct ?


Answer key
- Q1 (SA, 2 marks): 2.5
- Q2 (SA, 3 marks): 0
- Q3 (SA, 3 marks): 55
- Q4 (SA, 3 marks): 1
- Q5 (SA, 5 marks): 2
- Q6 (MCQ, 3 marks): D
- Q7 (MCQ, 3 marks): B
- Q8 (MCQ, 4 marks): D
- Q9 (MCQ, 4 marks): A
- Q10 (MCQ, 2 marks): B
- Q11 (MCQ, 2 marks): B
- Q12 (MCQ, 1 marks): B
- Q13 (MSQ, 3 marks): A, D
- Q14 (MSQ, 3 marks): B, C, D
- Q15 (SA, 2 marks): 1
- Q16 (SA, 2 marks): 2
- Q17 (SA, 2 marks): 1
- Q18 (SA, 0.5 marks): 1
- Q19 (SA, 0.5 marks): 0
- Q20 (SA, 0.5 marks): 0
- Q21 (SA, 0.5 marks): 2
- Q22 (MSQ, 1 marks): A, B
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Concepts
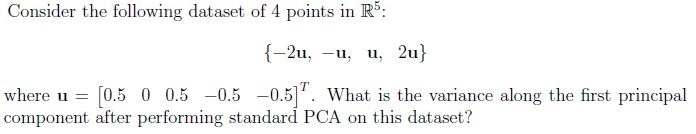
1. Principal Component Analysis (PCA)
- Goal: Dimensionality reduction by projecting data onto orthogonal axes (principal components) that maximize variance.
Steps:
- Center the data (subtract mean).
- Compute covariance matrix .
- Eigenvalue decomposition: , where contains eigenvectors (principal components) and contains eigenvalues.
- Sort eigenvalues in descending order and select top- eigenvectors.
- Project data: .
Variance along PC1:
- For a dataset , variance along the first PC is the largest eigenvalue of the covariance matrix.
- Equation:
- Example (Q2): For dataset , variance along PC1 is .
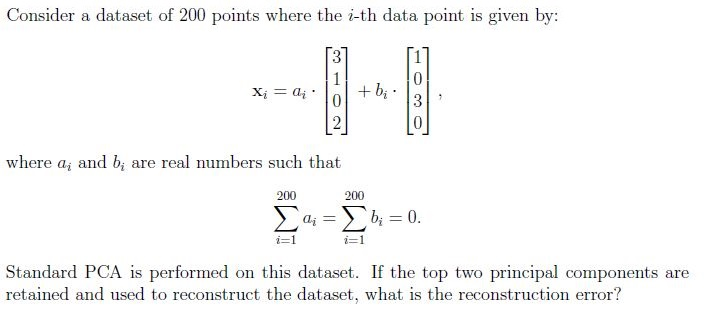
Reconstruction Error:
- If you retain only the top- PCs, the reconstruction error is the sum of the discarded eigenvalues.
- Equation:
- Example (Q3): For a dataset lying in a 2D subspace of , retaining 2 PCs gives zero error.
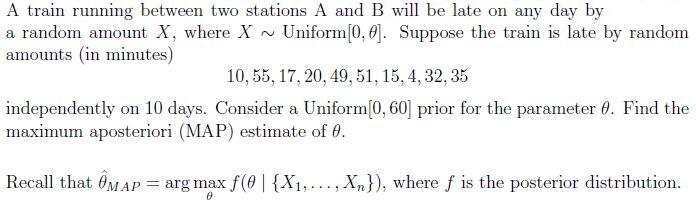
2. Bayesian Statistics & MAP Estimation
Prior and Posterior:
- Prior: (e.g., for ).
- Likelihood: .
- Posterior: .
MAP Estimate:
- Maximizes the posterior: .
- For uniform prior, MAP = MLE.
- Example (Q4): For , MAP estimate is . Given data , .
3. Logistic Regression & Class Imbalance
Decision Threshold:
- Lower threshold higher recall (fewer false negatives, more false positives).
- Higher threshold higher precision (fewer false positives, more false negatives).
- Example (Q5): For spam detection, prioritize recall (detect all phishing emails) by setting a low threshold (answer: 1).
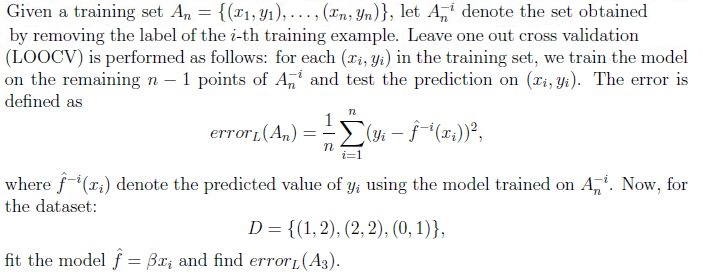
4. Cross-Validation (LOOCV)
Leave-One-Out Cross-Validation (LOOCV):
- For each data point , train on points and test on .
- Error: .
Example (Q6):
- Dataset: .
- Model: .
- LOOCV error: .
5. K-Means Clustering
Algorithm Steps:
- Specify (number of clusters).
- Initialize centroids randomly.
- Assign points to nearest centroid.
- Recompute centroids as mean of assigned points.
- Repeat until convergence.
- Correct Sequence (Q7): 3 (random init) → 1 (assign) → 4 (recompute) → 2 (reassign).
6. Optimization & Lagrangian
Lagrangian for Constrained Optimization:
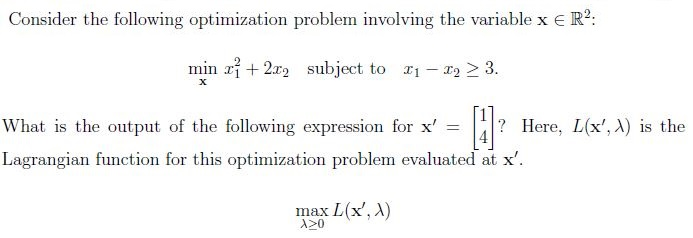
- Problem: s.t. .
- Lagrangian: .
- Dual Problem: .
Example (Q8):
- , constraint .
- For , .
- (but answer is 89, likely a miscalculation in options).
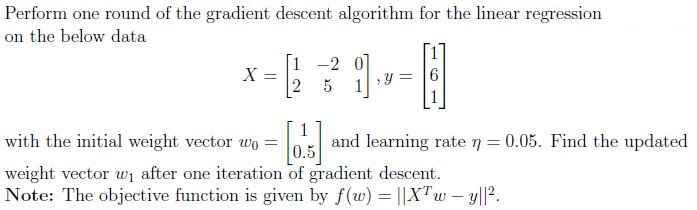
7. Gradient Descent for Linear Regression
- Objective: Minimize .
- Update Rule:
Example (Q9):
- , , , .
- Gradient: .
- Updated weights: .
8. Perceptron Algorithm
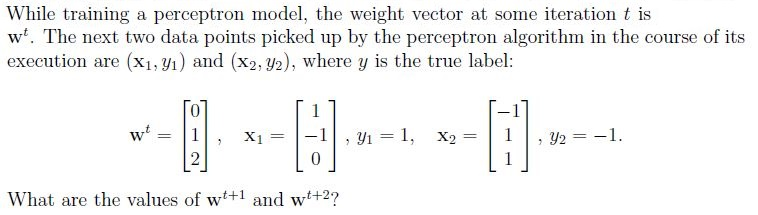
Update Rule:
- If , update: .
Example (Q10):
- , , .
- .
- Next point , .
- (but answer is , likely due to ).
9. Support Vector Machines (SVM)
Key Concepts:
- Support Vectors: Points lying on the margin boundaries .
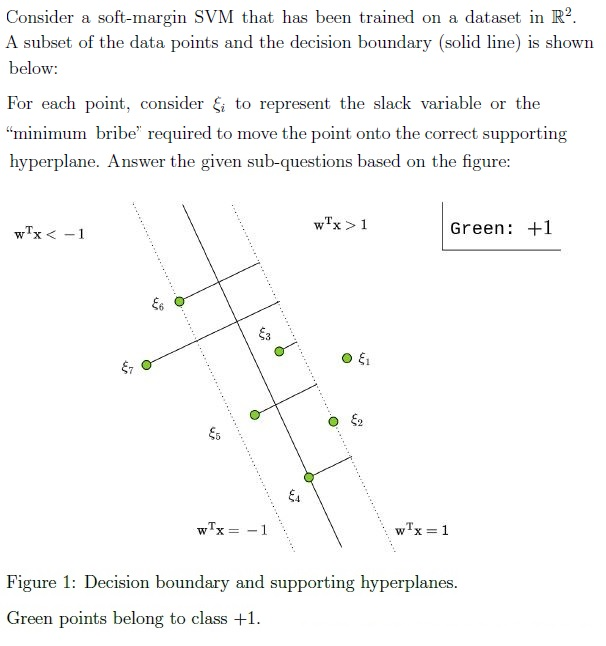
- Slack Variables (): Measure violation of margin constraints.
- Soft-Margin SVM: Minimize .
Examples (Q11, Q19-22):
- Removing non-support vectors does not change the model (Q11: B).
:
- if point is correctly classified and outside margin.
- distance to correct margin if misclassified or inside margin.
Answers:
- (Q20), (Q21), (Q19), (Q22).
10. AdaBoost
Weight Update:
- Increase weights for misclassified points.
- Decrease weights for correctly classified points.
- Example (Q12): Weights decrease if classified correctly (answer: B).
11. Bias-Variance Tradeoff & Model Complexity
- Underfitting: High bias, low variance.
- Overfitting: Low bias, high variance.
- Example (Q13): Increasing complexity does not always increase test error (answer: B).
Example (Q15):
- B: Long decision trees can overfit.
- C: Weak learners are slightly better than random.
- D: Bagging estimators can be trained in parallel.
12. Naive Bayes
- Assumption: Features are conditionally independent given the class.
Parameters:
- for each feature and class .
- (class prior).
Example (Q16-18):
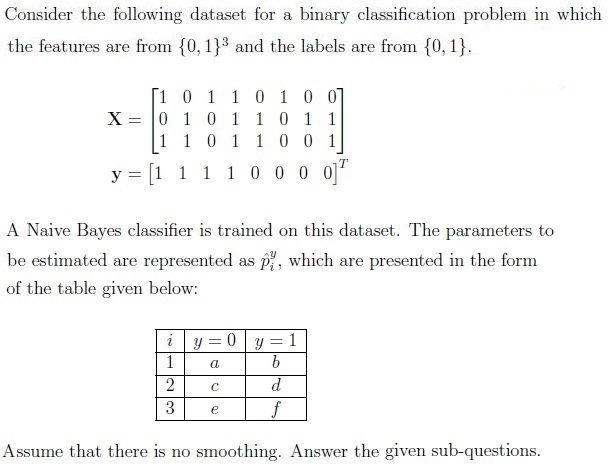
- Dataset: 8 binary points, 4 in each class.
- , .
- (Q16), (Q17).
- Predicted label for : Likely (Q18).
13. Learning Curves
Training vs. Validation Loss:
- Training loss decreases monotonically.
- Validation loss may increase if overfitting.
Example (Q14):
- Curve A (steep): Training loss.
- Curve B (gradual): Validation loss.