Home / Past papers / MLT Quiz 2 / this paper
IIT M FOUNDATION AN EXAM QDF2 16 Mar - 16 Mar 2025
Elapsed 00:00
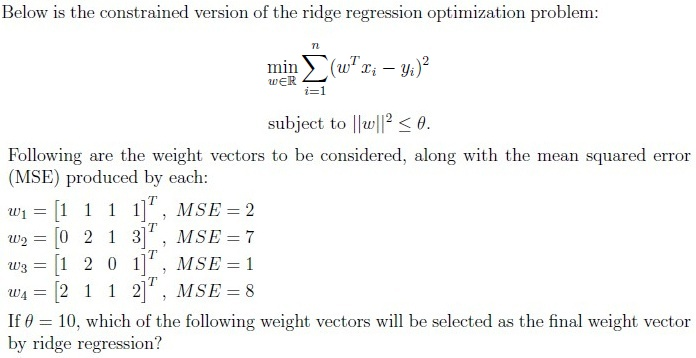


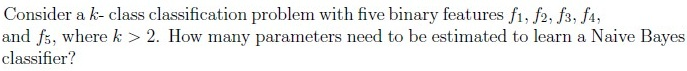


p is the proportion of points with label 1 in some node in a decision tree. Which of the following statements are true?
- As the value of p increases from 0 to 1, the impurity of the node increases.
- As the value of p increases from 0 to 1, the impurity of the node decreases.
- The impurity of the node does not depend on p.
- p = 0.5 correspond to the case of maximum impurity.
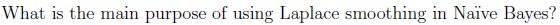
- To prevent numerical errors when calculating the variance of Gaussianfeatures.
- To ensure that unseen categorical feature values receive small but nonzeroprobabilities.
- To strengthen the model’s predictions by increasing the weight of certainfeatures.
- To balance the likelihood values of all features before computing posteriorprobabilities.
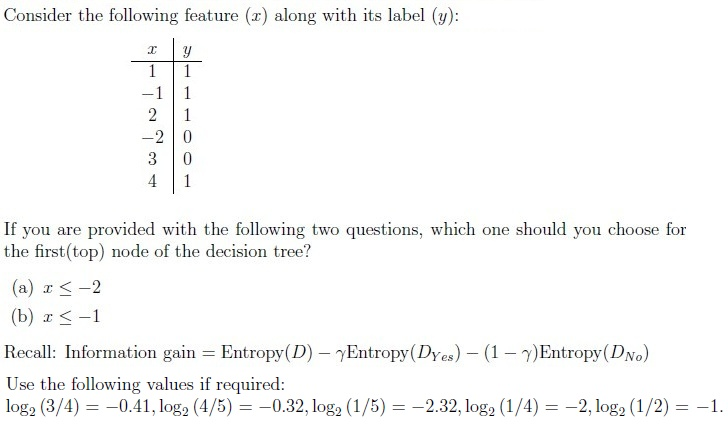
- (a)
- (b)
- Insufficient information
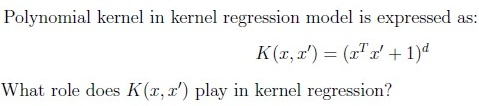
- It ensures that the regression model remains linear.
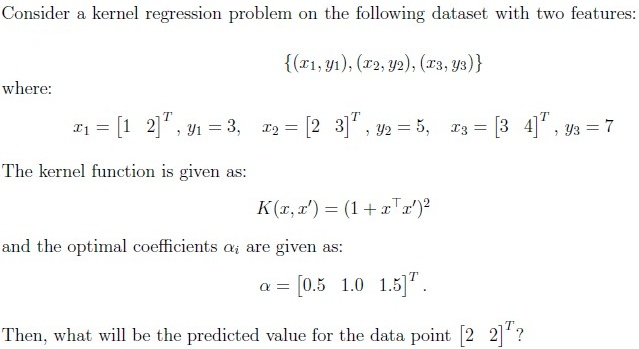
- It computes the similarity between data points in a transformed feature space.
- It allows the model to capture non-linear relationships by mapping data to ahigher-dimensional space.
- It helps in reducing the variance of the model.
- It minimizes the loss function in regression problems.

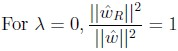
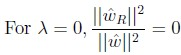
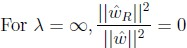
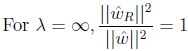
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
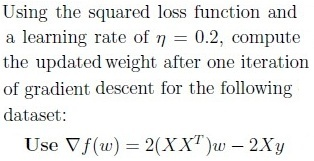
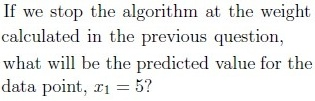
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
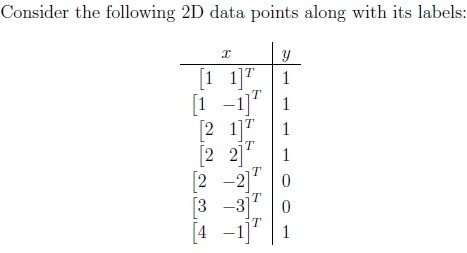
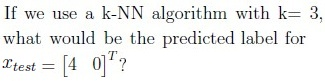
Compute the Leave-one-out cross validation (LOOCV) error for the 3- nearest neighbour (3-NN) algorithm on this dataset. Enter the answer correct to two decimal places.
Is it possible to reduce the cross-validation error obtained in the previous question by changing the label of certain points?
- Yes
- No
- Cannot conclude from the given information.
Answer key
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
1. Ridge Regression
- Concept: Ridge regression is a regularized version of linear regression that includes a penalty term to prevent overfitting.
- Optimization Problem:
- Key Idea: It adds a regularization term to the loss function to shrink the coefficients.
2. Naive Bayes Classifier
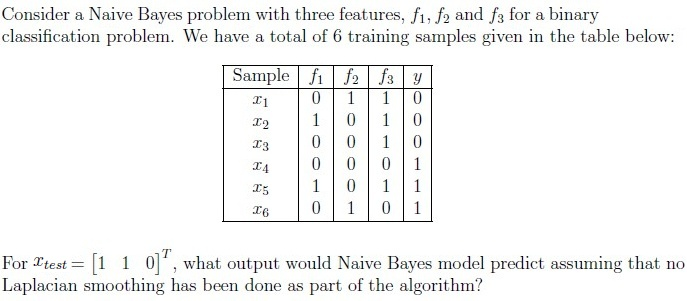
- Concept: A probabilistic classifier based on Bayes' theorem with strong independence assumptions between features.
- Parameters: For a -class classification problem with binary features, the number of parameters to estimate is .
- Laplace Smoothing: Used to handle zero probabilities in categorical data.
where is the count of feature in class , is the total count of features in class , and is the number of possible feature values.
3. Decision Trees
- Impurity Measures: Gini impurity and entropy are used to measure the disorder in a node.
- Information Gain: Used to decide the best split in a decision tree.
- Key Idea: The goal is to reduce impurity at each split.
4. Kernel Regression
- Concept: A non-parametric method to capture non-linear relationships by mapping data to a higher-dimensional space.
- Polynomial Kernel:
- Role of Kernel: Computes the similarity between data points in a transformed feature space.
5. Gradient Descent
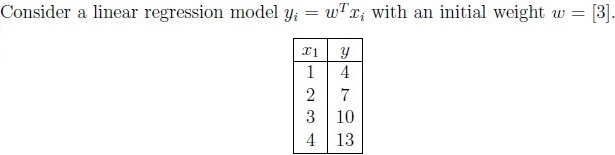
- Concept: An optimization algorithm used to minimize the loss function in linear regression.
- Update Rule:
where is the learning rate and is the gradient of the loss function.
- Gradient for Linear Regression:
6. k-Nearest Neighbors (k-NN)
- Concept: A non-parametric method used for classification and regression.
- Key Idea: Predicts the label of a data point based on the majority label of its nearest neighbors.
- Leave-One-Out Cross-Validation (LOOCV): A method to evaluate the performance of a model by leaving one data point out at a time.