Home / Past papers / MLT Quiz 1 / this paper
IIT M DIPLOMA AN4 EXAM QDD4 25 Feb 2024 - 25 Feb 2024
Elapsed 00:00
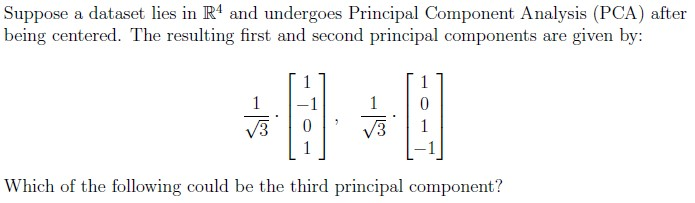
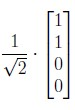
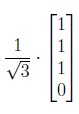
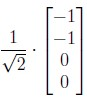
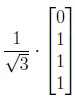
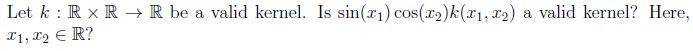
- Yes
- No
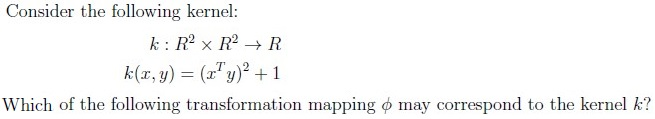
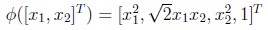
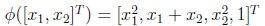
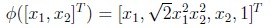
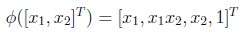
Consider a dataset consisting of 1000 samples in a 20-dimensional space. You apply Kernel PCA with a polynomial kernel of degree 3 to reduce the dimensionality of the data. Which of the following statements regarding Kernel PCA is true?
- Kernel PCA always results in a lower-dimensional representation of the datacompared to standard PCA.
- Kernel PCA can only be applied to datasets that are linearly separable.
- Choosing a higher degree polynomial kernel in Kernel PCA can lead toincreased flexibility in capturing non-linear relationships.
- None of these.
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
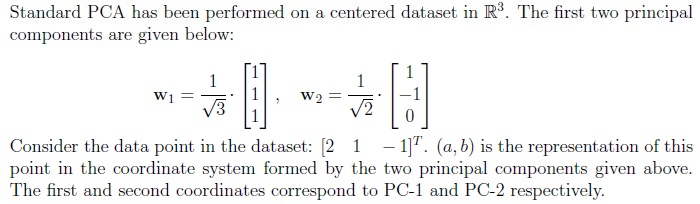
What is the value of a? Enter your answer correctly to three decimal places.
What is the value of b? Enter your answer correctly to two decimal places.
Comprehension passage - the questions below it refer to this
Consider the data points shown in the following image:
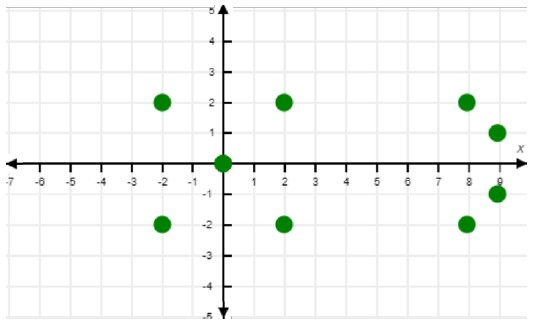 Consider the data points shown in the following image: Based on the above data, answer the given subquestions.
Perform K-means clustering with K = 2 and initial cluster centers at (0, 0) and (6, 0). What are the final means of clusters after convergence?
- (2, 0) and (8, 0)
- (2, 0) and (8.5, 0)
- (0, 0) and (8, 0)
- (0, 0) and (8.5, 0)
- None of these
After introducing a new data point (7, 0) , the cluster centers were updated. Enter the sum of the updated x-coordinates for both cluster centers accurately, rounding your answer to two decimal places.
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
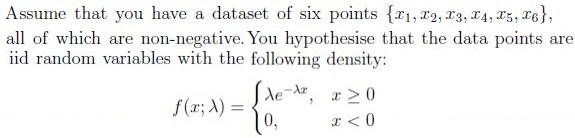
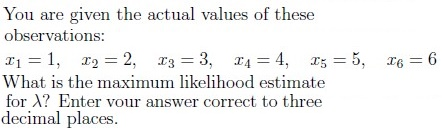
What is the log-likelihood of this dataset under this distribution? ln represents the natural logarithm or loge.


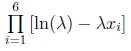
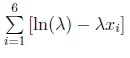
Consider Lloyd’s algorithm used for k-means clustering and choose the correct statements:
- K-means algorithm may get stuck at local minima.
- It guarantees finding the optimal clustering (global minimum) in every run.
- In practice, k should be as large as possible.
- If the resources are limited and the data set is huge, it will be good to prefer K-means over K-means++.
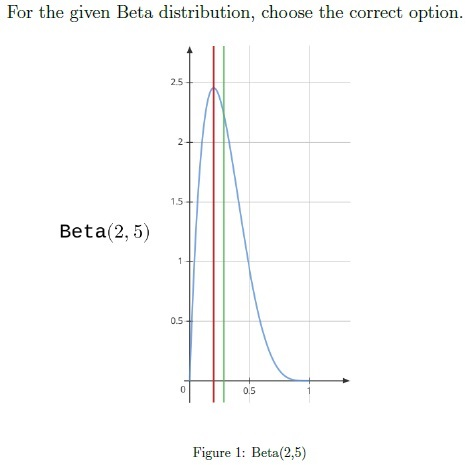
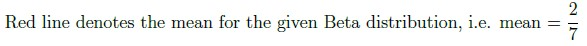
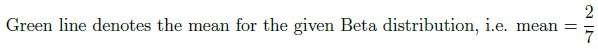
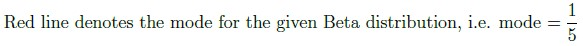
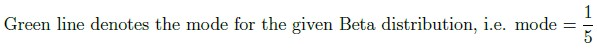
Consider a dataset with 100 total data points. Each data point is classified as either type A or type B. We model this using a Bernoulli distribution, where p is the probability of a data point being type A. If the maximum likelihood estimate (MLE) of p based on the dataset is 0.4, how many data points of type B are there in this dataset?
Answer key
- Q1 (MCQ, 4 marks): D
- Q2 (MCQ, 4 marks): B
- Q3 (MCQ, 4 marks): A
- Q4 (MCQ, 4 marks): C
- Q5 (SA, 4 marks): 1.10 to 1.20
- Q6 (SA, 4 marks): 0.65 to 0.75
- Q7 (MCQ, 4 marks): D
- Q8 (SA, 4 marks): 8.18 to 8.22
- Q9 (MCQ, 2 marks): D
- Q10 (SA, 2 marks): 0.25 to 0.35
- Q11 (MSQ, 5 marks): A, D
- Q12 (MSQ, 5 marks): B, C
- Q13 (SA, 4 marks): 60
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
1. Principal Component Analysis (PCA)
- Concept: PCA is a technique used to reduce the dimensionality of a dataset while preserving its variance.
Key Equations:
- Principal Components:
- Projection of data onto principal components: ,
- Covariance Matrix:
- Eigenvalue Decomposition:
2. Kernel Methods and Kernel PCA
- Concept: Kernel methods are used to transform data into a higher-dimensional space to make it easier to separate.
Key Equations:
- Kernel Function:
- Polynomial Kernel:
- Kernel PCA:
3. K-Means Clustering
- Concept: K-Means is an iterative algorithm that partitions data into K clusters.
Key Equations:
- Objective Function:
- Cluster Assignment:
- Centroid Update:
4. Probability Distributions
- Concept: Probability distributions describe the likelihood of different outcomes.
Key Equations:
- Exponential Distribution:
- Likelihood Function:
- Log-Likelihood Function:
- Maximum Likelihood Estimate (MLE):
5. Bernoulli Distribution
- Concept: The Bernoulli distribution models the outcome of a single trial with two possible outcomes.
Key Equations:
- Probability Mass Function:
- Maximum Likelihood Estimate (MLE):