Home / Past papers / MLT End Term / this paper
IIT M IMPROVEMENT AN EXAM QDD4 01 - 01 Sep 2024
Elapsed 00:00
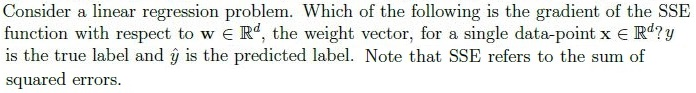


- 1
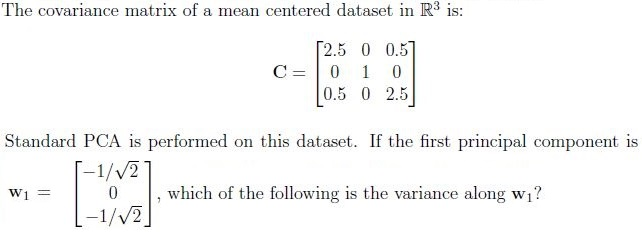
- 2
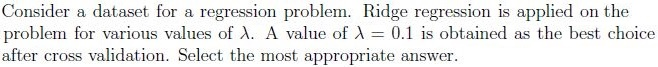
- 3
- 6
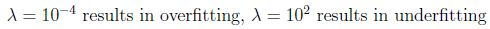
Match the characteristics given below with the appropriate ensemble technique. 1. Decision stumps 2. Deep decision trees 3. Parallel execution 4. Sequential execution
- Bagging → (2), (3); Boosting → (1), (4)
- Bagging → (1), (4); Boosting → (2), (3)
- Bagging → (1), (3); Boosting → (2), (4)
- Bagging → (2), (4); Boosting → (1), (3)
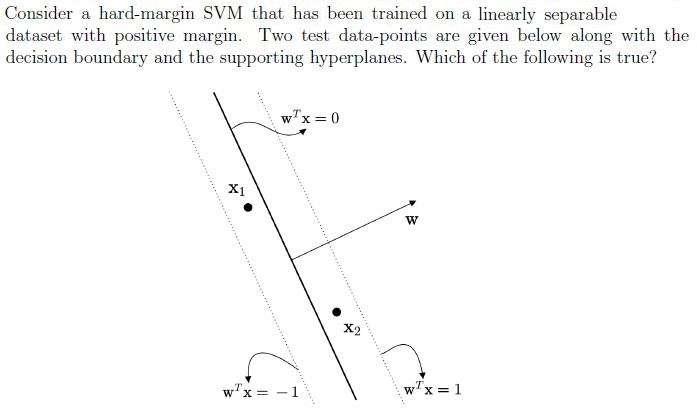
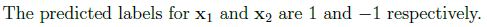
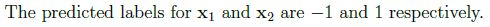
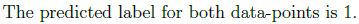
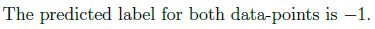

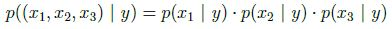
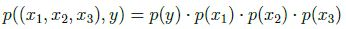
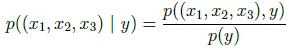
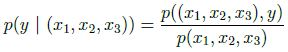
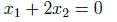
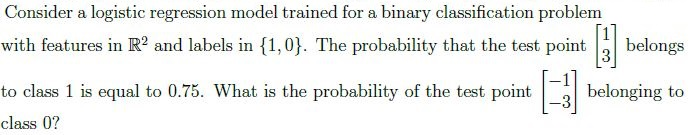
- 0.75
- 0.25
- 0.5
- 0.15
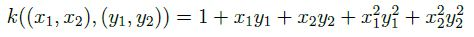
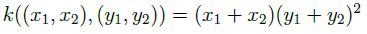
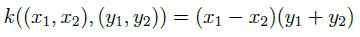
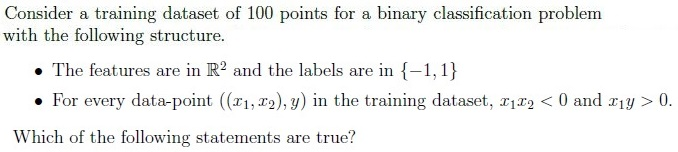
- The dataset is linearly separable with a positive margin.
- The perceptron algorithm will terminate after a finite number of iterationswhen trained on this dataset.
- The dataset is linearly separable, but the margin may be zero.
- The dataset is not linearly separable.
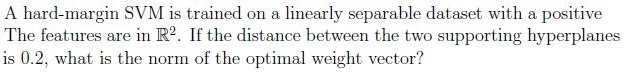
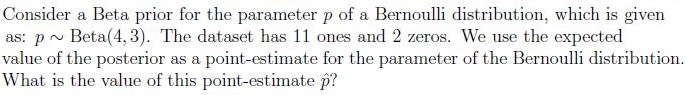
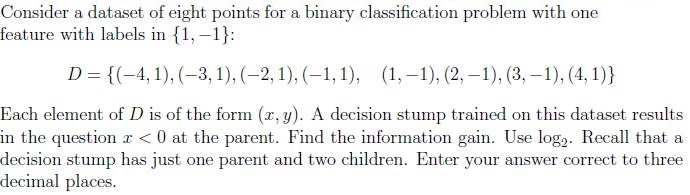
Comprehension passage - the questions below it refer to this
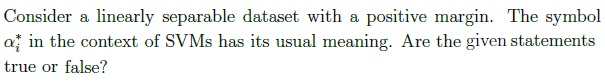
The weight vector output by the perceptron algorithm can be expressed as a linear combination of the data-points where the coefficients of the linear combination are integers.
- TRUE
- FALSE
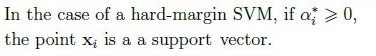
- TRUE
- FALSE
If a soft-margin SVM is trained on this dataset, the optimal weight vector it returns will be the same as the one returned by a hard-margin SVM, irrespective of the value of the hyperparameter C.
- TRUE
- FALSE
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
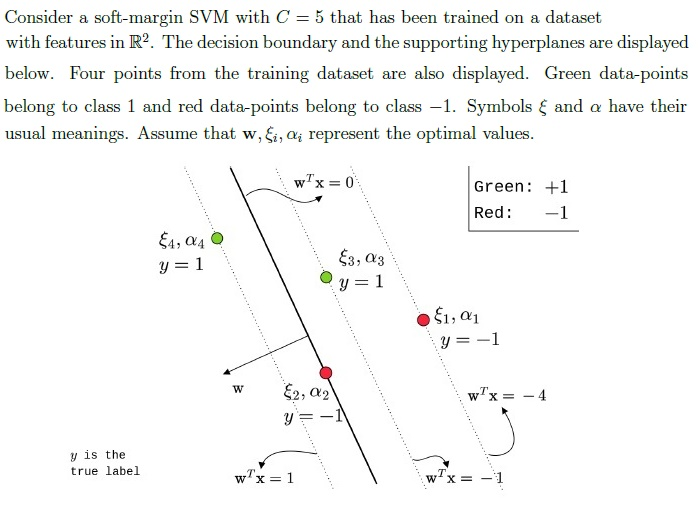


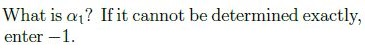
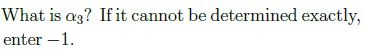
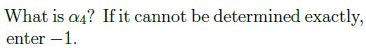
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
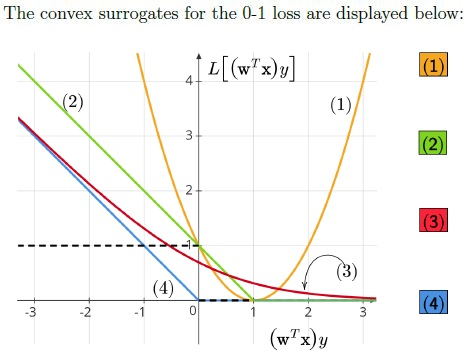
Enter the number corresponding to the logistic loss.
Enter the number corresponding to the (SVM) hinge loss.
Enter the number corresponding to the perceptron loss.
Enter the number corresponding to the squared loss.
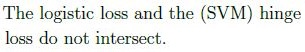
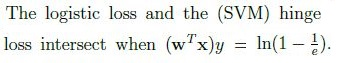
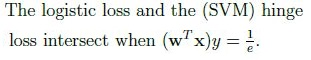
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
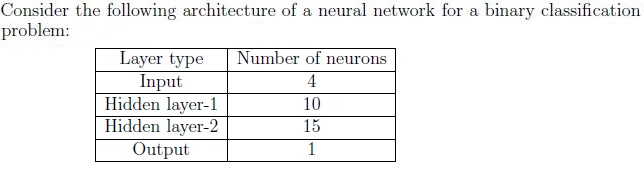
How many learnable parameters does this network have? Ignore the biases in the computation.
What is the most appropriate choice of activation function for the output layer if the binary cross-entropy loss is used?
- Sigmoid
- Linear
- ReLU
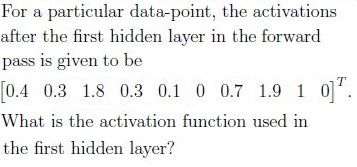
- ReLU
- Sigmoid
Answer key
- Q1 (MCQ, 2 marks): A
- Q2 (MCQ, 3 marks): C
- Q3 (MCQ, 3 marks): A
- Q4 (MCQ, 3 marks): A
- Q5 (MCQ, 3 marks): B
- Q6 (MCQ, 3 marks): A
- Q7 (MCQ, 3 marks): A
- Q8 (MCQ, 3 marks): A
- Q9 (MSQ, 3 marks): A, B
- Q10 (MSQ, 3 marks): A, B
- Q11 (SA, 3 marks): 10
- Q12 (SA, 3 marks): 0.75
- Q13 (SA, 3 marks): 0.50 to 0.60
- Q14 (MCQ, 1 marks): A
- Q15 (MCQ, 1 marks): B
- Q16 (MCQ, 1 marks): B
- Q17 (SA, 0.5 marks): 0
- Q18 (SA, 0.5 marks): 1
- Q19 (SA, 0.5 marks): 2
- Q20 (SA, 0.5 marks): 0
- Q21 (SA, 0.5 marks): 5
- Q22 (SA, 0.5 marks): -1
- Q23 (SA, 0.5 marks): 3
- Q24 (SA, 0.5 marks): 2
- Q25 (SA, 0.5 marks): 4
- Q26 (SA, 0.5 marks): 1
- Q27 (MCQ, 1 marks): A
- Q28 (SA, 1 marks): 205
- Q29 (MCQ, 1 marks): A
- Q30 (MCQ, 1 marks): A