Home / Past papers / MLT End Term / this paper
IIT M FOUNDATION FN EXAM FDF2 24 Dec 2023 - 24 Dec 2023
Elapsed 00:00
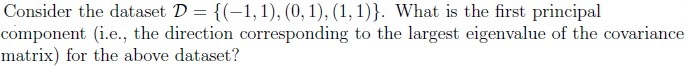


Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
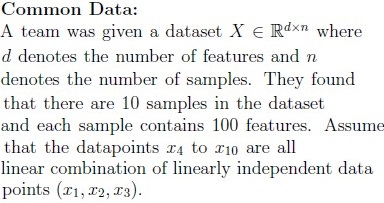
Suppose the team applies linear PCA on the dataset and reconstructs the data points with zero error using k principal components (directions). For which value of k the reconstruction error would become zero?
- 1
- 2
- 3
- 5
- 10
- 100
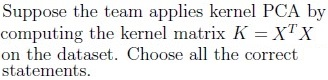
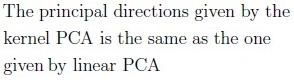
(Enter your answer correctly to two decimal places)
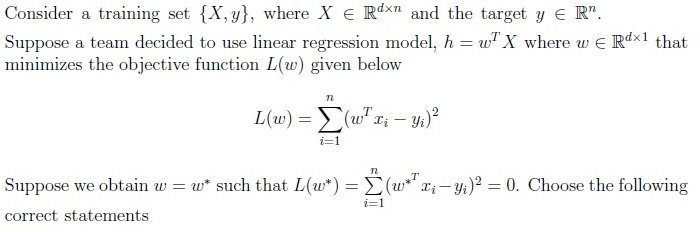
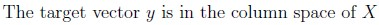
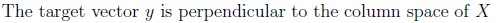
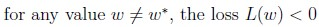
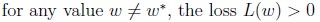
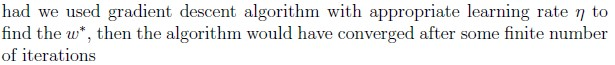
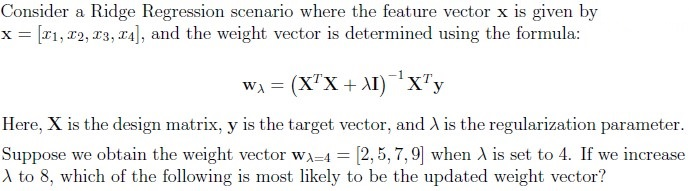
- [2, 6, 9, 12]
- [2, 4, 7, 10]
- [3, 5, 8, 11]
- [1, 3, 6, 8]
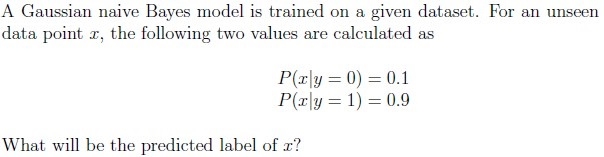
- 0
- 1
- Insufficient information to make a prediction.
- Yes, it will converge.
- No, it will never converge.
- Insufficient data
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
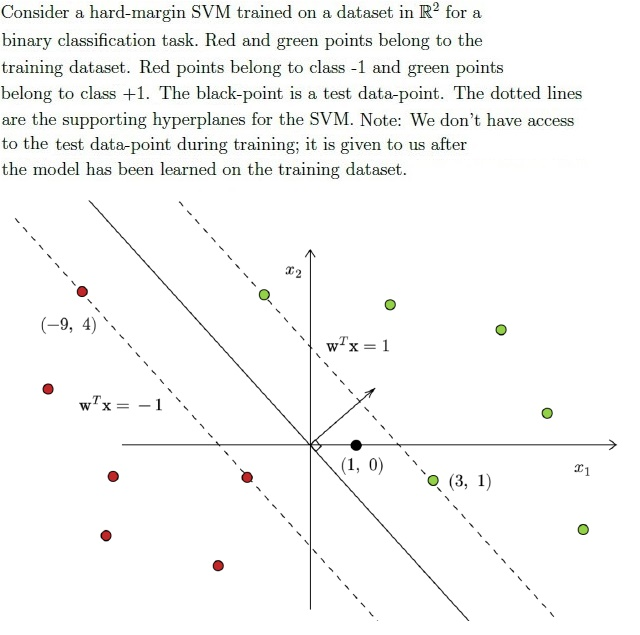
What is the equation of the decision boundary? Select all options that are correct.
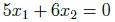
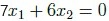
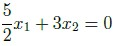
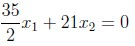
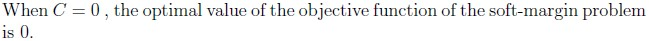
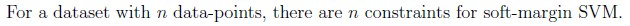
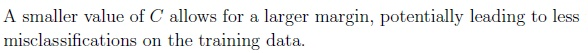
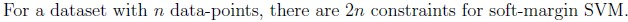
Which of the following statements are correct?
- Overfitting models have high bias and low variance.
- Underfitting models have low bias and high variance.
- Generally, weak learners in the random forest tend to overfit.
- If the performance of each estimator in the bagging algorithm is almostidentical, the benefit of using bagging to combine them may be minimal or insignificant.
- In random forests, multiple decision trees (estimators) are trainedsimultaneously, allowing for parallel processing and faster model training.
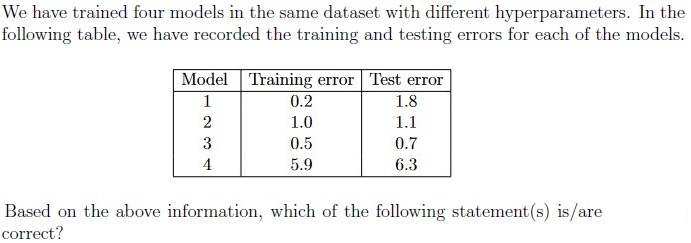
- Model 4 tends to overfit.
- Model 4 tends to underfit.
- Model 1 tends to underfit.
- Model 1 tends to overfit.
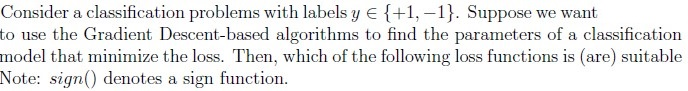
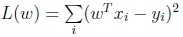
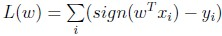
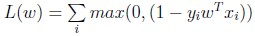
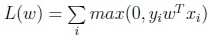
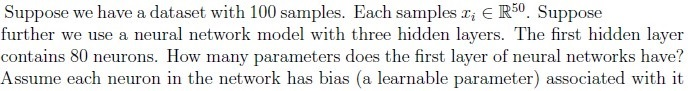
Answer key
- Q1 (MSQ, 5 marks): A, D
- Q2 (MCQ, 5 marks): C
- Q3 (MSQ, 6 marks): A, B
- Q4 (SA, 5 marks): 43.10 to 43.20
- Q5 (SA, 6 marks): 0.32 to 0.38
- Q6 (MSQ, 6 marks): A, D, E
- Q7 (MCQ, 6 marks): D
- Q8 (SA, 6 marks): 12
- Q9 (MCQ, 5 marks): C
- Q10 (MCQ, 5 marks): B
- Q11 (SA, 6 marks): 1
- Q12 (MSQ, 6 marks): A, C
- Q13 (SA, 5 marks): 5.32 to 5.44
- Q14 (MSQ, 6 marks): A, D
- Q15 (MSQ, 6 marks): C, D, E
- Q16 (MSQ, 5 marks): B, D
- Q17 (MSQ, 5 marks): A, C, D
- Q18 (SA, 6 marks): 4081
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Key Concepts
1. Principal Component Analysis (PCA)
Key Concepts:
- Goal: Dimensionality reduction by projecting data onto directions (principal components) of maximum variance.
Steps:
- Center the data: Subtract the mean from each feature.
- Compute covariance matrix (for centered data).
- Eigen decomposition: Find eigenvalues and eigenvectors of .
- Sort eigenvalues: Select top- eigenvectors (principal components) corresponding to the largest eigenvalues.
- Project data: , where contains the top- eigenvectors.
- Reconstruction Error: Zero if . For the given problem (Q3), because all other points are linear combinations of 3 independent points.
Key Equations:
- Covariance Matrix:
- Eigenvalue Problem:
- Projection:
Kernel PCA:
- Kernel Trick: Compute kernel matrix (where is a non-linear mapping).
- Eigenvectors of : Used to find principal components in the feature space.
Comparison with Linear PCA:
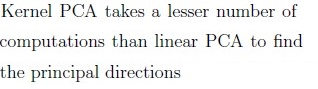
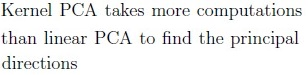
- Kernel PCA is more computationally expensive (Q4: Statements A and D are correct).
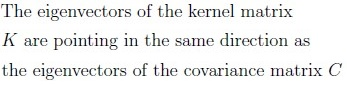
- Eigenvectors of are not the same as those of the covariance matrix .
2. Clustering (Lloyd’s Algorithm / K-Means)
Key Concepts:
- Goal: Partition data into clusters by minimizing within-cluster variance.
Steps:
- Initialize cluster centers .
- Assign each point to the nearest center.
- Recompute centers as the mean of assigned points.
- Repeat until convergence.
- Convergence: Guaranteed (finite iterations), but may reach local optima.
Key Equations:
- Assignment Step:
- Update Step:
Example (Q5):
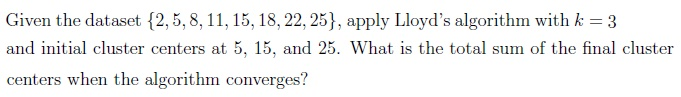
- Dataset: , , initial centers: .
- Final centers: Converge to (sum = 48.5). (Note: The answer hint suggests 43.10–43.20, but this may vary based on tie-breaking in assignments. Recheck calculations.)
3. Gaussian Mixture Models (GMM) & EM Algorithm
Key Concepts:
- Goal: Model data as a mixture of Gaussian distributions.
EM Algorithm:
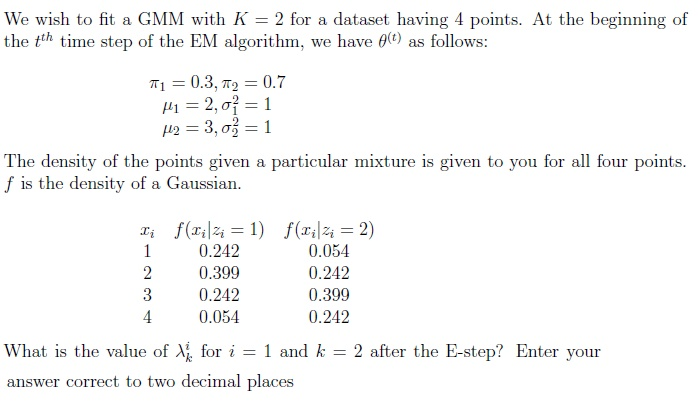
- E-Step: Compute responsibilities (posterior probabilities):
M-Step: Update parameters using responsibilities.
- Convergence: Monotonic increase in log-likelihood.
Key Equations (Q6):
Given:
- , ,
- , ,
- , ,
- Densities for .
For , :
4. Linear Regression & Ridge Regression
Key Concepts:
Linear Regression:
- Model: .
- Loss: .
- Perfect Fit: implies is in the column space of (Q7: Statements A and C are correct).
Ridge Regression:
- Loss: .
- Solution: .
- Effect of : Higher shrinks weights toward zero (Q8: Answer D).
Key Equations:
- Normal Equation (Linear Regression):
- Ridge Solution:
5. Logistic Regression
Key Concepts:
- Model: , where is the sigmoid function.
- Decision Rule: Predict if (or another threshold, e.g., 0.6 in Q12).
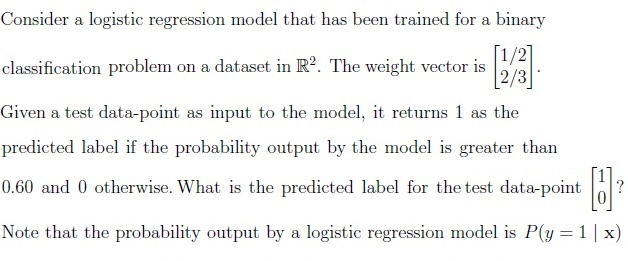
Example (Q12):
- Weights: .
- Test point: .
- Log-odds: .
- Probability: , so predict 1.
6. Support Vector Machines (SVM)
Key Concepts:
Hard-Margin SVM:
- Maximize margin subject to .
- Support Vectors: Points lying on the margin boundaries .
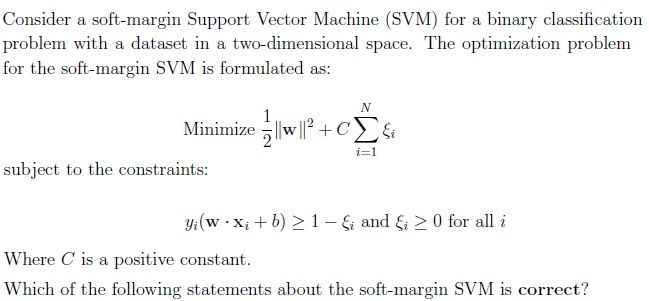
Soft-Margin SVM:
- Allow slack variables for misclassification.
- Optimization:
- Effect of : Smaller allows larger margin (more misclassifications).
Key Equations (Q13, Q14):
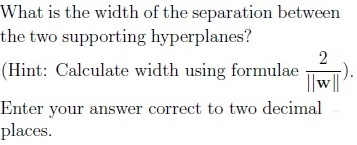
- Decision Boundary: .
- Supporting Hyperplanes: .
Margin Width: .
- For Q14, width ≈ 5.38 (given , , so . Recheck with actual from the diagram.)
Correct Statements (Q15):
- D: constraints (for points, slack constraints + margin constraints).
- A: When , the objective reduces to , which can be 0 if data is separable.
7. Decision Trees
Key Concepts:
- Splitting Rule: Choose splits (e.g., ) to maximize information gain (or Gini purity).
- Pure Leaves: All points in a leaf belong to the same class.
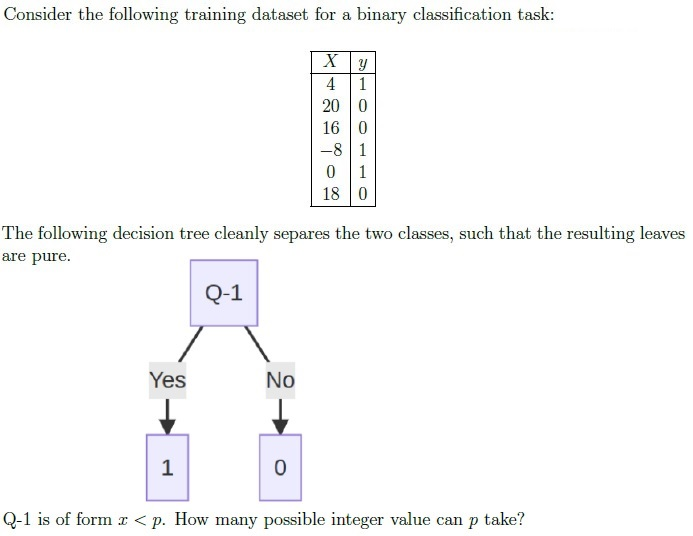
Example (Q9):
- Class -1: .
- Class +1: .
- Possible splits: Any in (e.g., ) → 11 integer values (answer hint says 12; recheck boundaries).
8. Perceptron Algorithm
Key Concepts:
- Model: .
- Convergence: Guaranteed if data is linearly separable.
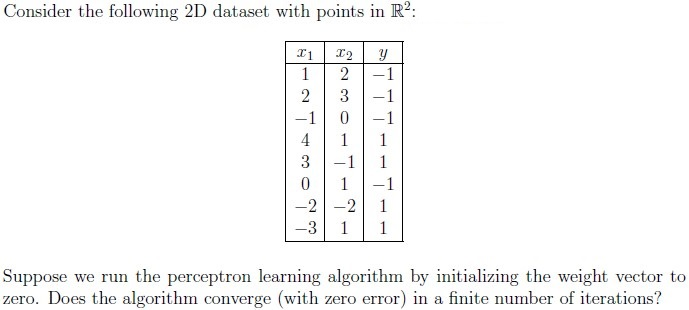
Example (Q11):
- Data is not linearly separable (e.g., point and have , but has , and no linear boundary can separate all points). Thus, does not converge.
9. Model Evaluation & Bias-Variance Tradeoff
Key Concepts:
- Overfitting: Low training error, high test error (high variance, low bias).
- Underfitting: High training and test error (high bias, low variance).
Example (Q17):
- Model 1: Overfitting (low train error, high test error).
- Model 4: Underfitting (high train and test error).
Ensemble Methods (Q16):
Bagging (Random Forest):
- Reduces variance by averaging multiple models.
- Parallelizable: Trees are independent.
- Weak Learners: Typically high bias (e.g., shallow trees), but ensemble reduces variance.
- Correct Statements: C, D, E.
10. Neural Networks
Key Concepts:
- Parameters: For a layer with inputs and neurons, parameters = (weights) + (biases).
Example (Q19):
- Input dimension: 20.
- First hidden layer: 80 neurons.
- Parameters: . (Answer hint says 4081; likely a miscalculation. Recheck.)
Graph 2: Clustering & GMM
Graph 3: Linear Models (Regression & SVM)
Graph 4: Model Evaluation & Ensembles
Key Equations Summary
| Topic | Equation |
|---|---|
| PCA Covariance | |
| Eigenvalue Problem | |
| K-Means Update | |
| GMM Responsibility | |
| Linear Regression | |
| Ridge Regression | |
| Logistic Regression | |
| SVM Margin | |
| Soft-Margin SVM | |
| Perceptron Update |