Home / Past papers / MLT Quiz 1 / this paper
IIT M QUIZ 1 FOUNDATION DAD DIPLOMA QPE3 16 Oct 2022 - 16 Oct 2022
- Yes
- No
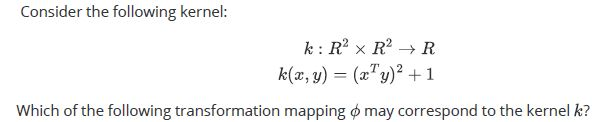
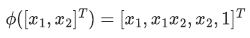
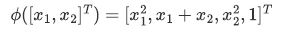
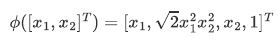
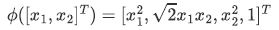
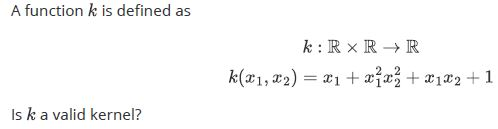
- Yes
- No
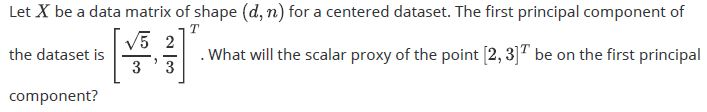


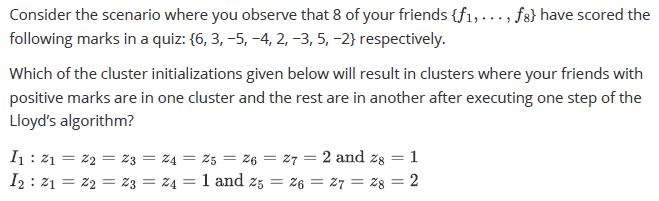
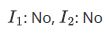
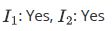
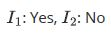
- 1
- 2
- 3
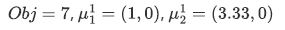
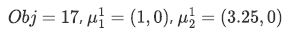
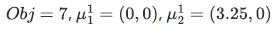
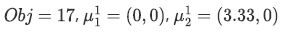
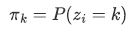

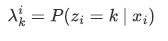
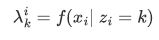
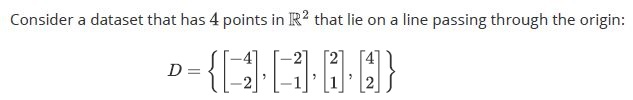
- Yes
- No



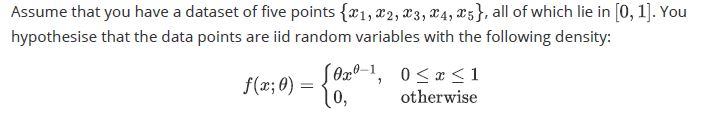


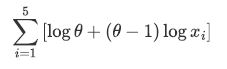
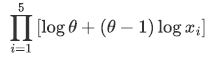
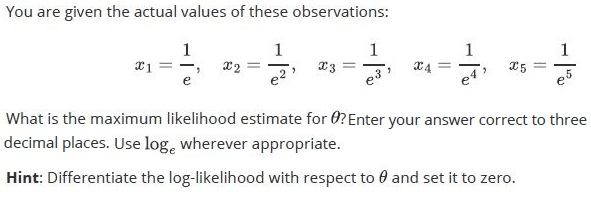
Answer key
- Q1 (MCQ, 0 marks): A
- Q2 (MCQ, 6 marks): D
- Q3 (MCQ, 6 marks): B
- Q4 (MCQ, 6 marks): D
- Q5 (MCQ, 6 marks): B
- Q6 (MCQ, 5 marks): A
- Q7 (MCQ, 5 marks): C
- Q8 (MSQ, 4 marks): A, C
- Q9 (SA, 5 marks): 0.09 to 0.11
- Q10 (SA, 5 marks): 6
- Q11 (SA, 5 marks): 15
- Q12 (SA, 5 marks): 0.29 to 0.31
- Q13 (SA, 7 marks): 6
- Q14 (SA, 3 marks): 0.03 to 0.04
- Q15 (SA, 3 marks): 0.01 to 0.02
- Q16 (SA, 3 marks): 0.06 to 0.07
- Q17 (MCQ, 3 marks): A
- Q18 (MSQ, 4 marks): A, B
- Q19 (SA, 5 marks): 12.4 to 12.6
- Q20 (SA, 4 marks): 0
- Q21 (MCQ, 5 marks): C
- Q22 (SA, 5 marks): 0.32 to 0.34
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
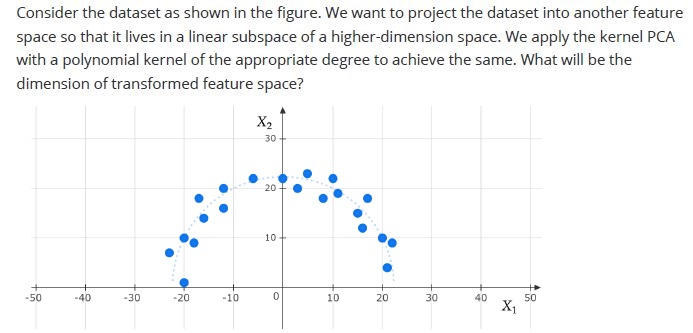
1. Kernel Methods and Kernel PCA
Kernel Functions: Functions that compute the inner product of two vectors in a high-dimensional space without explicitly transforming the vectors.
- Example: Polynomial kernel
Transformation Mapping (): Maps data to a higher-dimensional space.
- Example:
- Valid Kerners: A kernel must satisfy Mercer's condition to be valid.
2. Principal Component Analysis (PCA)
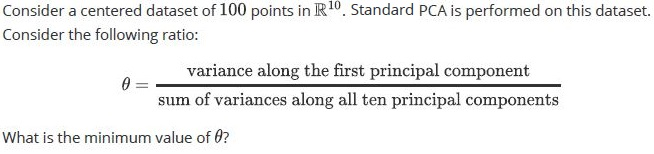
Principal Components: Directions in which the data varies the most.
- Example: First principal component
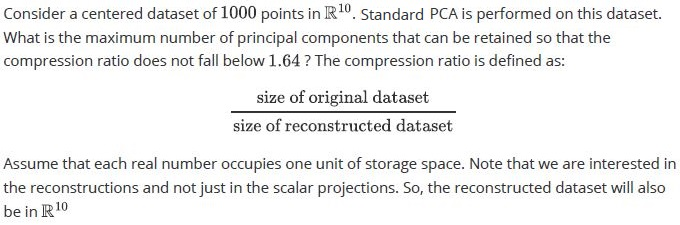
Variance and Compression Ratio:
- Variance along principal components:
- Compression ratio:
3. Clustering Algorithms
K-Means and Lloyd’s Algorithm:
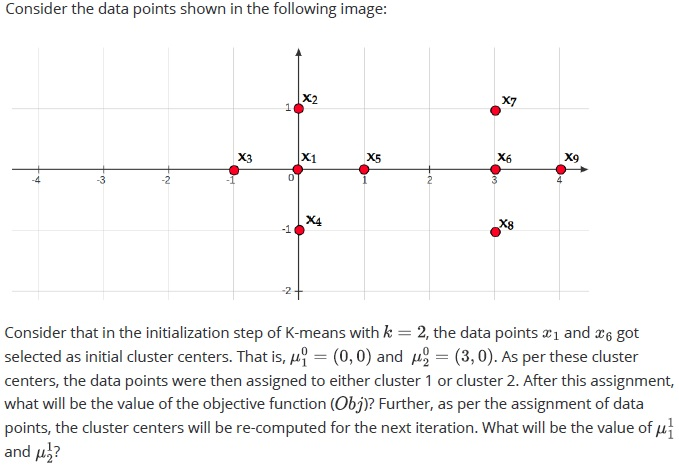
- Initialization: Choose initial cluster centers.
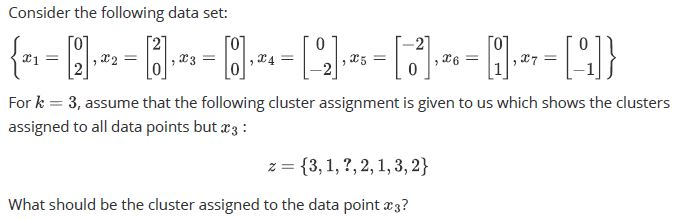
- Assignment: Assign each data point to the nearest cluster center.
- Update: Recompute the cluster centers as the mean of the assigned points.
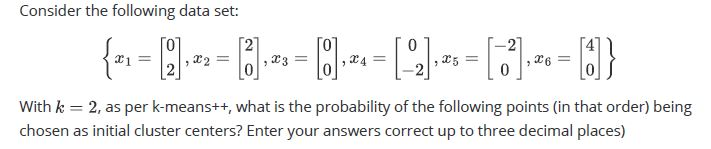
K-Means++: Probabilistic method for choosing initial cluster centers to improve convergence.
- Probability of choosing a point: Proportional to the squared distance from the closest already chosen center.
4. Gaussian Mixture Models (GMM) and EM Algorithm
EM Algorithm: Iterative method for finding maximum likelihood estimates of parameters in probabilistic models.
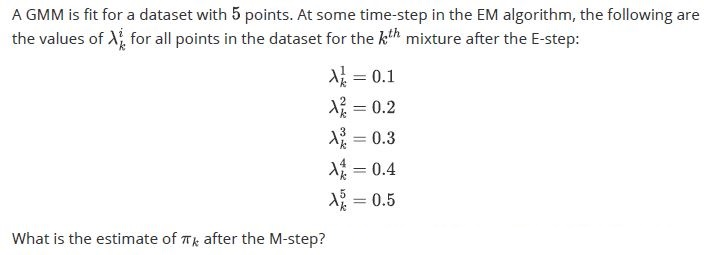
- E-step: Compute the posterior probabilities () of each data point belonging to each mixture component.
- M-step: Update the parameters (, , ) of the mixture components.
GMM Parameters:
- : Mixing coefficients.
- : Posterior probabilities.
5. Probability and Statistics
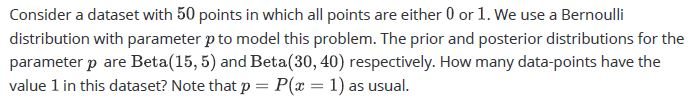
Bernoulli Distribution: Models binary outcomes.
- Example:
Beta Distribution: Conjugate prior for the parameter of a Bernoulli distribution.
- Example: Prior , Posterior
Log-Likelihood: Logarithm of the likelihood function.
- Example:
6. Data Centering and Variance
- Centered Dataset: Dataset where the mean of each feature is zero.
- Variance along Principal Components: Measure of the spread of data along each principal component.