Home / Past papers / MLT Quiz 1 / this paper
IIT M FOUNDATION AN EXAM QDF2 26 Oct - 26 Oct 2025
- It always converges.
- It may fail to converge for an initialization while it may converge for otherinitialization.
- It is sensitive to outliers.
- The solution produced is always the optimal.

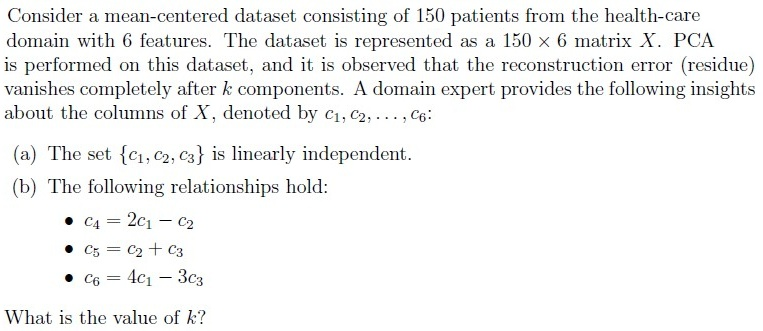
- There will be 50 non-zero eigenvalues of the covariance matrix.
- There will be 6 non-zero eigenvalues of the covariance matrix.
- Using the first 5 principal components, the dataset can be reconstructed withzero residue.
- The variance captured by the top 6 principal components equals the totalvariance of the dataset.
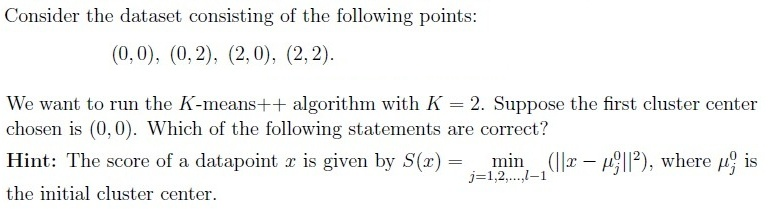
- The points (0, 2), (2, 0), and (2, 2) have the equal probability of being chosen asthe second cluster center.
- The probability of selecting (2, 2) as the second cluster center is twice that ofselecting (0, 2).
- If (2, 2) is chosen as the second cluster center, the algorithm will alwaysconverge in one iteration.
- The tie-breaking rule will affect the final cluster centers.
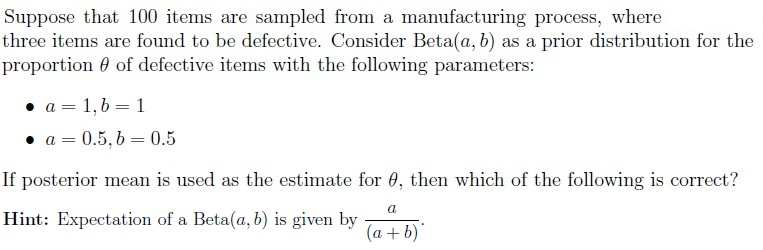
- Posterior mean for Beta(1, 1) is 0.039.
- Posterior mean for Beta(1, 1) is 0.03.
- Posterior mean for Beta(0.5, 0.5) is 0.025.
- Posterior mean for Beta(0.5, 0.5) is 0.034.
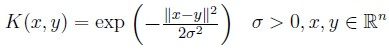
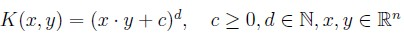
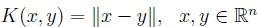
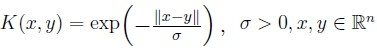


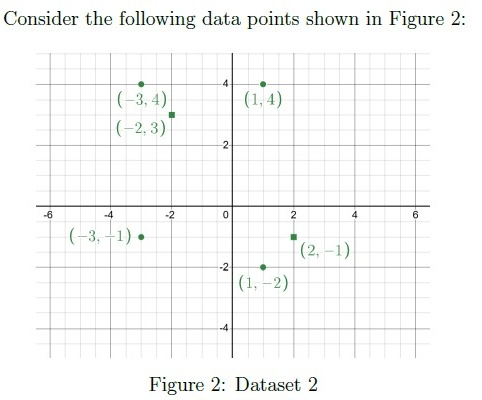
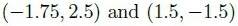
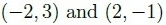
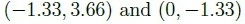
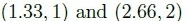
Answer key
- Q1 (MSQ, 2 marks): A, C
- Q2 (MSQ, 4 marks): B, D
- Q3 (MSQ, 4 marks): B, C, D
- Q4 (MSQ, 4 marks): A, D
- Q5 (MSQ, 3 marks): A, B, D
- Q6 (SA, 3 marks): 3
- Q7 (SA, 3 marks): 0.45 to 0.50
- Q8 (MCQ, 2 marks): B
- Q9 (SA, 2 marks): 4.5
- Q10 (SA, 2 marks): 0.5
- Q11 (MCQ, 3 marks): B
- Q12 (SA, 3 marks): 0.64 to 0.68
- Q13 (MCQ, 3 marks): A
- Q14 (SA, 2 marks): 1
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the Diploma-Level Machine Learning Techniques exam, based on the question paper. The focus is on clustering (K-means, Lloyd’s algorithm), PCA, Bayesian inference, and kernel methods.
1. Core Topics & Key Concepts
A. Clustering (K-means & Lloyd’s Algorithm)
Lloyd’s Algorithm (K-means):
Steps:
- Initialize cluster centers (e.g., randomly or via K-means++).
- Assign points to the nearest center (Euclidean distance).
- Recompute centers as the mean of assigned points.
- Repeat until convergence (centers stabilize or max iterations reached).
Properties:
- Convergence: Always converges to a local minimum (not necessarily global). (Question 2: Option A is true; Option B is false because it *always converges, though the solution may be suboptimal.)*
- Sensitivity to Outliers: Yes (Option C is true).
- Optimality: Not guaranteed (Option D is false).
- Initialization Matters: Different initializations can lead to different results.
K-means++ Initialization:
- First center chosen uniformly at random.
- Subsequent centers chosen with probability proportional to distance squared from existing centers.
- Reduces variance in clustering quality.
(Question 4: Probability of selecting (2,2) is higher due to distance from (0,0).)
Convergence Criteria:
- Stops when cluster assignments or centers change negligibly (e.g., below a threshold).
- (Question 14: Final cluster means depend on initialization.)
Tie-Breaking in K-means:
- Affects final clusters if points are equidistant to multiple centers.
- (Question 4: Option D is true.)
B. Principal Component Analysis (PCA)
- Key Idea: Linear dimensionality reduction by projecting data onto orthogonal axes (principal components) that maximize variance.
Steps:
- Standardize data (mean=0, variance=1).
- Compute covariance matrix: .
Eigen decomposition: , where:
- : Matrix of eigenvectors (principal components, sorted by eigenvalues).
- : Diagonal matrix of eigenvalues (variances along PCs).
- Project data onto top- eigenvectors: .
Variance Explained:
- Total variance = sum of all eigenvalues.
- Variance of -th PC = .
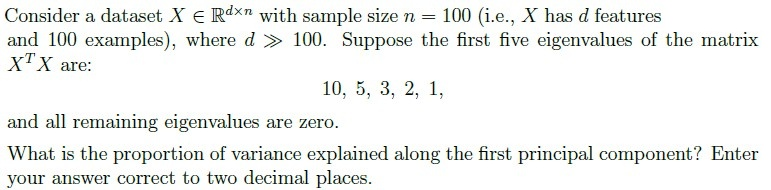
- (Question 3: For 6 points in 2D, covariance matrix has 2 non-zero eigenvalues. Top 6 PCs capture total variance only if all eigenvalues are non-zero.)
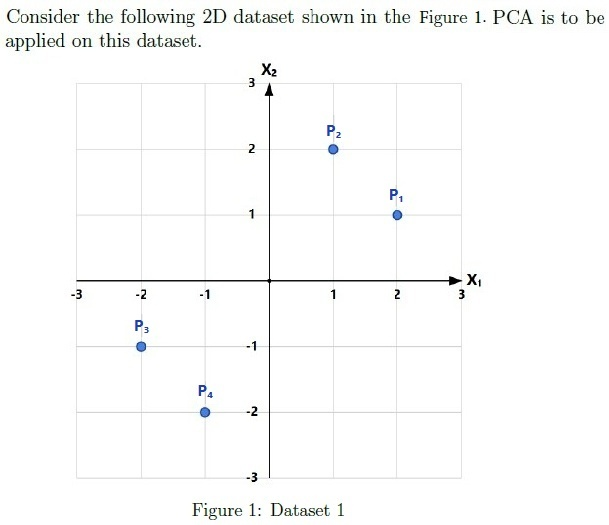
- (Questions 10–11: Variances along PC1 and PC2 are 4.5 and 0.5, respectively.)
Reconstruction:
- Zero residue only if all PCs are used (Question 3: Option C is false).
Covariance Matrix:
- For centered data , .
- (Question 9: Compute covariance from data.)
C. Bayesian Inference (Beta Distribution)
Beta Distribution:
- Prior for binomial proportions: .
- Posterior after observing successes in trials: .
- Posterior Mean: .
*(Question 5:
- For (uniform prior) and data, posterior mean ≈ 0.039.
- For , posterior mean ≈ 0.034.)*
D. Kernel Methods
- Kernel Trick: Map data to higher-dimensional space via , compute dot products efficiently using kernels .
Valid Kernels (must satisfy Mercer’s condition):
- Linear: .
- Polynomial: .
- Gaussian (RBF): .
- Sigmoid: .
- (Question 6: Options A, B, D are valid kernels.)
2. Key Equations
A. K-means
- Objective: Minimize within-cluster sum of squares (WCSS):
where is the mean of cluster .
B. PCA
- Covariance Matrix:
- Eigen Decomposition:
- Variance of PC:
- Total Variance:
C. Bayesian Posterior (Beta)
- Posterior Mean:
D. Kernel Functions
- Linear Kernel:
- Gaussian (RBF) Kernel:
Graph 2: Bayesian Inference & Kernels
Graph 3: Workflow for K-means and PCA
4. Exam Tips
K-means:
- Know how initialization (random vs. K-means++) affects convergence.
- Understand why it’s sensitive to outliers (uses Euclidean distance).
- Remember it converges to a local minimum, not necessarily global.
PCA:
- Always standardize data first.
- Eigenvalues = variances; eigenvectors = principal components.
- Total variance = sum of all eigenvalues.
Bayesian Inference:
- For Beta prior, posterior mean is .
- Uniform prior = Beta(1,1).
Kernels:
- Valid kernels must satisfy Mercer’s condition (symmetric, positive semi-definite).
- Common kernels: linear, polynomial, Gaussian, sigmoid.