Home / Past papers / MLT Quiz 2 / this paper
IIT M IMPROVEMENT AN EXAM QIV4 03 Aug - 03 Aug 2025
Elapsed 00:00

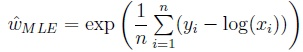
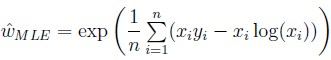
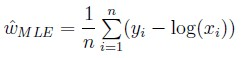
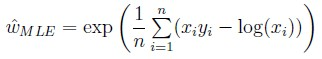
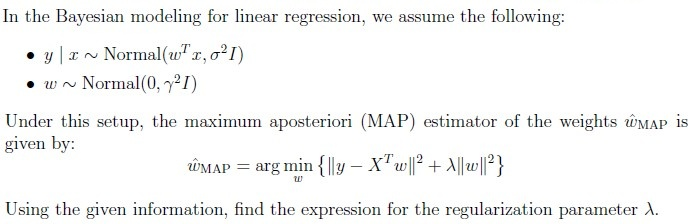
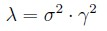


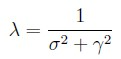
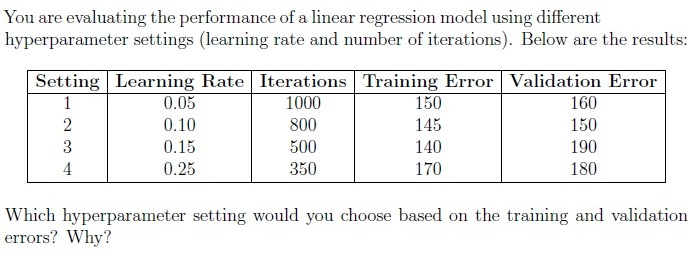
- Setting 3, because it has the lowest training error, indicating the best fit to thetraining data.
- Setting 2, because it has the lowest validation error and a relatively lowtraining error, indicating a good generalization.
- Setting 1, because it has the highest number of iterations and therefore likelyto be more stable.
- Setting 4, because it uses the highest learning rate and converges the fastest.
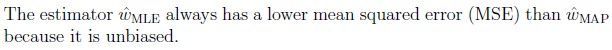
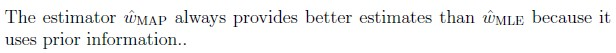
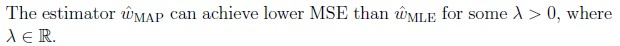
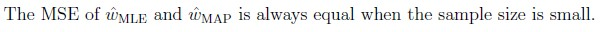
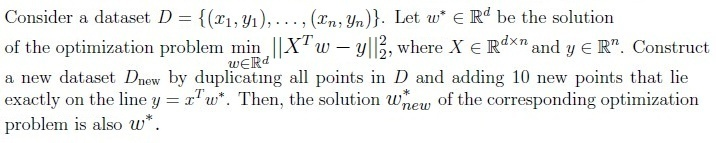
- TRUE
- FALSE
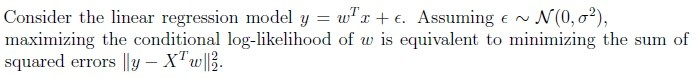
- TRUE
- FALSE

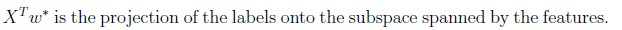
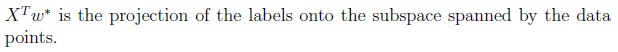
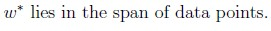
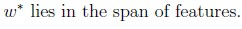
Which among the following are true?
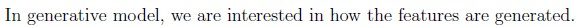
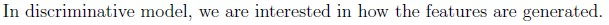
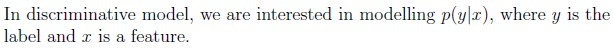
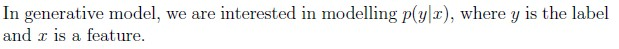
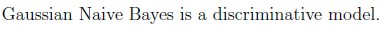
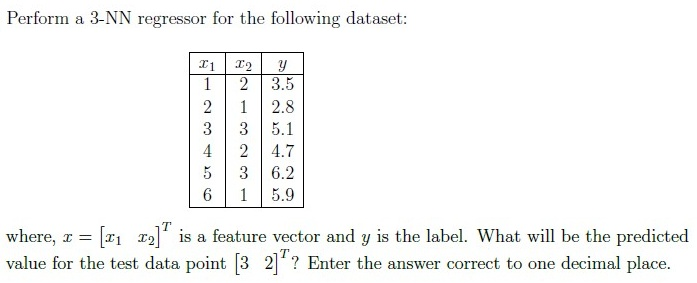
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
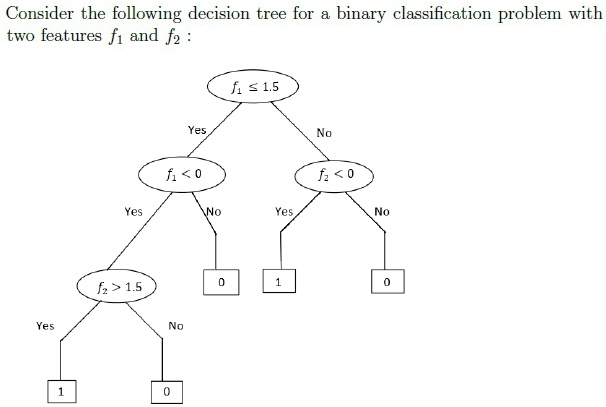
Which among the following represents the correct decision boundary for the decision tree?
Note: Here + represents the label 1 and − represents the label 0.
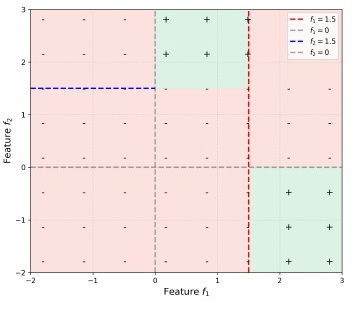
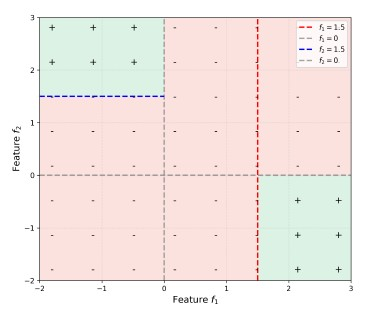
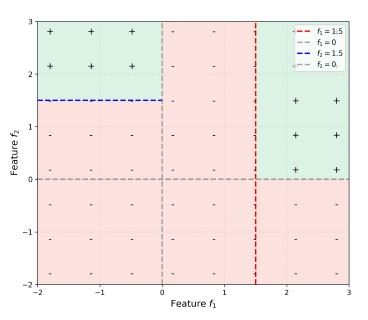
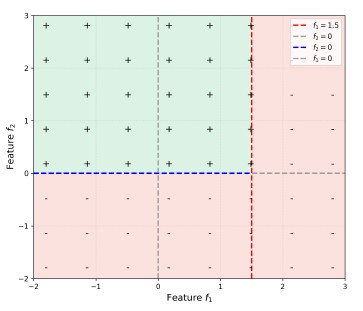
What will be the prediction for the new datapoint (2, 2)?
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
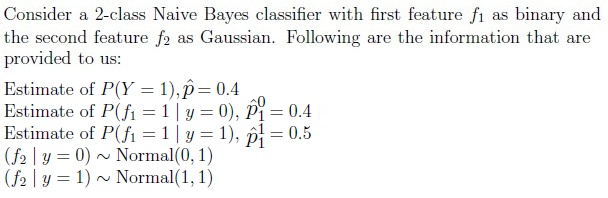
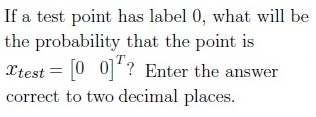
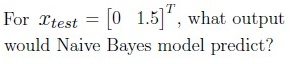
Comprehension passage - the questions below it refer to this
Suppose you want to build a decision tree to help diagnose a certain disease based on patient data. You have a dataset of 1000 patients labeled as either “positive” or “negative”. Here, positive represents patients with the disease and negative represents no disease. One of the feature used to diagnose is headache.
Below is the breakdown of the patients reporting headache: Headache present: 300 positive, 50 negative Headache not present: 100 positive, 550 negative
 Suppose you want to build a decision tree to help diagnose a certain disease based on patient data. You have a dataset of 1000 patients labeled as either “positive” or “negative”. Here, positive represents patients with the disease and negative represents no disease. One of the feature used to diagnose is headache.
Below is the breakdown of the patients reporting headache: Headache present: 300 positive, 50 negative Headache not present: 100 positive, 550 negative
Based on the above data, answer the given subquestions.
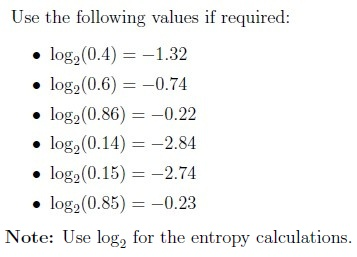
What is the entropy of the root node? Enter the answer correct to two decimal places.
What is the information gain for choosing the feature “headache” for splitting at the root node? Enter the answer correct to two decimal places.
Answer key
- Q1 (MCQ, 4 marks): A
- Q2 (MCQ, 3 marks): C
- Q3 (MCQ, 3 marks): B
- Q4 (MCQ, 3 marks): C
- Q5 (MCQ, 2 marks): A
- Q6 (MCQ, 1 marks): A
- Q7 (MSQ, 2 marks): A, C
- Q8 (MSQ, 2 marks): A, C
- Q9 (SA, 3 marks): 4.2
- Q10 (MCQ, 3 marks): B
- Q11 (SA, 2 marks): 0
- Q12 (SA, 2 marks): 0.22 to 0.26
- Q13 (SA, 3 marks): 1
- Q14 (SA, 3 marks): 0.95 to 0.99
- Q15 (SA, 4 marks): 0.34 to 0.38
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
1. Maximum Likelihood Estimation (MLE)
- Concept: MLE is a method of estimating the parameters of a statistical model by maximizing the likelihood function.
- Equation:
2. Maximum A Posteriori (MAP) Estimation
- Concept: MAP estimation is used to find the mode of the posterior distribution, incorporating prior information.
- Equation:
3. Linear Regression and Mean Squared Error (MSE)
- Concept: Linear regression models the relationship between a dependent variable and one or more independent variables. MSE is a common loss function for regression.
- Equation:
4. Model Evaluation and Hyperparameter Tuning
- Concept: Evaluating model performance using training and validation errors to choose optimal hyperparameters.
- Principle: Choose hyperparameters that minimize validation error while keeping training error relatively low to avoid overfitting.
5. Generative and Discriminative Models
- Concept: Generative models learn the joint probability distribution , while discriminative models learn the conditional probability distribution .
Examples:
- Generative Model: Gaussian Naive Bayes
- Discriminative Model: Logistic Regression
6. k-Nearest Neighbors (k-NN) Regression
- Concept: k-NN is a non-parametric method used for classification and regression. For regression, it predicts the value based on the average of the k-nearest neighbors.
- Example: For a test point , the predicted value is calculated based on the average of the 3 nearest neighbors.
7. Decision Trees
- Concept: Decision trees are used for classification and regression. They split the data based on features to make predictions.
- Equation: Entropy and Information Gain are used to determine the best splits.
8. Naive Bayes Classifier
- Concept: Naive Bayes is a probabilistic classifier based on Bayes' theorem with an assumption of independence between features.
- Equation: