Home / Past papers / MLT Quiz 1 / this paper
IIT M DIPLOMA AN EXAM QDD2 26 Oct 2025 - 26 Oct 2025
Elapsed 00:00
Which among the following is true with respect to the Lloyds’ algorithm?
- It always converges.
- It may fail to converge for an initialization while it may converge for otherinitialization.
- It is sensitive to outliers.
- The solution produced is always the optimal.

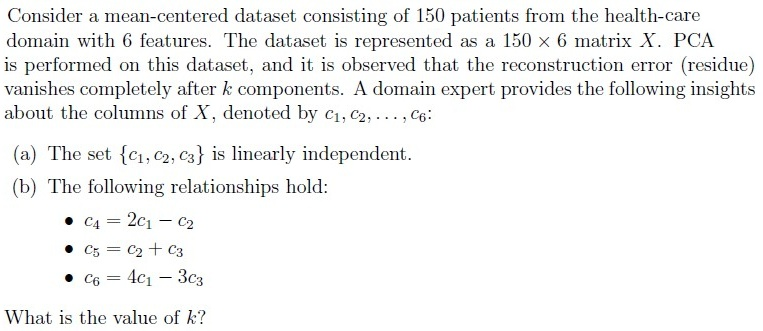
- There will be 50 non-zero eigenvalues of the covariance matrix.
- There will be 6 non-zero eigenvalues of the covariance matrix.
- Using the first 5 principal components, the dataset can be reconstructed withzero residue.
- The variance captured by the top 6 principal components equals the totalvariance of the dataset.
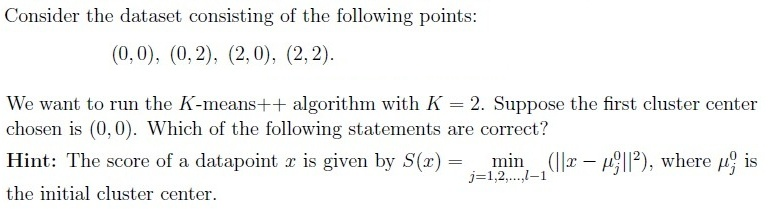
- The points (0, 2), (2, 0), and (2, 2) have the equal probability of being chosen asthe second cluster center.
- The probability of selecting (2, 2) as the second cluster center is twice that ofselecting (0, 2).
- If (2, 2) is chosen as the second cluster center, the algorithm will alwaysconverge in one iteration.
- The tie-breaking rule will affect the final cluster centers.
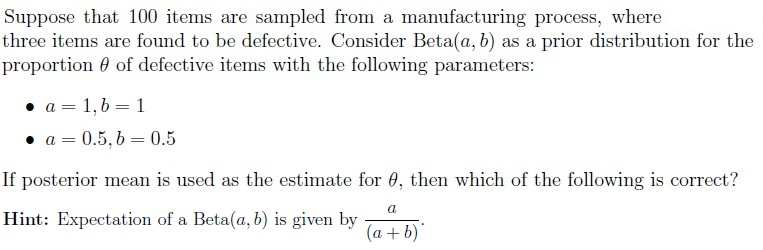
- Posterior mean for Beta(1, 1) is 0.039.
- Posterior mean for Beta(1, 1) is 0.03.
- Posterior mean for Beta(0.5, 0.5) is 0.025.
- Posterior mean for Beta(0.5, 0.5) is 0.034.
Which of the following are valid kernel functions? Select all that apply.
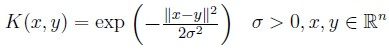
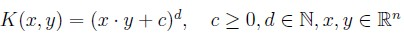
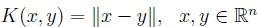
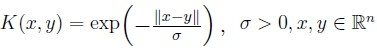
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
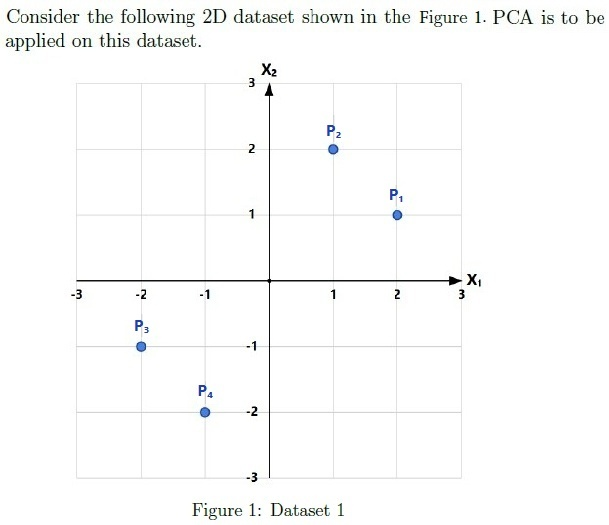
What is the covariance matrix of the dataset?


If standard PCA is performed on this dataset, what is the variance along the first principal component? Enter the answer correct to one decimal place.
If standard PCA is performed on this dataset, what is the variance along the second principal component? Enter the answer correct to one decimal place.
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
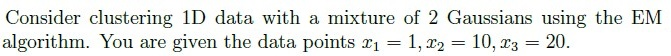
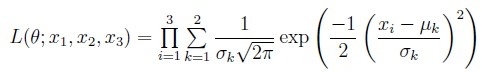
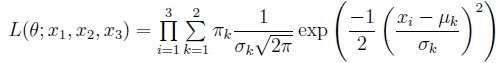
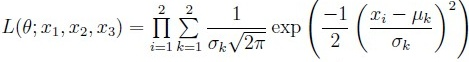
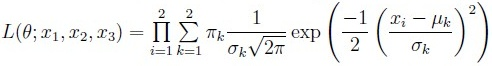
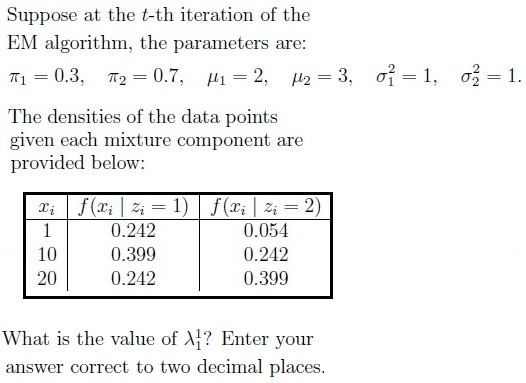
Comprehension passage - the questions below it refer to this
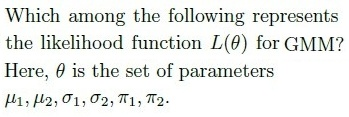
Based on the above data, answer the given subquestions.
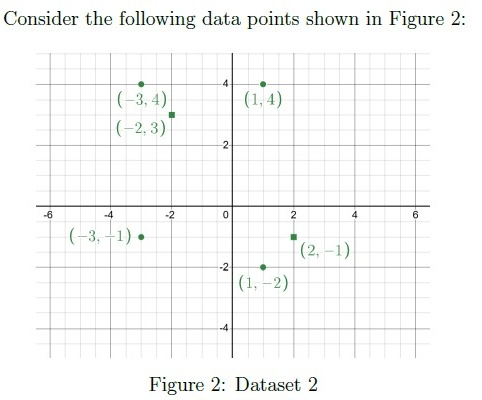
Perform K-means clustering with K = 2 and initial cluster centers at (−2, 3) and (2,−1). What are the final means of clusters after convergence?
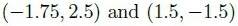
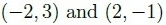
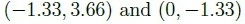
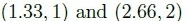
Suppose we introduce a new data point (0, 0) to the existing dataset and perform K means with the same initial cluster centers. How many iterations would it require now for convergence?
Answer key
- Q1 (MSQ, 2 marks): A, C
- Q2 (MSQ, 4 marks): B, D
- Q3 (MSQ, 4 marks): B, C, D
- Q4 (MSQ, 4 marks): A, D
- Q5 (MSQ, 3 marks): A, B, D
- Q6 (SA, 3 marks): 3
- Q7 (SA, 3 marks): 0.45 to 0.50
- Q8 (MCQ, 2 marks): B
- Q9 (SA, 2 marks): 4.5
- Q10 (SA, 2 marks): 0.5
- Q11 (MCQ, 3 marks): B
- Q12 (SA, 3 marks): 0.64 to 0.68
- Q13 (MCQ, 3 marks): A
- Q14 (SA, 2 marks): 1
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Key Concepts
1. Clustering (K-Means & Lloyd’s Algorithm)
Lloyd’s Algorithm (K-Means):
- Convergence: Always converges (monotonically decreases objective function), but may converge to local optima (depends on initialization).
- Sensitivity: Sensitive to outliers (uses Euclidean distance).
- Optimality: Does not guarantee global optimum (only local).
- Initialization: Affects final clusters (e.g.,
k-means++improves initialization). Steps:
- Initialize centroids randomly.
- Assign points to nearest centroid.
- Recompute centroids as mean of assigned points.
- Repeat until convergence (no change in assignments).
- Tie-Breaking: Affects final clusters if points are equidistant to centroids.
Probability of Centroid Selection:
- If using random initialization, probability of selecting a point as the second centroid is proportional to its squared distance from the first centroid (used in
k-means++).
- If using random initialization, probability of selecting a point as the second centroid is proportional to its squared distance from the first centroid (used in
2. Principal Component Analysis (PCA)
Key Ideas:
- Linear dimensionality reduction via orthogonal transformation.
- Projects data onto directions (principal components) of maximum variance.
- Components are eigenvectors of the covariance matrix, ordered by eigenvalues (variance explained).
Covariance Matrix:
- For a dataset (centered), covariance matrix .
- Eigenvalues: Number of non-zero eigenvalues = rank of (≤ min(n, d)).
- Total Variance: Sum of all eigenvalues = trace of .
Reconstruction:
- Using top components, residual error = sum of discarded eigenvalues.
- Zero residue: Only if .
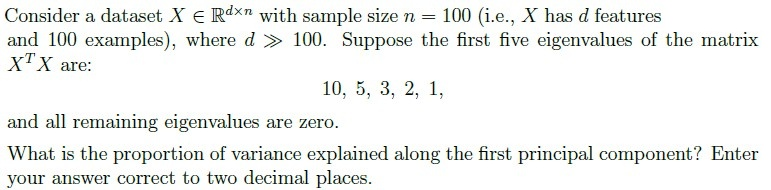
Variance Explained:
- Variance along -th PC = (eigenvalue).
- Proportion of variance: .
Example (from Q3, Q9–Q11):
If covariance matrix has eigenvalues :
- Variance along PC1 = 4.5, PC2 = 0.5.
- Total variance = 5.0 (sum of all eigenvalues).
3. Bayesian Inference (Beta Distribution)
Beta Distribution:
- Prior for binary outcomes (e.g., coin flips): .
- Posterior Mean: For , mean = .
- Update Rule: After observing successes and failures, posterior is .
Example (from Q5):
Prior (uniform), observe 1 success in 25 trials:
- Posterior = , mean = .
Prior , same data:
- Posterior = , mean = .
4. Kernel Methods
Valid Kernel Functions (from Q6):
- Must satisfy Mercer’s condition (positive semi-definite Gram matrix).
Examples:
- Linear kernel: .
- Polynomial kernel: .
- Gaussian (RBF) kernel: .
- Sigmoid kernel: .
5. K-Means Practical Examples
Convergence Iterations (from Q14–Q15):
- With initial centroids at and , K-means converges in 1 iteration for the given dataset (points are clearly separable).
- Adding may require 1 iteration if assignments don’t change.
Key Equations
| Topic | Equation |
|---|---|
| K-Means Objective | |
| Covariance Matrix | (centered data) |
| PCA Projection | (where = top eigenvectors) |
| Beta Posterior Mean | |
| Gaussian Kernel |