Home / Past papers / MLT End Term / this paper
IIT M DIPLOMA AN1 EXAM ETD1 11 Dec 2022 - 11 Dec 2022
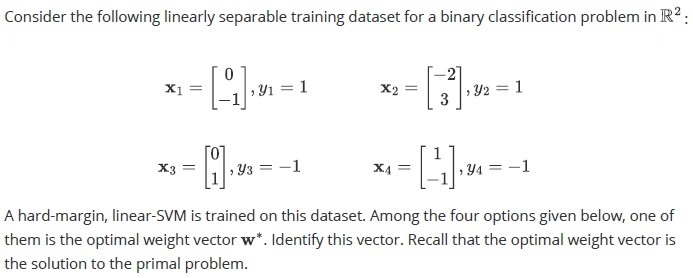
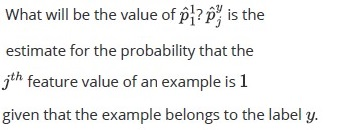
- 1, 3.9, 1, 4.2, 6.4, 1
- 0, 1, 0, 1, 1, 0
- -2.7, 0, -1.0, 0, 0, -7.3
- -1, +1, -1, +1, +1, -1
- 0, 3.9, 0, 4.2, 6.4, 0
- Number of features in the training data may be too low, try increasing them.
- Number of features in the training data may be too high, try reducing them.
- Learning rate may be too low; Try increasing it.
- Learning rate may be too high; Try reducing it.
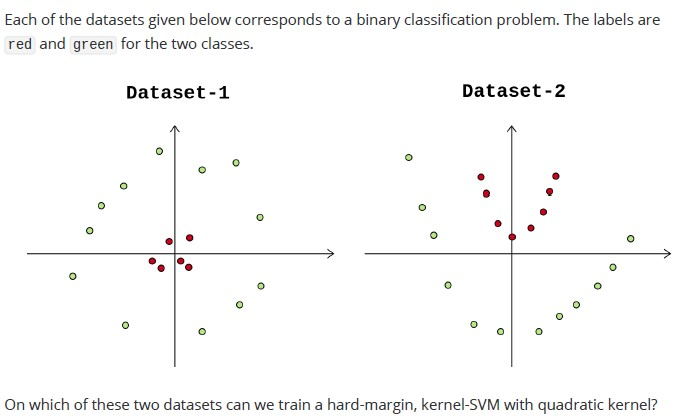
- Only dataset-1
- Only dataset-2
- On both dataset-1 and dataset-2
- Neither dataset-1 nor dataset-2
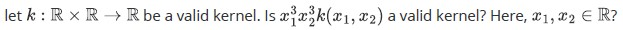
- Yes
- No
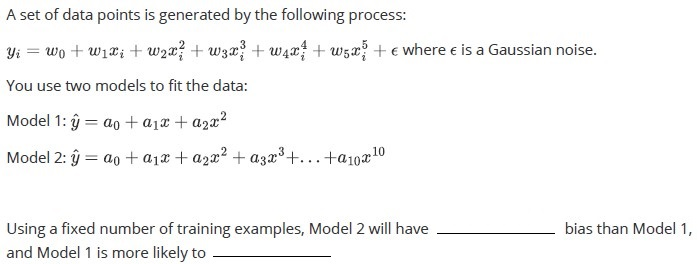
- Higher, underfit
- Lower, overfit
- Higher, overfit
- Lower, underfit


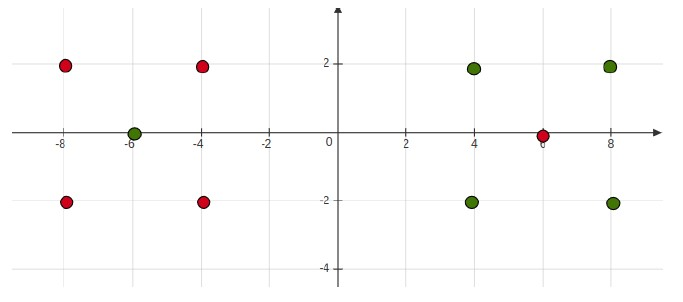 Consider the following data set: Which of the following will have lower leave-one-out cross-validation error?
- 1-Nearest Neighbor
- 3-Nearest Neighbor
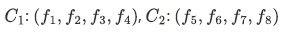
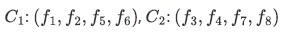
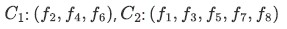
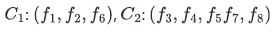
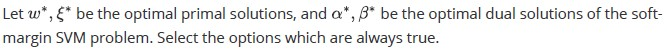




- A decision stump
- A decision stump with randomly selected features for splitting the nodes
- k -NN classifier with a smaller value of k.
- k-NN classifier with a larger value of k .
- A fully grown decision tree with randomly selected features for splitting thenodes
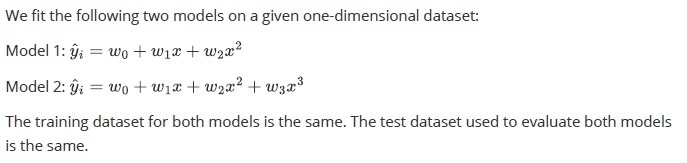
- Model 1
- Model 2
- Both will fit equally well
- Can not say
- Model 1
- Model 2
- It will depend upon the underlying distribution that generates the dataset andtherefore, can not say.
- Both will give the equal error



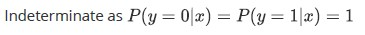
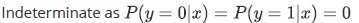
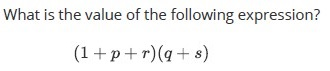
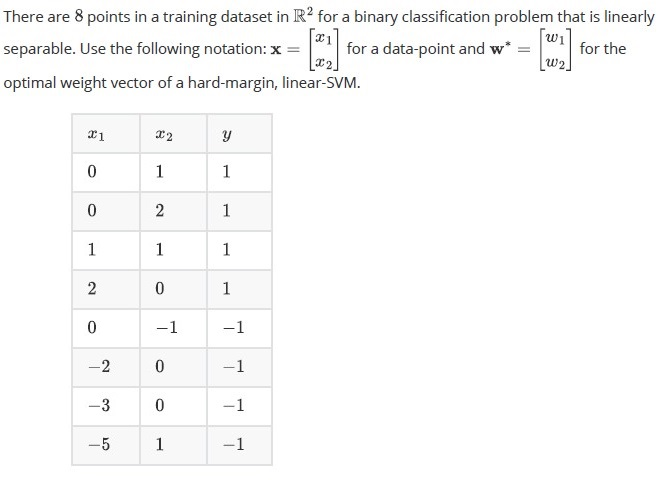
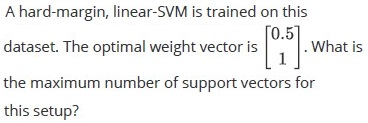
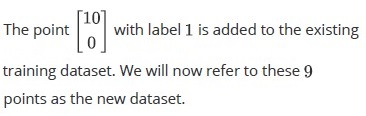

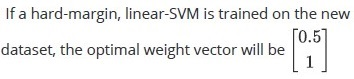
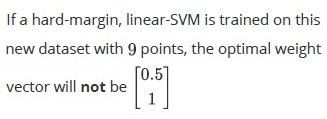
Answer key
- Q1 (MCQ, 3 marks): E
- Q2 (MCQ, 3 marks): D
- Q3 (MCQ, 4 marks): C
- Q4 (MCQ, 4 marks): A
- Q5 (MCQ, 4 marks): D
- Q6 (MCQ, 5 marks): A
- Q7 (MCQ, 5 marks): B
- Q8 (MCQ, 6 marks): D
- Q9 (MSQ, 5 marks): A, D
- Q10 (MSQ, 2 marks): C, E
- Q11 (SA, 5 marks): 40
- Q12 (SA, 5 marks): 16
- Q13 (SA, 4 marks): 106
- Q14 (MCQ, 2.5 marks): B
- Q15 (MCQ, 2.5 marks): C
- Q16 (SA, 3 marks): 12
- Q17 (MCQ, 3 marks): C
- Q18 (SA, 3 marks): 0
- Q19 (MCQ, 3 marks): D
- Q20 (SA, 3 marks): 2
- Q21 (SA, 3 marks): 4
- Q22 (SA, 1.5 marks): 2
- Q23 (SA, 1.5 marks): 2
- Q24 (SA, 1.5 marks): 4
- Q25 (SA, 2.5 marks): 2
- Q26 (SA, 2 marks): -1
- Q27 (SA, 2 marks): 0.23 to 0.27
- Q28 (SA, 3 marks): 0.31 to 0.35
- Q29 (SA, 4 marks): 4
- Q30 (MSQ, 4 marks): B, C
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of the core topics, concepts, principles, and equations essential for the Diploma-Level Machine Learning Techniques exam, along with a Mermaid knowledge graph to visualize relationships.
Core Topics & Key Concepts
1. Activation Functions
ReLU (Rectified Linear Unit):
- Definition:
- Outputs: for , for .
- Example: For inputs , outputs are (Q2).
2. Gradient Descent & Optimization
Learning Rate ():
- If loss increases, the learning rate is too high (divergence).
- Fix: Reduce (Q3).
Stochastic vs. Batch Gradient Descent:
- Batch: Uses entire dataset.
- Stochastic: Uses one sample per iteration.
3. Support Vector Machines (SVM)
Hard-Margin SVM
- Objective: Maximize margin for linearly separable data.
- Constraints: .
Kernel Trick:
- Quadratic Kernel: .
Valid Kernels: Must satisfy Mercer’s condition (Q5).
- If is a valid kernel, then is also valid.
Soft-Margin SVM
- Slack Variables (): Allow misclassification.
Dual Problem:
- (Lagrange multipliers) are nonzero only for support vectors.
- If , the point is misclassified or within margin (Q10).
4. Model Complexity & Bias-Variance Tradeoff
Bias:
- High Bias (Underfitting): Model is too simple (e.g., low-degree polynomial).
- Low Bias (Overfitting): Model is too complex (e.g., high-degree polynomial).
Example (Q6, Q15, Q16):
- Model 1: (higher bias, lower variance).
- Model 2: (lower bias, higher variance).
- Test Error: Depends on the true data distribution (Q16).
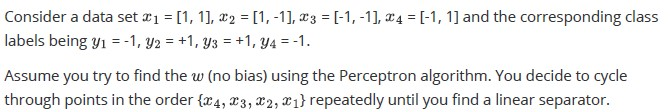
5. Perceptron Algorithm
Update Rule:
- if misclassified.
Mistake Bound:
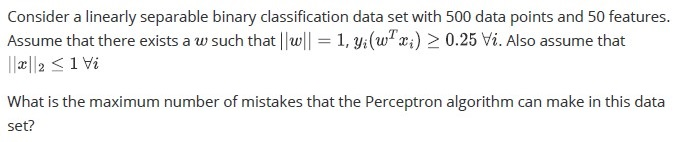
- For separable data with margin , max mistakes:
Example (Q13, Q21, Q22):
- Given , , and , max mistakes = 16.
- For 4 points in , Perceptron makes 2 mistakes and converges to with squared length 4.
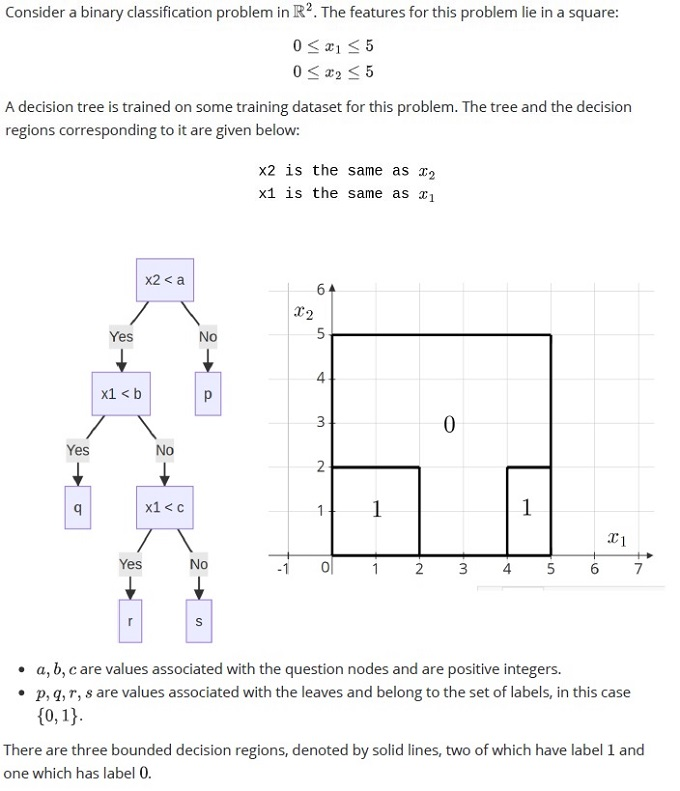
6. Decision Trees
Splitting Criteria:
- Gini impurity, entropy, or misclassification error.
Example (Q23-Q26):
Tree structure:
      x2 < a
     /      \
 x1 < b      p
 /    \
q     x1 < c
     /      \
    r        s
Decision Regions:
- , , (for given labels).
Leaf Values:
- .
- Expression: .
7. k-Nearest Neighbors (k-NN)
Leave-One-Out Cross-Validation (LOOCV):
- Lower error for higher (smoother decision boundaries).
- Example (Q8): 3-NN has lower LOOCV error than 1-NN.
8. Clustering (Lloyd’s Algorithm / k-Means)
Steps:
- Initialize centroids.
- Assign points to nearest centroid.
- Recompute centroids.
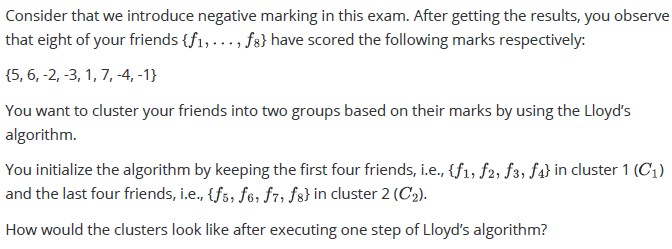
Example (Q9):
- Initial clusters: , .
- After 1 iteration: , .
9. Principal Component Analysis (PCA)
Covariance Matrix ():
- Diagonal entries = variances.
- Off-diagonal entries = covariances.
Principal Components:
- Eigenvectors of , ordered by eigenvalues.
Example (Q17, Q18):
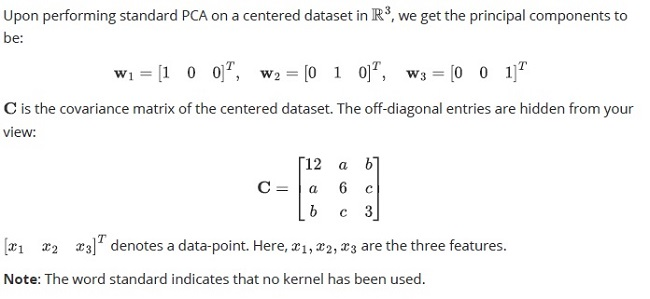
- Given , first PC variance = 12.
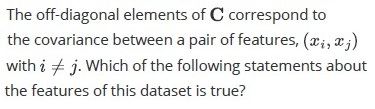
- If eigenvectors are standard basis, features are uncorrelated.
10. Naive Bayes
- Assumption: Features are conditionally independent given the class.
- Prediction:
Example (Q19, Q20):
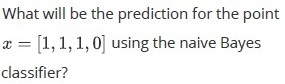
- If a feature is always 0, .
- Prediction for is indeterminate (zero probability).
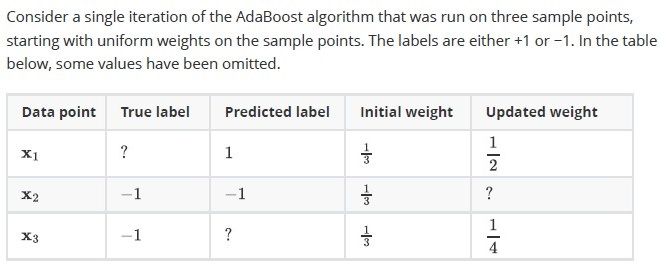
11. AdaBoost
Weight Update:
- Increase weights for misclassified points.
- .
Error Calculation:
- Training error = sum of weights of misclassified points.
Example (Q27-Q29):
- Initial weights: .
After 1 iteration:
- : weight = , true label = -1.
- : weight ≈ 0.25 (correctly classified).
- Training error ≈ 0.33.
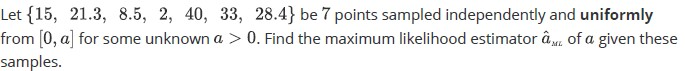
12. Maximum Likelihood Estimation (MLE)
Uniform Distribution:
- .
- MLE for : .
Example (Q12):
- Given samples , .
13. Ensemble Methods (Bagging)
Preferred Estimators:
- High variance, low bias models (e.g., deep decision trees, k-NN with small ).
Example (Q11):
- Decision stump with random features (reduces variance).
- k-NN with small (high variance, good for bagging).
14. Neural Networks
Parameter Count:
- For a network with layers, parameters = sum of (including biases).
Example (Q14):
- Input: 8, Hidden: 4 layers × 4 neurons, Output: 2.
- Total parameters = .
Key Equations
| Concept | Equation |
|---|---|
| ReLU | |
| SVM Margin | |
| Perceptron Update | (if misclassified) |
| Perceptron Mistake Bound | |
| PCA Variance | (top eigenvalue) |
| Naive Bayes Prediction | |
| MLE for Uniform | |
| AdaBoost Weight Update | |
| Neural Network Parameters |
Exam Tips
- SVM: Know the difference between hard-margin and soft-margin, and how kernels work.
- Perceptron: Understand the mistake bound and update rule.
- Decision Trees: Focus on splitting criteria and interpreting tree structures.
- PCA: Remember that principal components are eigenvectors of the covariance matrix.
- AdaBoost: Pay attention to weight updates and error calculations.
- Neural Networks: Count parameters carefully (include biases!).
- k-NN: Higher smooths decision boundaries (lower LOOCV error).