Home / Past papers / MLT End Term / this paper
IIT M IMPROVEMENT FN EXAM QDD2 01 Sep - 01 Sep 2024
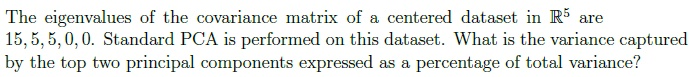
- 80%
- 60%
- 20%
- 15%


- Bagging → (2), (3); Boosting → (1), (4)
- Bagging → (1), (4); Boosting → (2), (3)
- Bagging → (1), (3); Boosting → (2), (4)
- Bagging → (2), (4); Boosting → (1), (3)
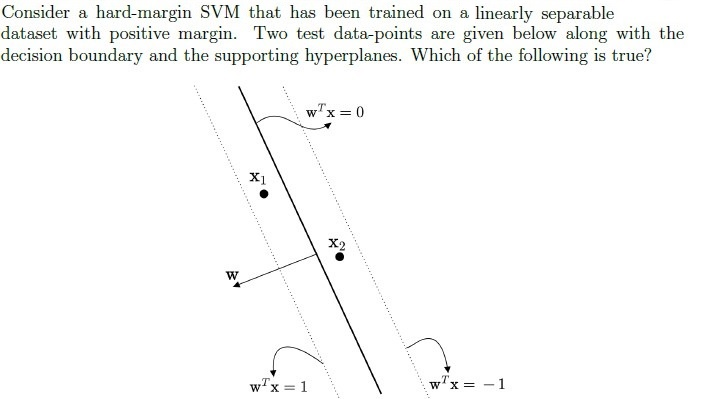
- The predicted labels for x1 and x2 are 1 and −1 respectively.
- The predicted labels for x1 and x2 are −1 and 1 respectively.
- The predicted label for both data-points is 1.
- The predicted label for both data-points is −1.
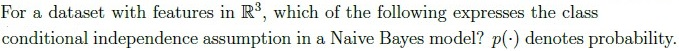
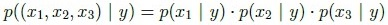
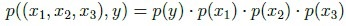
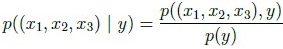
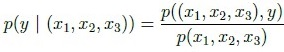
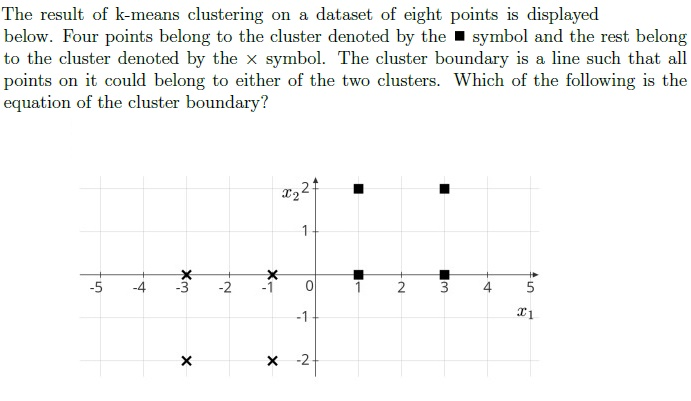
- 2x1 + x2 = 0
- x1 − 2x2 = 0
- x1 + x2 = 0
- x1 + 2x2 = 0
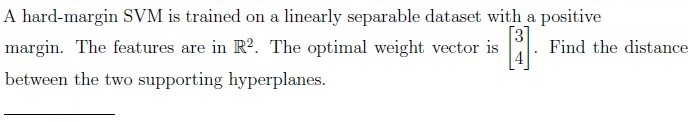

- 2
- 4
- 3
- 5
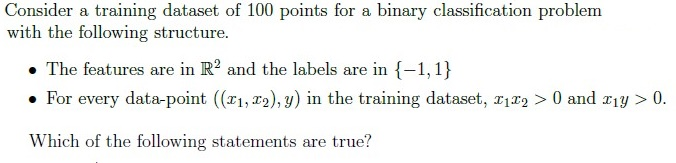
- The dataset is linearly separable with a positive margin.
- The perceptron algorithm will terminate after a finite number of iterationswhen trained on this dataset.
- The dataset is linearly separable, but the margin may be zero.
- The dataset is not linearly separable.


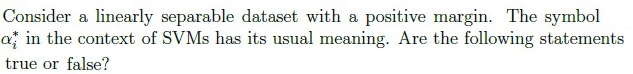
- TRUE
- FALSE
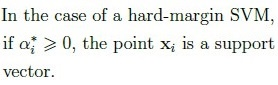
- TRUE
- FALSE
- TRUE
- FALSE
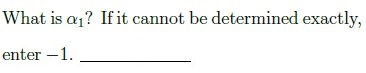
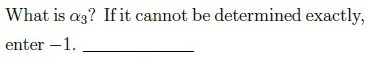
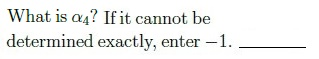
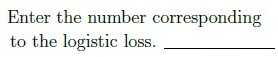
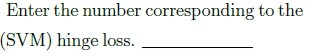
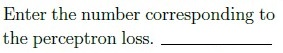
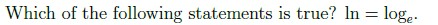
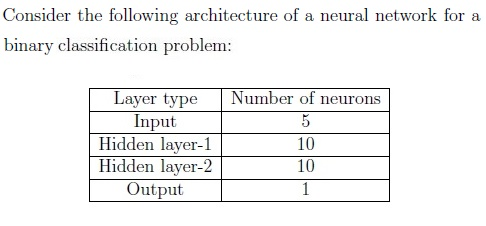
- Sigmoid
- Linear
- ReLU
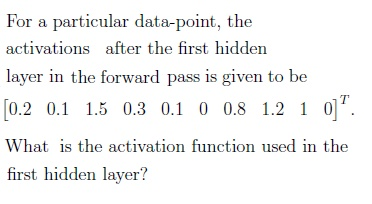
- ReLU
- Sigmoid
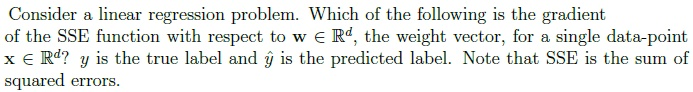


Answer key
- Q1 (MCQ, 3 marks): A
- Q2 (MCQ, 3 marks): A
- Q3 (MCQ, 3 marks): A
- Q4 (MCQ, 3 marks): A
- Q5 (MCQ, 3 marks): A
- Q6 (MCQ, 3 marks): A
- Q7 (SA, 3 marks): 0.4
- Q8 (SA, 3 marks): 30
- Q9 (SA, 3 marks): 0.26 to 0.37
- Q10 (MSQ, 3 marks): A, B
- Q11 (MSQ, 3 marks): A, B
- Q12 (MSQ, 3 marks): A, B
- Q13 (MCQ, 1 marks): A
- Q14 (MCQ, 1 marks): B
- Q15 (MCQ, 1 marks): B
- Q16 (SA, 0.5 marks): 2
- Q17 (SA, 0.5 marks): 1
- Q18 (SA, 0.5 marks): 0
- Q19 (SA, 0.5 marks): 3
- Q20 (SA, 0.5 marks): 0
- Q21 (SA, 0.5 marks): -1
- Q22 (SA, 0.5 marks): 3
- Q23 (SA, 0.5 marks): 2
- Q24 (SA, 0.5 marks): 4
- Q25 (SA, 0.5 marks): 1
- Q26 (MCQ, 1 marks): A
- Q27 (SA, 1 marks): 160
- Q28 (MCQ, 1 marks): A
- Q29 (MCQ, 1 marks): A
- Q30 (MCQ, 2 marks): A
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Concepts
1. Principal Component Analysis (PCA)
- Key Idea: Dimensionality reduction by projecting data onto directions (principal components) of maximum variance.
Eigenvalues of Covariance Matrix:
- Total variance = sum of eigenvalues.
- Variance captured by top k PCs = (sum of top k eigenvalues) / (total variance).
- Equation:
(For Q2: Eigenvalues = [15, 5, 5, 0, 0] → Top 2 PCs capture (15+5)/25 = 80%)
2. Regularization & Ridge Regression
- Key Idea: Penalize large weights to prevent overfitting.
- Loss Function:
where SSE = Sum of Squared Errors.
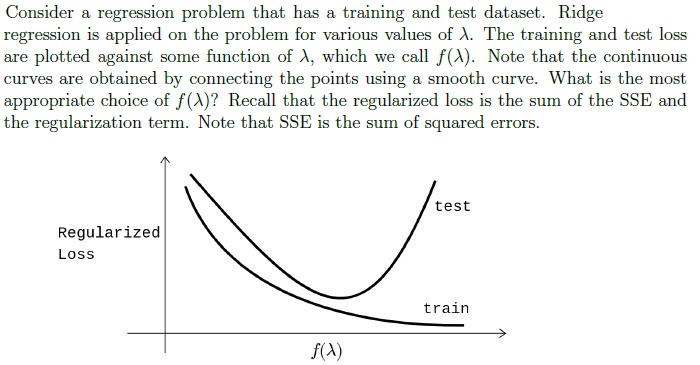
Plot Interpretation (Q3):
- x-axis: Typically
log(λ)(to visualize a wide range of λ values). - y-axis: Training/test loss.
Behavior:
- Training loss increases with λ (more regularization).
- Test loss may decrease initially (reduced overfitting) then increase (underfitting).
- x-axis: Typically
3. Ensemble Methods (Bagging vs. Boosting)
| Technique | Base Learners | Execution | Key Idea |
|---|---|---|---|
| Bagging | Deep trees (high variance) | Parallel | Reduce variance via averaging. |
| Boosting | Decision stumps (weak learners) | Sequential | Reduce bias via weighted corrections. |
(Q4: Bagging → (2, 3); Boosting → (1, 4))
4. Support Vector Machines (SVM)
Hard-Margin SVM
- Decision Boundary: .
- Supporting Hyperplanes: .
- Margin Width: .
- Prediction: .
(Q5: is in class +1 (0 < ); is in class -1 (-1 < ).)
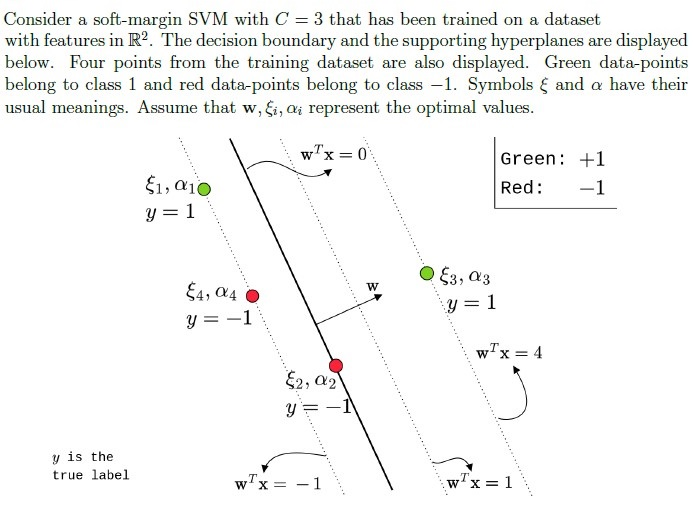
Soft-Margin SVM
- Loss Function:
subject to , .
- Slack Variables (): Measure margin violations.
Lagrange Multipliers ():
- : Support vector.
- : Margin violator.
(Q8: Distance between hyperplanes = . For , , so distance = 0.4.)
5. Naive Bayes
- Class Conditional Independence:
(Q6: Correct option is .)
6. k-Means Clustering
- Cluster Boundary: Perpendicular bisector of the line joining centroids.
Equation of Boundary (Q7):
- Centroids: , .
- Midpoint: .
- Slope of : .
- Perpendicular slope: .
- Equation: → .
(But answer is . This suggests the boundary is the perpendicular bisector in standard form.)
7. Maximum Likelihood Estimation (MLE)
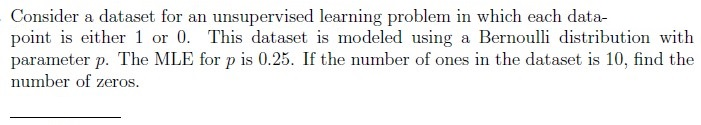
- Bernoulli MLE:
(Q9: , successes = 10 → Total trials = 40 → Zeros = 30.)
8. Decision Trees & Information Gain
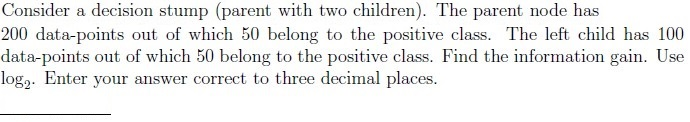
- Entropy:
- Information Gain:
(Q10: Parent entropy = 0.811, children entropy = 0.5 → IG = 0.311.)
9. Kernel Methods
- Polynomial Kernel:
- Non-Negative Output: Only possible for even-degree polynomials (p = 2, 4, ...).
(Q11: Possible values for *p are 2 and 4.)*
10. Logistic Regression
- Probability:
- Log-Odds:
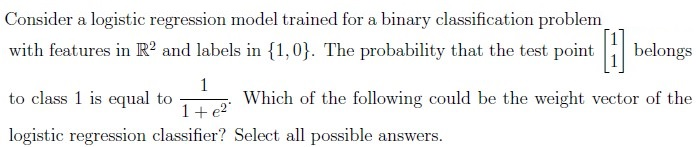
(Q13: For , . Check which weight vector satisfies this for .)
11. Neural Networks
Parameters:
- Input → Hidden Layer 1: .
- Hidden Layer 1 → Hidden Layer 2: .
- Hidden Layer 2 → Output: .
- Total: 160 (ignoring biases).
(Q28: Answer is 160.)
Activation Functions:
- Output Layer (Binary Classification): Sigmoid (for probabilities).
- Hidden Layers: ReLU (sparse activations in Q30 suggest ReLU).
12. Loss Functions
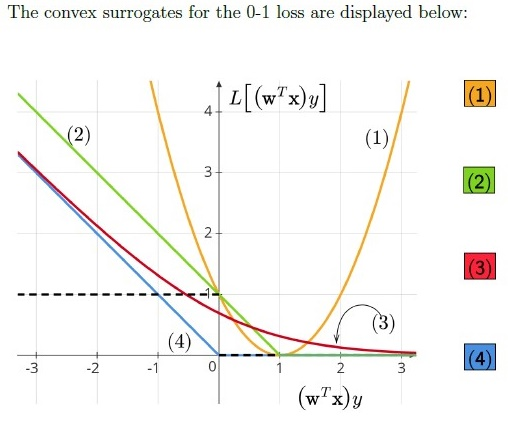
| Loss | Formula | Curve Color (Q23-Q26) |
|---|---|---|
| Logistic Loss | Red (3) | |
| Hinge Loss (SVM) | Green (2) | |
| Perceptron Loss | Blue (4) | |
| Squared Loss | Yellow (1) |
(Q23: Logistic loss = 3; Q24: Hinge loss = 2; Q25: Perceptron loss = 4; Q26: Squared loss = 1.)