Home / Past papers / MLP End Term / this paper
2023 Dec24: IIT M FN EXAM FDD2 - 24 Dec 2023
Elapsed 00:00
Consider the following Python code using Pandas:
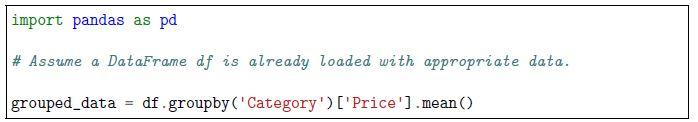 Consider the following Python code using Pandas: What does the groupby operation in the code achieve?
- It calculates the total price for each category.
- It calculates the average price for each category.
- It groups the data by the ’Category’ column.
- It filters out rows where the ’Price’ column is zero.
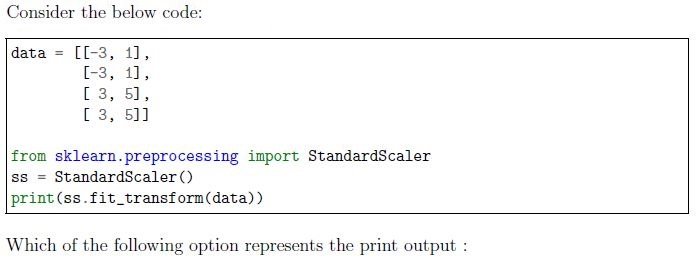

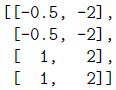

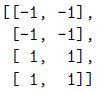
Which of the following metrics indicate higher their value, better the regression model’s performance?
- RMSE
- R2
- Mean absolute error
- Mean squared error
Which of the following variations of gradient descent can be implemented with SGDClassifier?
- stochastic gradient descent
- mini gradient descent
- full batch gradient descent
- None of these
Consider the Ridge regression model in scikit-learn, represented by the Ridge class. Which of the following statements about Ridge regression is correct?
- Ridge regression is designed to handle class imbalance of the dataset.
- The regularization term in Ridge regression is added to the sum of absoluteresiduals.
- Increasing the value of the regularization parameter (alpha) in Ridgeregression makes the model less sensitive to high-magnitude coefficients.
- Ridge regression is equivalent to Lasso regression when the regularizationparameter (alpha) is set to zero.
Which of the following method is used to estimate the probabilities in SGD-Classifier with suitable loss?
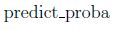
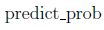
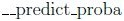
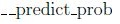

- Faster to compute the list of neighbors on scaled data.
- k-nearest neighbors is based on computing some distances. Features need tobe normalized to contribute approximately equally to the distance computation.
- Scaling the data has a negligible effect on k-nearest neighbor’s performance,but it enhances the interpretability of the model.
- This is irrelevant. One could use k-nearest neighbors without normalizing thedataset and get a very similar cross-validation score.
When using CountVectorizer in scikit-learn, what does the max_features parameter control?
- The maximum number of documents considered during vectorization.
- The maximum number of features (words) to be extracted based on termfrequency.
- The maximum number of randomly selected features (words).
- The maximum number of characters allowed in each document.
Which of these may NOT help in handling overfitting in decision trees?
- Increasing the value of min_samples_split
- Increasing the value of the pruning parameter
- Increasing the value of min_samples_leaf
- Increasing the depth of the tree
Which of the following is/are Clustering Method.
- Connectivity-based Clustering
- Centroids-based Clustering
- Density-based Clustering
- All of them
You’re working with a large image and want to group similarly coloured segments in the image together. No other information is provided with the image. Which of the following techniques will you use to accomplish the task?
- Supervised learning
- Unsupervised learning
- Reinforcement learning
- None of these
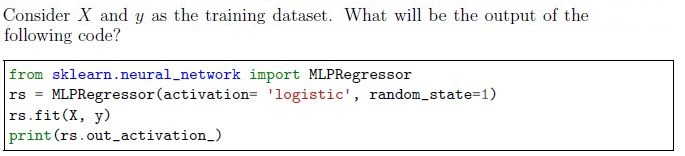
- logistic
- relu
- identity
- tanh
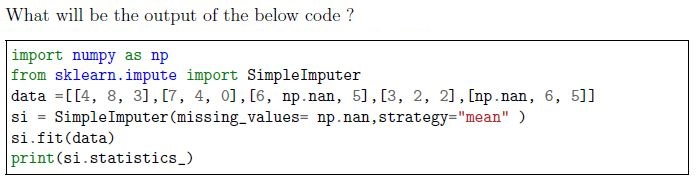
- [5, 5, 3.75]
- [5, 5, 3]
- [4, 4, 3]
- [4, 4, 3.75]
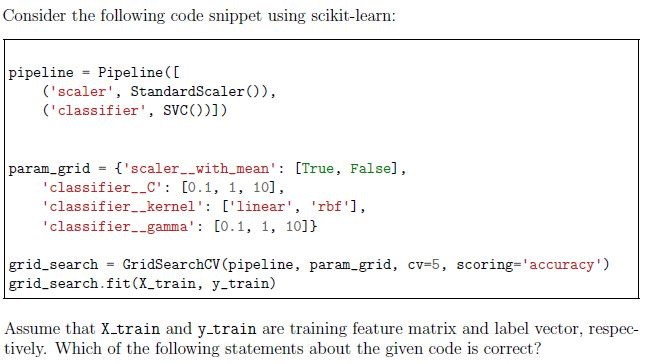
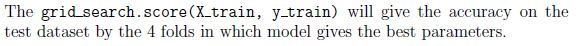

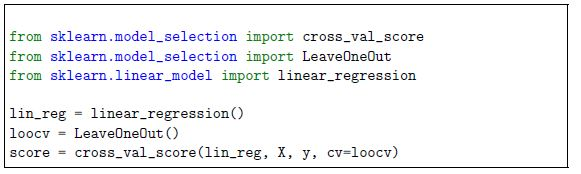
Which of the following code snippets represent correct methods to obtain cross validated performance measure using LeaveOneOut?
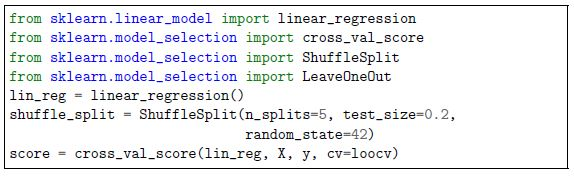
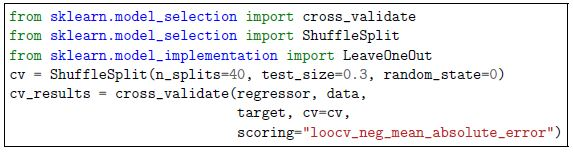
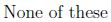
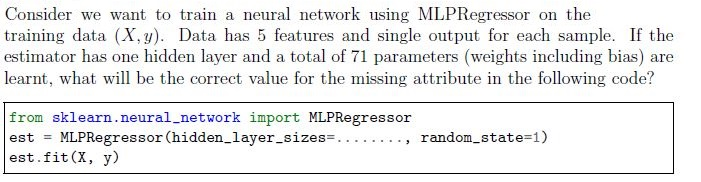
- (71)
- (71, 1)
- (10)
- (10, 2)
You’re building an ‘MLPClassifier‘ for a dataset with a large number of features. The goal is to predict whether a patient is going to have parkinson disease in next 12 months. You’re trying to decide the appropriate number of neurons in the hidden layers of the neural network. Which statement about adjusting the hidden_layer_sizes parameter is correct?
- Increasing the number of neurons in hidden layers will always lead to bettermodel performance.
- Decreasing the number of neurons in hidden layers reduces the model’scapacity to capture complex patterns.
- The number of neurons in hidden layers does not significantly affect themodel’s performance.
- Finding the optimal number of neurons is a trial-and-error process and mayrequire experimentation.
Which of the following code snippet can correctly plot the elbow graph for feature matrix X (k value is taken from 1 to 10)?
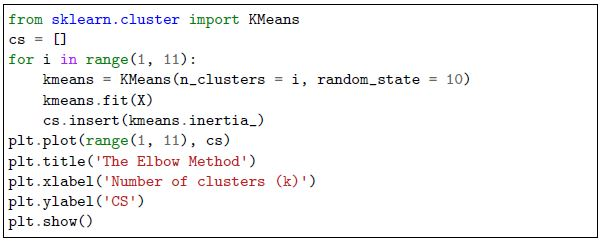
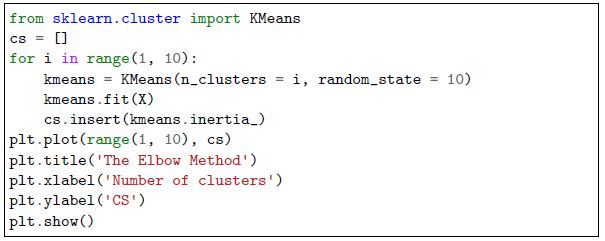
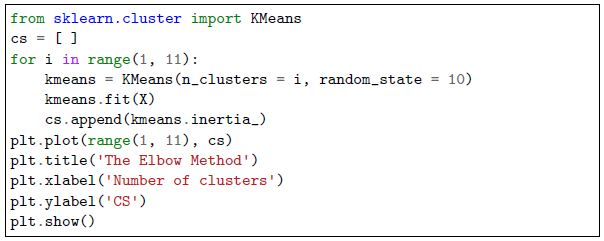
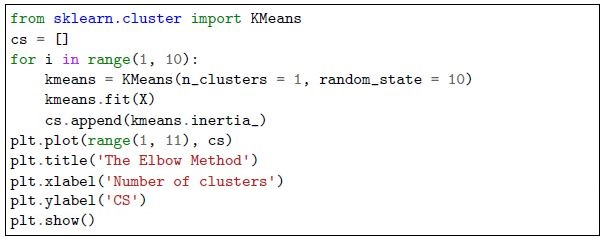
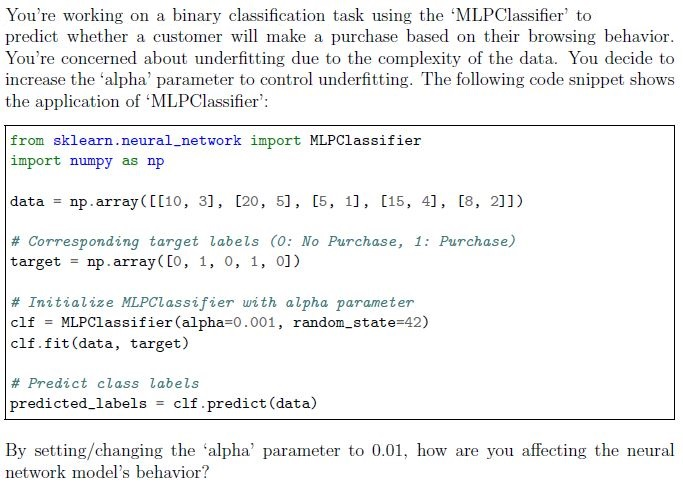
- Increasing the model’s complexity to fit the training data more closely.
- Adding a stronger regularization term to the loss function, discouragingcomplex models.
- Making the model more capable to learn more complex behaviour.
- Adjusting the learning rate to control convergence speed.
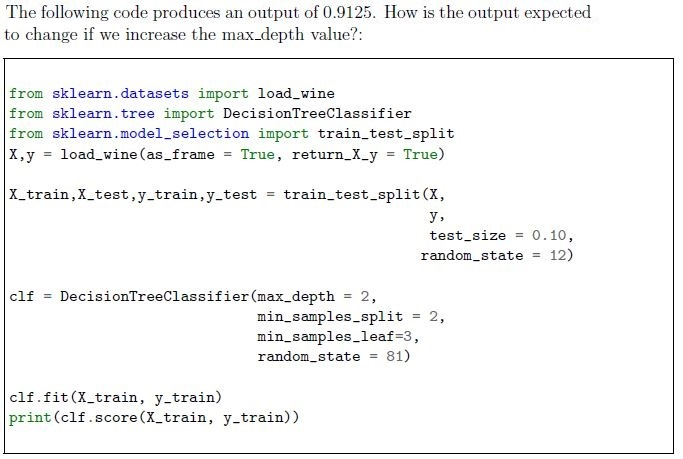
- Output score is likely to increase.
- Output score is likely to decrease.
- Output score may increase or decrease.
- Output score will remain the same.
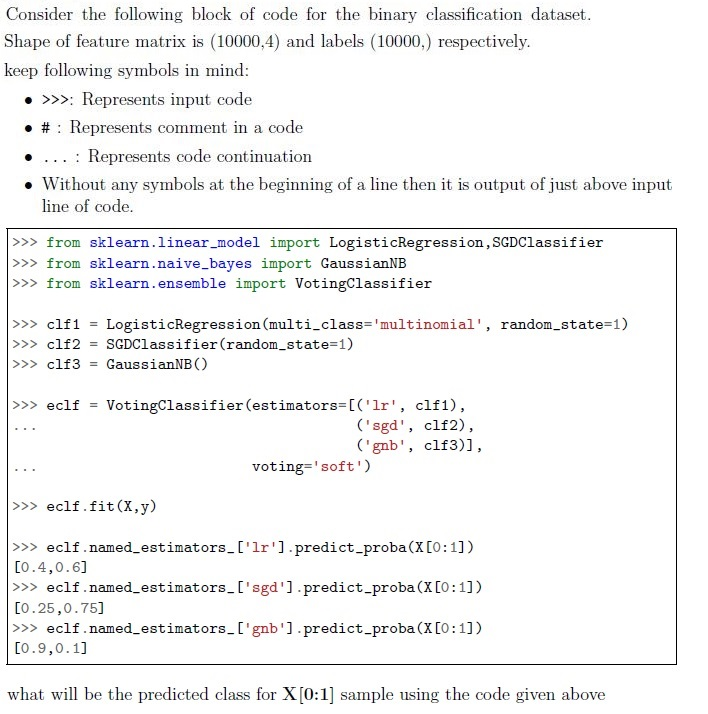
- 0
- 1
- 2
- 3
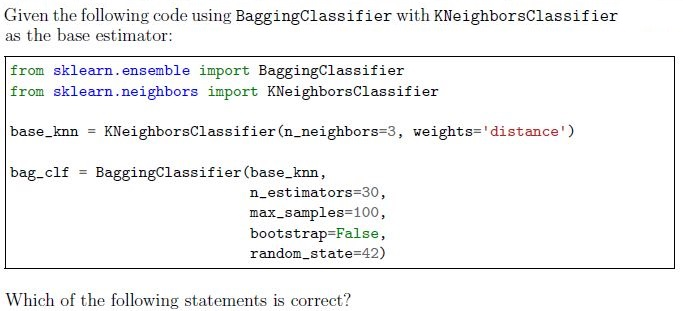
- Above code uses bootstrapping to generate samples for each base classifier.
- model will be tested on out of the bags samples.
- Due to weights=’distance’, each base KNN classifier will treat all neighborsequally in terms of voting power.
- The ensemble will consist of 3 base KNN classifiers.
- None of these
Consider a dataset representing various attributes of red wine, loaded into a Pandas DataFrame named data using the following code:
 Consider a dataset representing various attributes of red wine, loaded into a Pandas DataFrame named data using the following code: Suppose we are interested in extracting the value of the chlorides attribute for the third sample in the dataset (2nd by index). Which of the following expressions correctly achieves this? chlorides is at the 4th index of columns.
- data.chlorides[2]
- data[’chlorides’][2]
- data[2][4]
- data.iloc[2, 4]
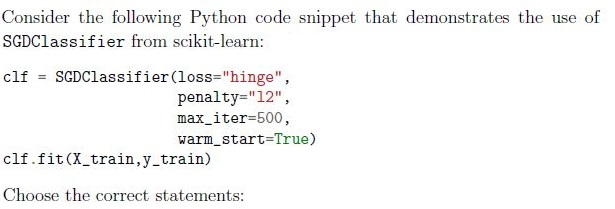
- It applies lasso penalty.
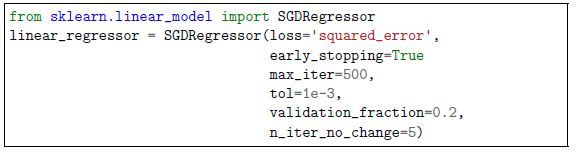
- The training may terminate after 499 iterations or lesser
- the classifier represents a perceptron model
- The classifier’s model parameters will initialized with parameters learnt fromprevious call to fit() function, if the same object is trained/fitted multiple times on new data.
Which of the following observations warrant use of SGD model?
- The data set size is 1000 GB.
- The model has to be trained in non-iterative manner.
- The model must be a decision tree.
- The model must be a logistic regressor.
- None of these
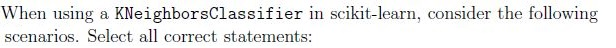
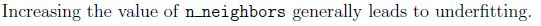
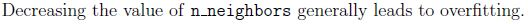
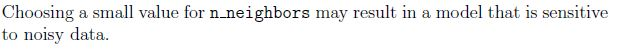
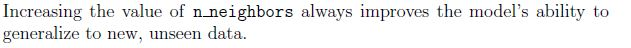
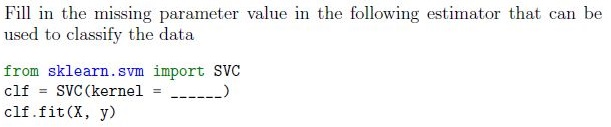
- ‘poly’,
- ‘lasso’
- ‘rbf’,
- ‘scale’
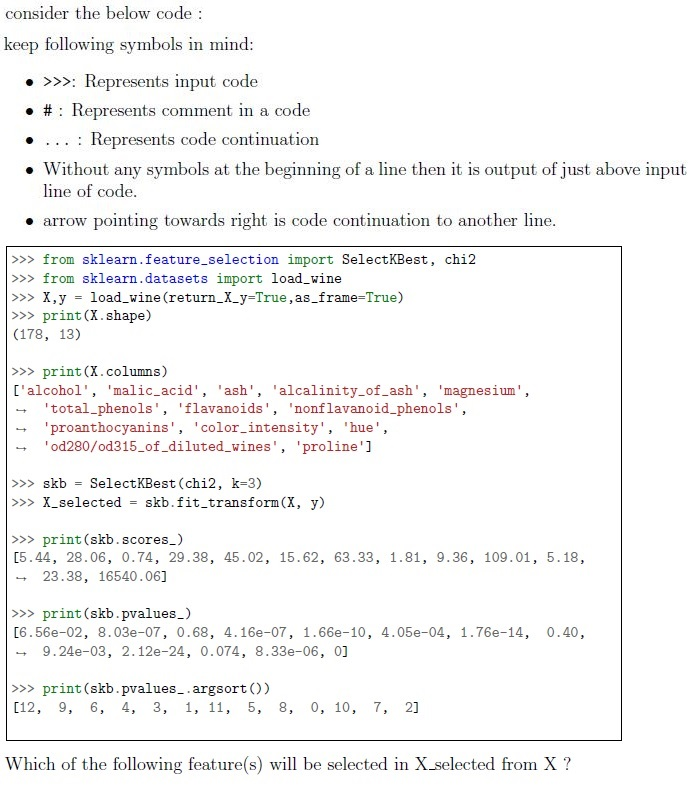
- malic_acid
- magnesium
- flavanoids
- proanthocyanins
- color_intensity
- proline

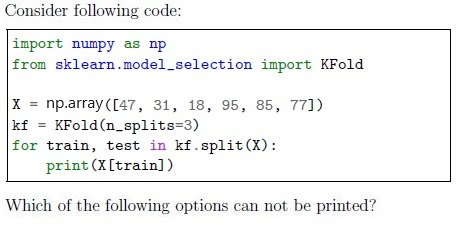
- [47, 31, 18, 95, 77]
- [47, 31, 18 ]
- [31, 41, 18, 95, 85, 77]
- [31, 41, 85, 31]
- [18, 95, 85, 77]
- [47, 31, 18, 85]
- None of these
When using a Support Vector Classifier (SVC) in scikit-learn with different values of the regularization parameter (C), how does the complexity of the decision boundary change? Select all correct statements:
- Smaller values of C result in a more complex decision boundary.
- Larger values of C result in a more complex decision boundary.
- The decision boundary becomes simpler with increasing values of C.
- Very large values of C may lead to overfitting.
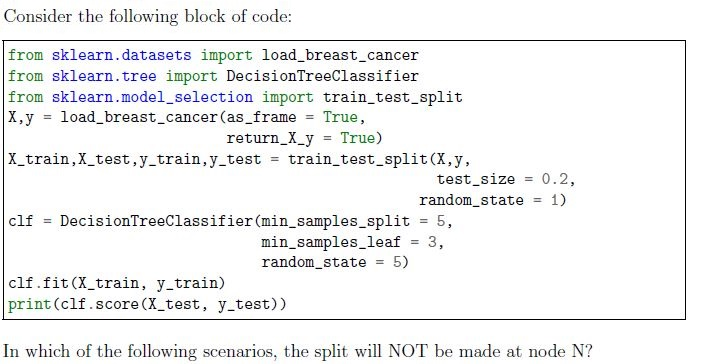
- Number of samples at node N = 10. If it is split, it will result in 2 nodes in theleft child and 8 nodes in the right child.
- Number of samples at node N = 6. If it is split, it will result in 3 nodes in the leftchild and 3 nodes in the right child.
- Number of samples at node N = 12. If it is split, it will result in 5 nodes in theleft child and 7 nodes in the right child.
- Number of samples at node N = 4. If it is split, it will result in 3 nodes in the leftchild and 1 node in the right child.
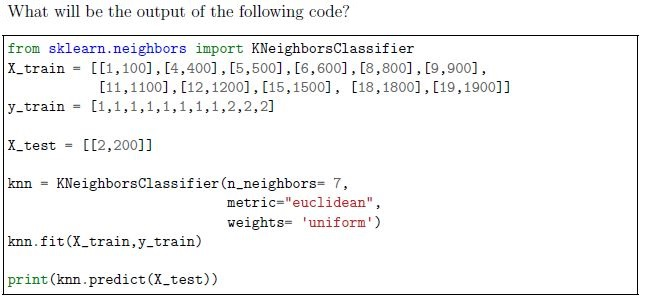
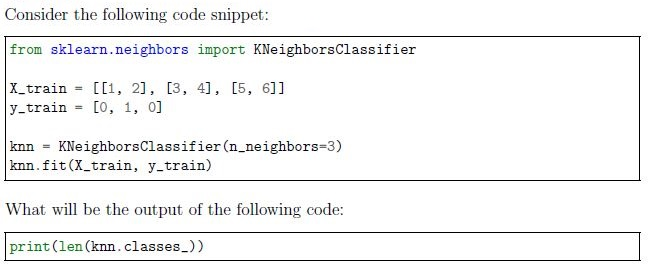
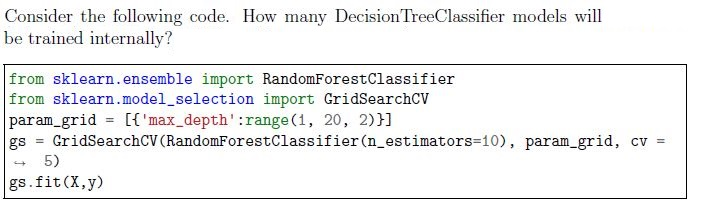
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
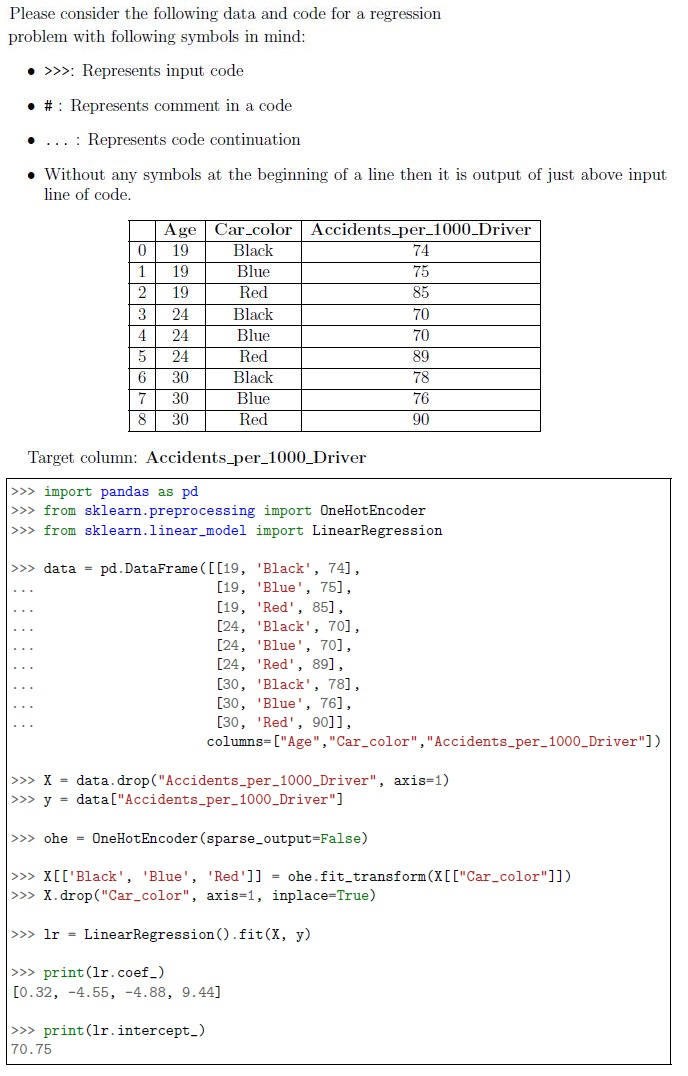
How many Accidents per 1000 Driver happens for Age 25 and driving blue car ?
To improve the given model which of the following preprocessing step you suggest?
- StandardScaler()
- OrdinalEncoder()
- MinMaxScaler()
- LabelEncoder()
Answer key
- Q1 (MCQ, 2 marks): B
- Q2 (MCQ, 2 marks): D
- Q3 (MCQ, 2 marks): B
- Q4 (MCQ, 2 marks): A
- Q5 (MCQ, 2 marks): C
- Q6 (MCQ, 2 marks): A
- Q7 (MCQ, 2 marks): B
- Q8 (MCQ, 2 marks): B
- Q9 (MCQ, 2 marks): D
- Q10 (MCQ, 2 marks): D
- Q11 (MCQ, 2 marks): B
- Q12 (MCQ, 2 marks): C
- Q13 (MCQ, 3 marks): B
- Q14 (MCQ, 3 marks): B
- Q15 (MCQ, 3 marks): A
- Q16 (MCQ, 3 marks): C
- Q17 (MCQ, 3 marks): D
- Q18 (MCQ, 3 marks): C
- Q19 (MCQ, 3 marks): C
- Q20 (MCQ, 4 marks): A
- Q21 (MCQ, 4 marks): B
- Q22 (MCQ, 4 marks): E
- Q23 (MSQ, 2 marks): A, B, D
- Q24 (MSQ, 2 marks): B, D
- Q25 (MSQ, 2 marks): A, D
- Q26 (MSQ, 2 marks): A, C
- Q27 (MSQ, 2 marks): A, C
- Q28 (MSQ, 3 marks): C, E, F
- Q29 (MSQ, 3 marks): A, C, D
- Q30 (MSQ, 3 marks): A, B, C, D
- Q31 (MSQ, 3 marks): B, D
- Q32 (MSQ, 4 marks): A, D
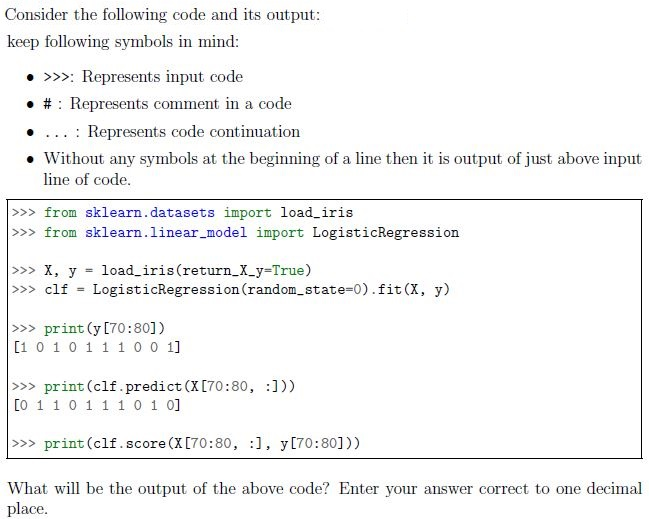
- Q33 (SA, 3 marks): 0.6
- Q34 (SA, 3 marks): 1
- Q35 (SA, 2 marks): 2
- Q36 (SA, 4 marks): 500
- Q37 (SA, 3 marks): 73 to 75
- Q38 (MSQ, 2 marks): A, C