Home / Past papers / MLP Quiz 2 / this paper
IIT M DIPLOMA AN EXAM QDD3 01 Dec 2024 - 01 Dec 2024
Elapsed 00:00
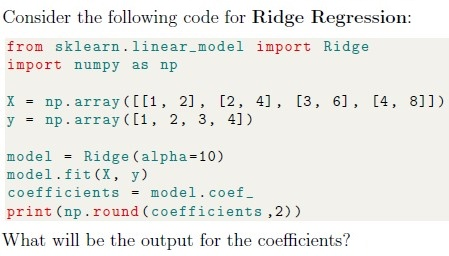


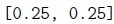

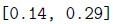
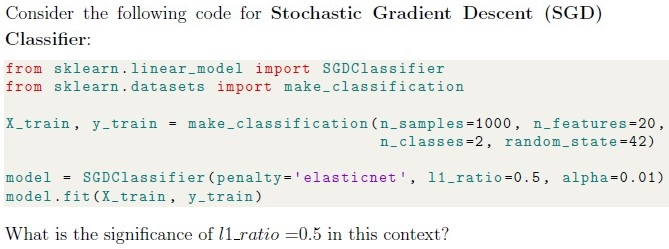
- It assigns equal weightage to L1 and L2 regularizations.
- It applies only L2 regularization.
- It applies only L1 regularization.
- It disables regularization completely.
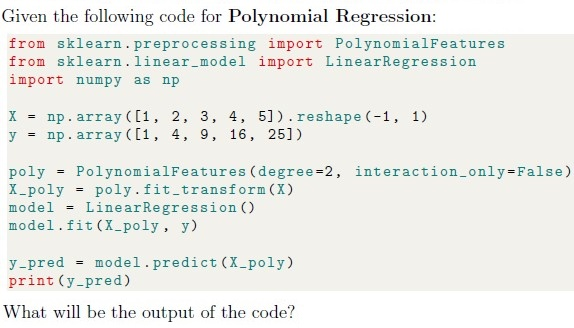
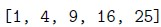
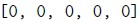
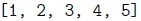
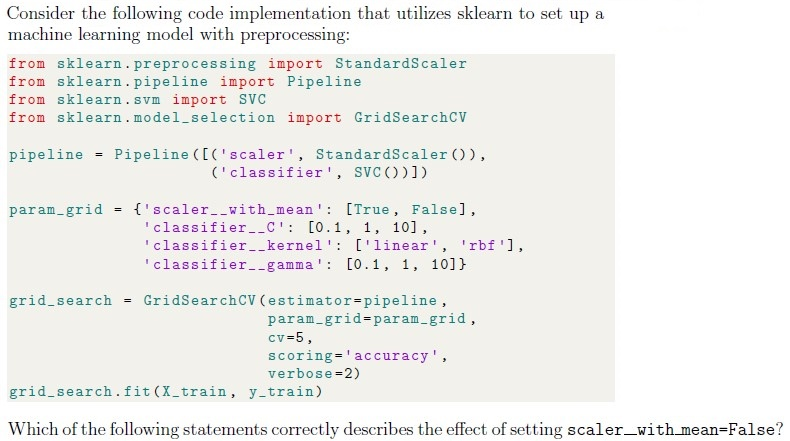
- The data will be standardized without centering, preserving the mean of thedataset.
- The data will be centered but not scaled, leading to variance issues.
- The parameter has no effect; the data will always be centered regardless ofthis setting.
- The scaling operation will be disabled entirely, leaving the data unchanged.
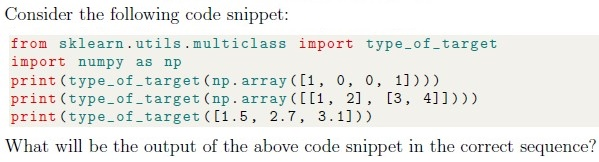
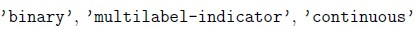
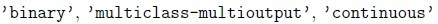
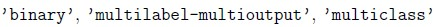
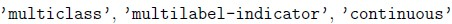
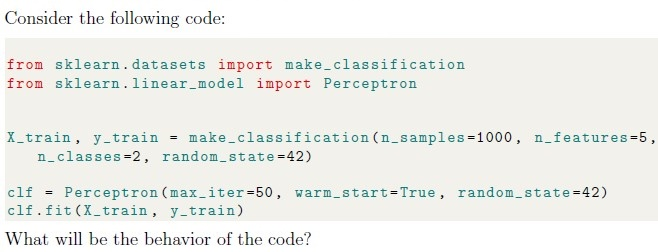
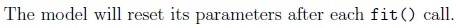
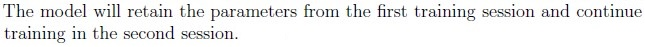
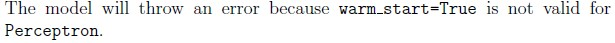
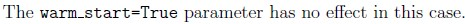
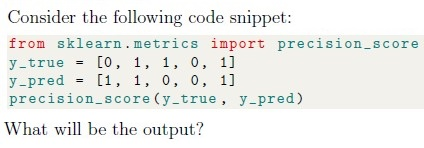
- 0.75
- 0.80
- 0.50
- 0.67
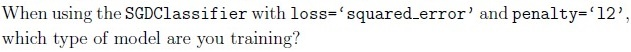
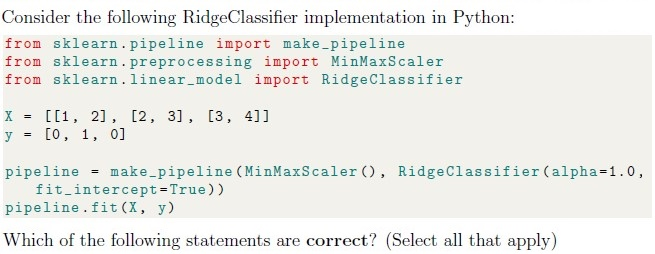
- LogisticRegression
- Perceptron
- RidgeClassifier
- Support Vector Machine (SVM)
- LassoClassifer
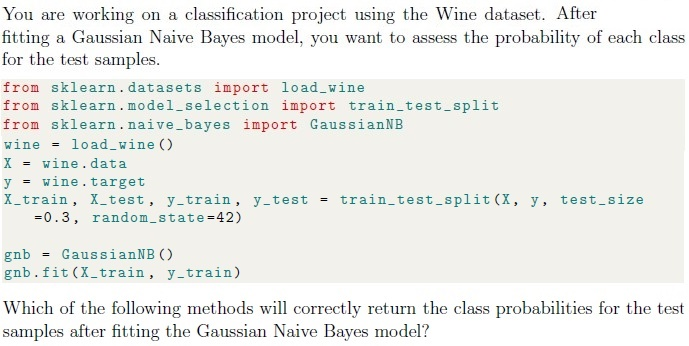

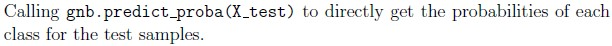
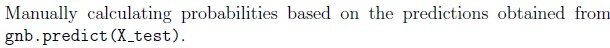

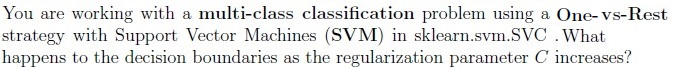
- The boundaries become more complex and tightly fitted to the training data.
- The boundaries become more regular and smooth.
- Decision boundaries are unaffected by C.
- The number of support vectors decreases.
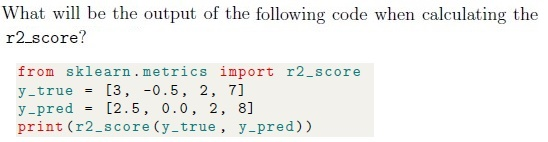
- 0.99
- 0.87
- 0.95
- 0.80
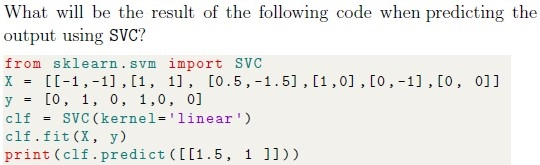


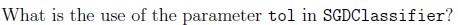
- It defines the tolerance for stopping criteria.
- It defines the learning rate schedule.
- It controls regularization strength.
- It controls the number of iterations.

- ’linear’
- ’quadratic’
- ’rbf’
- ’sigmoid’
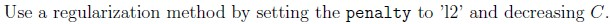
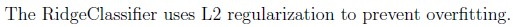

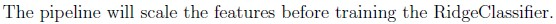
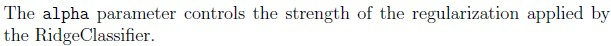


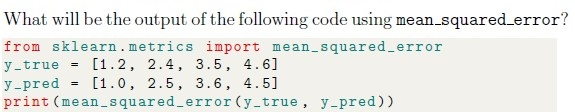
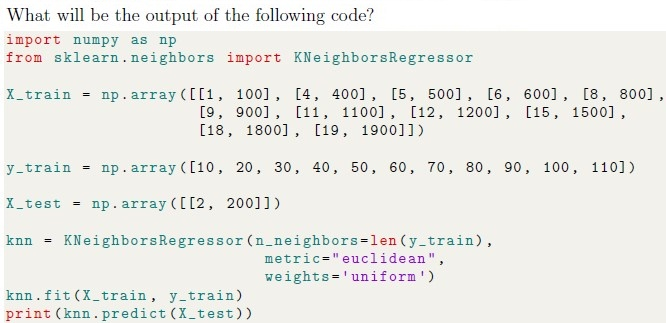
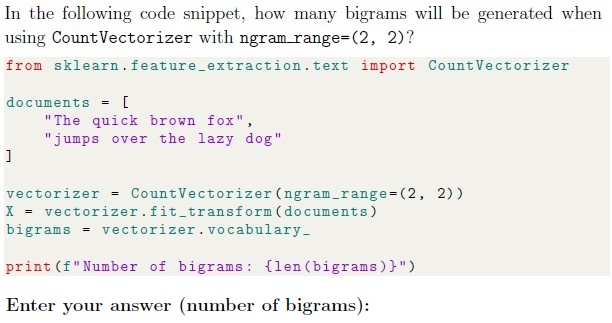
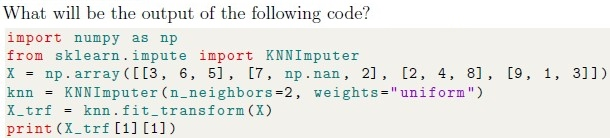
Answer key
- Q1 (MCQ, 3 marks): E
- Q2 (MCQ, 3 marks): A
- Q3 (MCQ, 3 marks): A
- Q4 (MCQ, 3 marks): A
- Q5 (MCQ, 2 marks): B
- Q6 (MCQ, 2 marks): B
- Q7 (MCQ, 2 marks): D
- Q8 (MCQ, 2 marks): C
- Q9 (MCQ, 2 marks): B
- Q10 (MCQ, 2 marks): A
- Q11 (MCQ, 2 marks): C
- Q12 (MCQ, 2 marks): A
- Q13 (MCQ, 2 marks): A
- Q14 (MSQ, 2 marks): A, C, D
- Q15 (MSQ, 2 marks): B, C, D
- Q16 (MSQ, 2 marks): A, C, D
- Q17 (MSQ, 3 marks): A, B
- Q18 (SA, 3 marks): 0.012 to 0.022
- Q19 (SA, 3 marks): 60
- Q20 (SA, 3 marks): 7
- Q21 (SA, 2 marks): 3.5
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
1. Machine Learning Basics
- Supervised vs. Unsupervised Learning
- Classification vs. Regression
2. Data Preprocessing
Standardization and Normalization
StandardScaler,MinMaxScaler
Handling Missing Values
KNNImputer
3. Model Evaluation
Metrics
- Precision Score:
- Mean Squared Error (MSE):
- R² Score:
Cross-Validation
GridSearchCV
4. Linear Models
Linear Regression
- Polynomial Regression:
Ridge Regression (L2 Regularization)
- Loss Function:
Lasso Regression (L1 Regularization)
- Loss Function:
Elastic Net
- Loss Function:
5. Support Vector Machines (SVM)
Kernel Trick
- Linear Kernel:
- Polynomial Kernel:
- RBF Kernel:
- Sigmoid Kernel:
- Regularization Parameter : Controls the trade-off between achieving a low training error and a low testing error.
6. Stochastic Gradient Descent (SGD)
Loss Functions
- Squared Error:
- Hinge Loss:
Regularization
- L1 Regularization:
- L2 Regularization:
- Elastic Net: Combination of L1 and L2 regularization.
7. Naive Bayes
Gaussian Naive Bayes: Assumes features follow a normal distribution.
- Probability Density Function:
8. K-Nearest Neighbors (KNN)
Distance Metrics
- Euclidean Distance:
- Manhattan Distance:
- Imputation: Using KNN to fill missing values.
9. Text Processing
CountVectorizer: Converts a collection of text documents to a matrix of token counts.
- N-grams: Contiguous sequence of n items from a sample of text.
10. Model Selection and Hyperparameter Tuning
- GridSearchCV: Exhaustive search over specified parameter values for an estimator.
- Pipeline: Sequentially applies a list of transforms and a final estimator.