Home / Past papers / MLP End Term / this paper
IIT M IMPROVEMENT FN EXAM QDD2 01 Sep - 01 Sep 2024
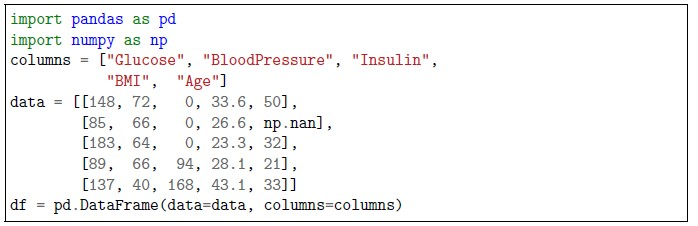 Consider following common data and answer the subquestions:
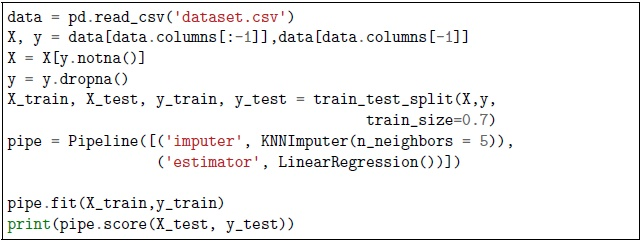
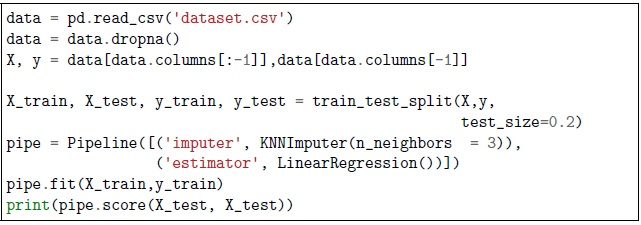
 What will be the output of the following code snippet? Enter -1, if you think the above code snippet will generate an error.
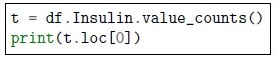 What will be the output of the following code snippet? Enter -1, if you think the above code snippet will generate an error.
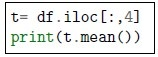 What will be the output of the following code snippet? Enter -1, if you think the above code snippet will generate an error.
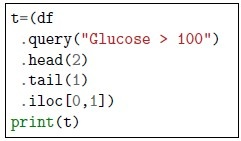 What will be the output of the following code snippet? Enter -1, if you think the above code snippet will generate an error.
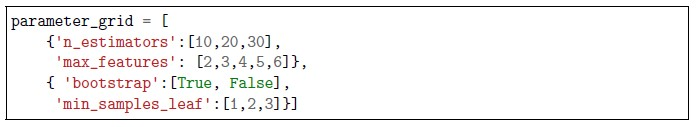 Consider following parameter grid for regression with RandomForest: How many unique combinations of hyperparameters are there in the above parameter grid?


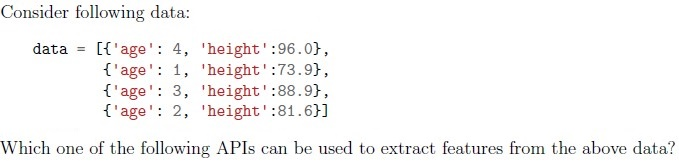
- DictVectorizer
- HashingVectorizer
- FeatureHasher
- Blood type (A, B, AB, O)
- Satisfaction rating (Very Unsatisfied, Unsatisfied, Neutral, Satisfied, VerySatisfied)
- Height of individuals
- Gender
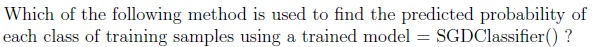
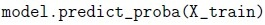
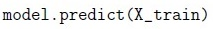
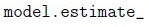
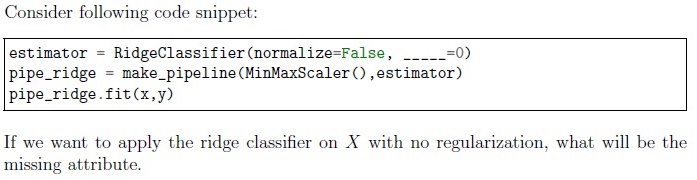
- cv
- reg_rate
- alpha
- tol
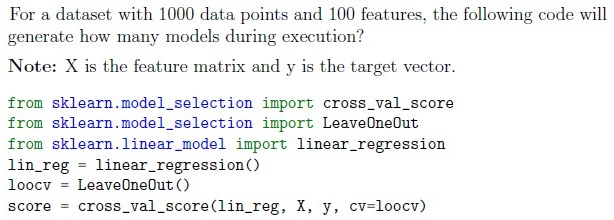
- 1000
- 100
- 99
- 999
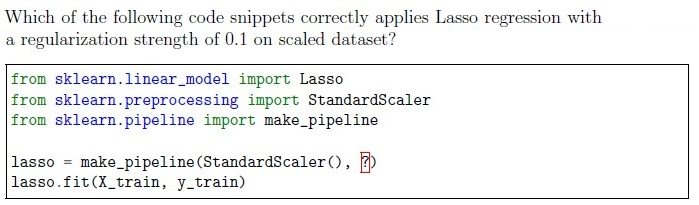
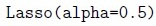
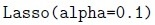
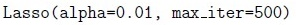
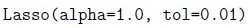
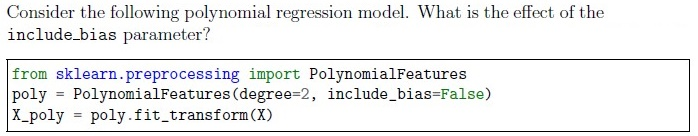
- It determines whether to include a bias term in the model.
- It sets the degree of the polynomial features.
- It controls the regularization strength.
- It specifies the number of features to consider when fitting the model.
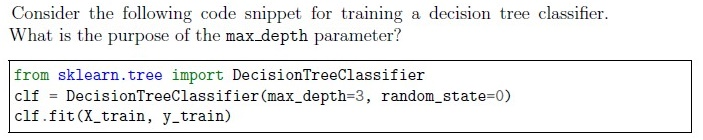
- To specify the maximum number of samples per leaf.
- To limit the depth of the tree.
- To set the minimum number of samples required to split an internal node.
- To control the minimum impurity decrease required for a split.
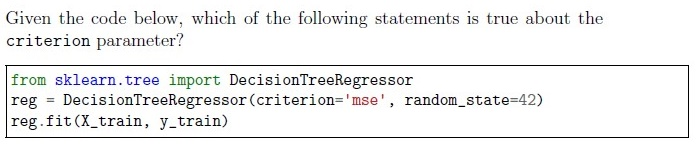
- It determines the function to measure the quality of a split.
- It specifies the number of features to consider when looking for the best split.
- It sets the strategy used to choose the split at each node.
- It controls whether to use the Gini impurity or entropy.
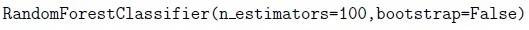
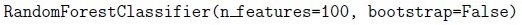
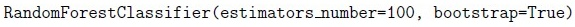
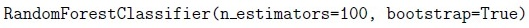
- Statement1 is True, Statement2 is True
- Statement1 is True, Statement2 is False
- Statement1 is False, Statement2 is True
- Statement1 is False, Statement2 is False
- It ignores outliers during the clustering process.
- It assigns outliers to the nearest cluster.
- It creates separate clusters for outliers.
- It removes outliers from the dataset before clustering.
- A hierarchical clustering technique that starts with each data point as itscluster and merges the closest clusters iteratively.
- A method for partitioning data into a predefined number of clusters.
- A clustering algorithm that uses centroids to iteratively assign data points toclusters.
- A dimensionality reduction technique that projects data onto a lower-dimensional space.
- The distance between cluster centroids
- The number of clusters formed
- The within-cluster sum of squared distances
- The silhouette coefficient
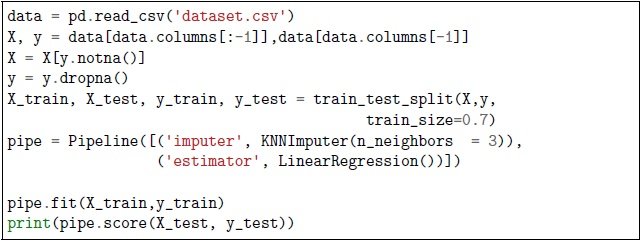
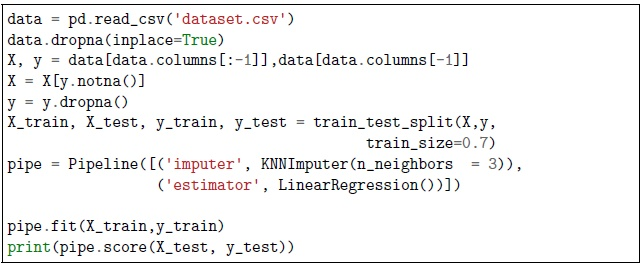
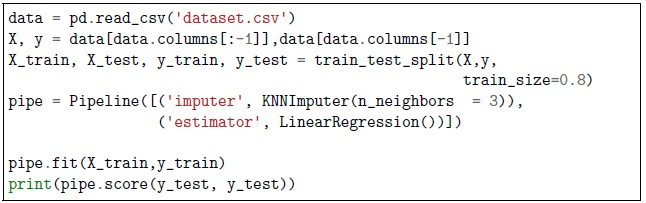
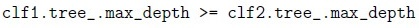
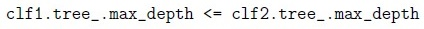
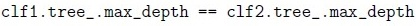
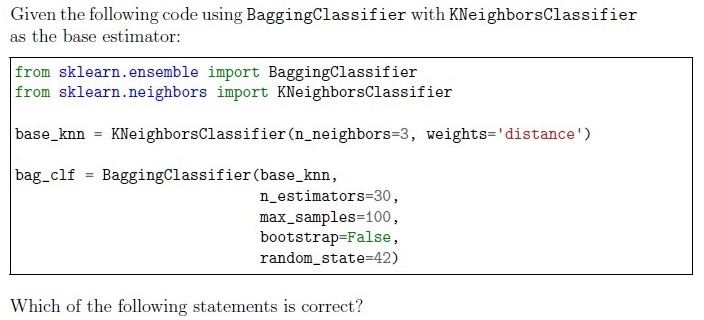
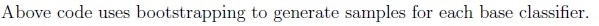
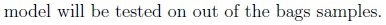
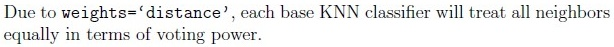
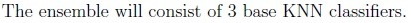
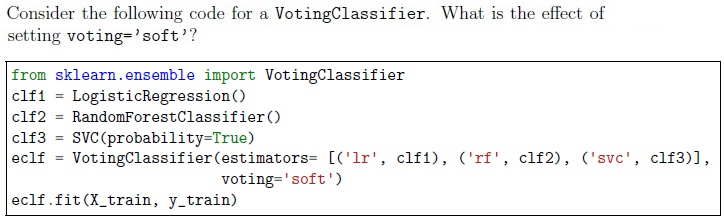
- The predictions are based on the majority vote.
- The predictions are based on the average of probabilities predicted by eachclassifier.
- The predictions are based on the weighted sum of the predictions.
- The predictions are based on the classifier with the highest accuracy
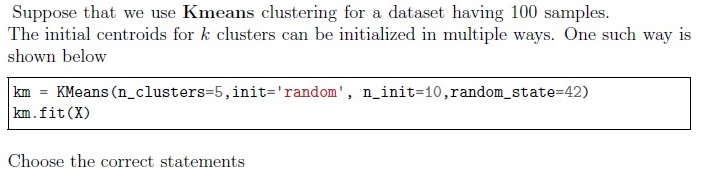
- 5 centroids are randomly initialized 10 times
- 10 centroids are randomly initialized 5 times
- 5 samples in the dataset are selected as initialization point such that they areat least 10 units away from each other
- 10 samples in the dataset are selected as initialization point such that they areat least 5 units away from each other
- Leads to biased estimation on test sets
- Increases the risk of false positives
- Leads to better estimation on training sets
- Reduces the risk of false positives
- LinearRegression
- DecisionTree
- SVM
- NaiveBayes
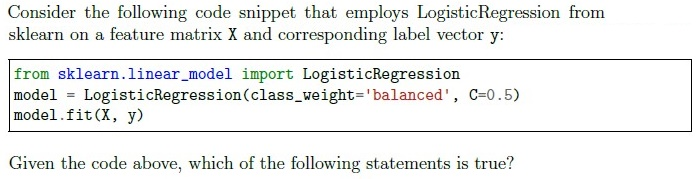
- The logistic regression model will use equal weights for both the classes in animbalanced dataset.
- The model does not use any regularization because the parameter C is set.
- The “balanced” mode uses the values of y to automatically adjust weightsinversely proportional to class frequencies in the input data.
- The value of C indicates that the model will apply a regularization.
- KNeighborsClassifier with high values of n_neighbors produces complexdecision boundaries.
- KNeighborsClassifier with high values of n_neighbors produces smoothdecision boundaries.
- In KNeighborsClassifier the scale of the features(columns) can impact thedecision boundaries.
- None of these
- Support vectors are the data points nearest to the hyperplane
- Using these support vectors, we maximize the margin of the classifier.
- Using these support vectors, we minimize the margin of the classifier.
- None of these
- It only finds spherical clusters.
- The output of the algorithms depends upon initial cluster centroids.
- It can automatically detect most appropriate value of k.
- None of these.
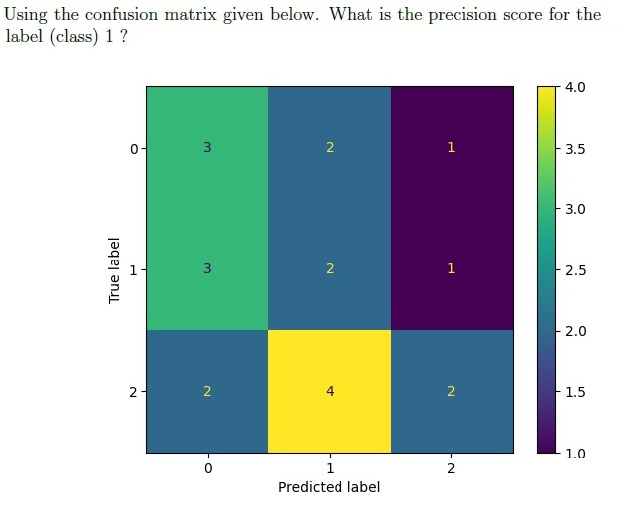
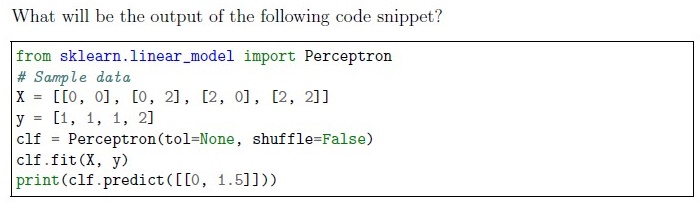
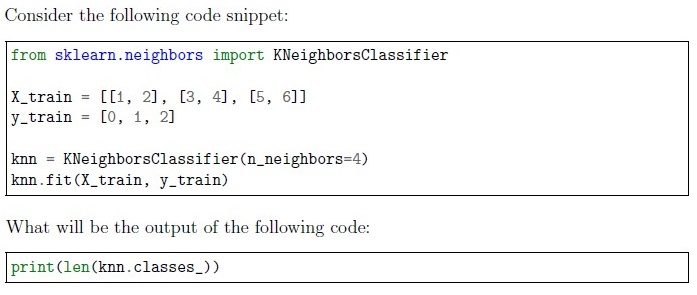
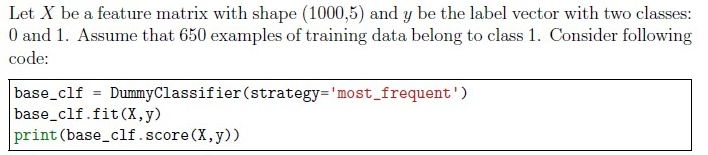
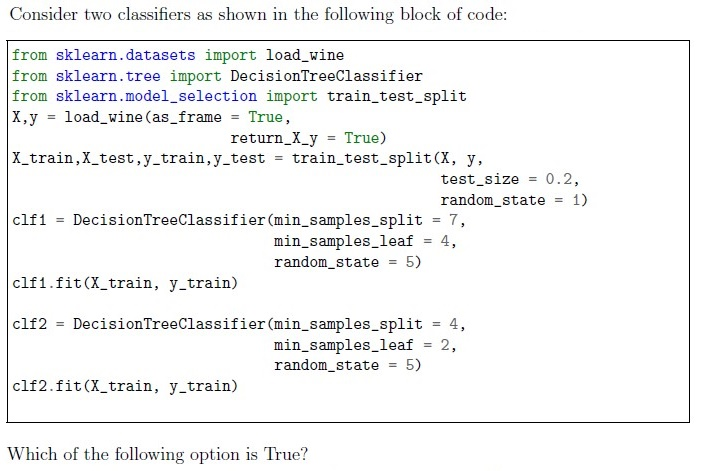
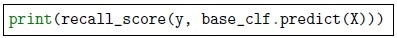 What will be the output of the following code?
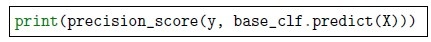 What will be the output of the following code?
Answer key
- Q1 (SA, 2 marks): 24
- Q2 (SA, 2 marks): 3
- Q3 (SA, 2 marks): 34
- Q4 (SA, 2 marks): 2
- Q5 (SA, 2 marks): 64
- Q6 (SA, 2 marks): 21
- Q7 (MCQ, 1 marks): C
- Q8 (MCQ, 2 marks): A
- Q9 (MCQ, 2 marks): B
- Q10 (MCQ, 2 marks): A
- Q11 (MCQ, 2 marks): C
- Q12 (MCQ, 3 marks): A
- Q13 (MCQ, 3 marks): B
- Q14 (MCQ, 3 marks): A
- Q15 (MCQ, 3 marks): B
- Q16 (MCQ, 3 marks): A
- Q17 (MCQ, 3 marks): D
- Q18 (MCQ, 3 marks): B
- Q19 (MCQ, 3 marks): B
- Q20 (MCQ, 3 marks): A
- Q21 (MCQ, 3 marks): C
- Q22 (MCQ, 4 marks): A
- Q23 (MCQ, 4 marks): B
- Q24 (MCQ, 4 marks): E
- Q25 (MCQ, 4 marks): B
- Q26 (MCQ, 4 marks): A
- Q27 (MSQ, 2 marks): A, B
- Q28 (MSQ, 2 marks): A, C
- Q29 (MSQ, 3 marks): C, D
- Q30 (MSQ, 3 marks): B, C
- Q31 (MSQ, 3 marks): A, B
- Q32 (MSQ, 3 marks): A, B
- Q33 (SA, 3 marks): 0.25
- Q34 (SA, 3 marks): 1
- Q35 (SA, 3 marks): 3
- Q36 (SA, 2 marks): 1
- Q37 (SA, 2 marks): 0.64 to 0.66
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the Diploma Level: Machine Learning Practice (Computer-Based Exam). The exam covers Pandas, Scikit-Learn, ML algorithms, preprocessing, model evaluation, and clustering. ---
1. Core Topics & Concepts
A. Pandas & Data Handling
Key Concepts:
DataFrame Operations:
- Shape:
df.shape→(rows, columns). - Missing values:
df.isna().sum().sum()→ Total missing values. - Value counts:
df.column.value_counts()→ Frequency of unique values. - Querying:
df.query("condition")→ Filter rows. - Indexing:
df.iloc[:, n]→ Select columnn;df.loc[index, column]→ Select by label. - Mean/aggregations:
df.column.mean()(ignoresNaNby default).
- Shape:
Handling Missing Data:
- Drop:
df.dropna(). - Impute:
KNNImputer(n_neighbors=k)(for numerical data).
- Drop:
Data Types:
float64(default for decimals),int64,object(strings/categorical).- Check dtypes:
df.dtypes.
Key Equations (Pandas):
- Mean (ignoring
NaN):
- Value Counts: Frequency of each unique value in a column.
B. Scikit-Learn Workflow
Key Concepts:
Data Preprocessing:
Scaling:
StandardScaler(standardizes to mean=0, std=1).MinMaxScaler(scales to[0, 1]).
Polynomial Features:
PolynomialFeatures(degree=d, include_bias=True/False).- If
include_bias=True, adds a column of1s (for intercept).
Encoding:
DictVectorizer(for feature extraction from dictionaries).OneHotEncoder(for categorical variables).
Train-Test Split:
train_test_split(X, y, test_size=0.3, random_state=42).random_stateensures reproducibility.
Pipelines:
make_pipeline(step1, step2, ...)→ Sequential processing (e.g., impute → scale → model).Example:
pipe = Pipeline([
    ('imputer', KNNImputer(n_neighbors=3)),
    ('scaler', StandardScaler()),
    ('model', LinearRegression())
])
Model Evaluation:
- Regression:
R² score(model.score(X_test, y_test)). Classification:
precision_score,recall_score,confusion_matrix.DummyClassifier(strategy='most_frequent')→ Predicts the majority class.
- Regression:
Key Equations (Preprocessing):
- Standard Scaling:
where = mean, = standard deviation.
- Min-Max Scaling:
- Polynomial Features: For
degree=2and features , output includes (ifinclude_bias=True).
C. Supervised Learning Algorithms
1. Linear Models
| Model | Key Parameters | Use Case | Equation |
|---|---|---|---|
| LinearRegression | - | Regression | (closed-form solution via OLS) |
| RidgeRegression | alpha (regularization strength) | Regression (L2 penalty) | |
| LassoRegression | alpha | Regression (L1 penalty, sparsity) | |
| SGDRegressor | max_iter, tol, learning_rate | Large datasets | Iterative update: |
| LogisticRegression | C (inverse of alpha), class_weight | Binary classification | , where = sigmoid function. |
| Perceptron | tol, shuffle | Linear classification |
Key Notes:
Regularization:
alpha=0→ No regularization (e.g.,RidgeClassifier(alpha=0)).- Higher
alpha→ Stronger penalty.
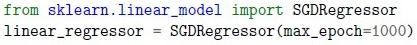
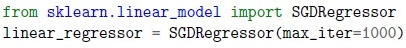
- SGD Stopping: Use
max_iter(notmax_epoch). Logistic Regression:
class_weight='balanced'adjusts weights inversely to class frequencies.Ccontrols regularization (smallerC→ stronger regularization).
2. Tree-Based Models
| Model | Key Parameters | Use Case | Key Concepts |
|---|---|---|---|
| DecisionTree | max_depth, min_samples_split, criterion (gini/entropy for classification, mse/mae for regression) | Classification/Regression | Splits data recursively; max_depth limits tree depth to prevent overfitting. |
| RandomForest | n_estimators, bootstrap, max_features | Ensemble learning | Bagging (bootstrap aggregating) of decision trees. |
| BaggingClassifier | base_estimator, n_estimators, max_samples | Reduce variance | Trains base models on bootstrapped samples. |
| VotingClassifier | estimators, voting (hard/soft) | Ensemble learning | soft voting averages predicted probabilities. |
Key Notes:
Decision Trees:
min_samples_split=2(default): Minimum samples to split a node.min_samples_leaf=1(default): Minimum samples in a leaf.- Deeper trees → Higher variance (overfitting).
Random Forest:
bootstrap=True(default): Samples with replacement.max_features='sqrt'(default for classification): Features considered for splits.
Bagging vs. Boosting:
- Bagging: Parallel training (e.g., Random Forest).
- Boosting: Sequential training (focuses on errors, e.g., AdaBoost).
3. Nearest Neighbors
| Model | Key Parameters | Use Case | Key Concepts |
|---|---|---|---|
| KNeighborsClassifier | n_neighbors, weights (uniform/distance) | Classification | Predicts majority class of k nearest neighbors. |
| KNeighborsRegressor | n_neighbors, weights | Regression | Predicts average of k nearest neighbors. |
Key Notes:
- Distance Metrics: Default is Euclidean.
- Scaling: Critical (use
StandardScaler). n_neighbors:- Small
k→ Complex boundaries (overfitting). - Large
k→ Smooth boundaries (underfitting).
- Small
4. Support Vector Machines (SVM)
| Model | Key Parameters | Use Case | Key Concepts |
|---|---|---|---|
| SVC | C, kernel (linear, rbf), gamma | Classification | Maximizes margin; C controls misclassification penalty. |
| SVR | C, kernel, epsilon | Regression | Fits a tube around data; epsilon defines tube width. |
Key Notes:
- Support Vectors: Data points closest to the hyperplane.
- Kernel Trick: Transforms data into higher dimensions (e.g.,
rbffor non-linear boundaries). - Scaling: Required (use
StandardScaler).
D. Unsupervised Learning
1. Clustering
| Model | Key Parameters | Use Case | Key Concepts |
|---|---|---|---|
| KMeans | n_clusters, init (random/k-means++), n_init | General-purpose clustering | Minimizes within-cluster sum of squares (inertia). |
| AgglomerativeClustering | n_clusters, linkage (ward, complete, average) | Hierarchical clustering | Merges closest clusters iteratively. |
Key Notes:
K-Means:
inertia: Sum of squared distances to centroids (lower = better).n_init: Number of times to run with different centroid seeds.- Limitations: Assumes spherical clusters; sensitive to initialization.
Agglomerative Clustering:
Linkage Methods:
ward: Minimizes variance.complete: Maximizes distance between clusters.
- Outliers: Assigned to the nearest cluster (not ignored).
Key Equations (Clustering):
- Inertia (K-Means):
where = set of centroids.
E. Model Evaluation & Metrics
1. Classification Metrics
| Metric | Formula | Interpretation |
|---|---|---|
| Accuracy | Overall correctness. | |
| Precision | Correctness of positive predictions. | |
| Recall (Sensitivity) | Ability to find all positive instances. | |
| F1-Score | Harmonic mean of precision and recall. | |
| Confusion Matrix | TP, TN, FP, FN for each class. |
2. Regression Metrics
| Metric | Formula | Interpretation |
|---|---|---|
| R² Score | Proportion of variance explained (1 = perfect fit). | |
| MSE | Average squared error. |
3. Cross-Validation
| Method | Description | Use Case |
|---|---|---|
| Leave-One-Out (LOOCV) | Uses samples for training, 1 for testing (repeated times). | Small datasets. |
| k-Fold CV | Splits data into folds; each fold used once for testing. | General-purpose. |
Key Notes:
- Dummy Classifier: Baseline model (e.g.,
strategy='most_frequent'). - Class Imbalance: Use
class_weight='balanced'or resampling. - Overfitting: High training accuracy but low test accuracy.
F. Hyperparameter Tuning
Key Concepts:
Grid Search:
ParameterGridgenerates all combinations of hyperparameters.Example:
param_grid = { 'n_estimators': [10, 20, 30], 'max_features': [2, 3, 4] }- Total combinations: .
- Random Search: Samples randomly from parameter distributions.
Common Parameters:
- Random Forest:
n_estimators,max_depth,min_samples_leaf. - SVM:
C,kernel,gamma. - KNN:
n_neighbors,weights.
- Random Forest:
G. Special Topics
1. Data Snooping
- Definition: Repeatedly testing hypotheses on the same dataset leads to overfitting.
Effects:
- Biased test set estimates.
- Increased false positives (Type I errors).
2. Feature Scaling Impact
Affected Algorithms:
- Distance-based: KNN, SVM, K-Means.
- Gradient-based: Linear Regression, Logistic Regression, Neural Networks.
Unaffected Algorithms:
- Tree-based: Decision Trees, Random Forest.
3. Ordinal vs. Nominal Variables
| Type | Definition | Example |
|---|---|---|
| Ordinal | Categories with order. | Satisfaction (Low, Medium, High). |
| Nominal | Categories without order. | Blood type (A, B, AB, O). |
Graph 2: Unsupervised Learning
Graph 3: Model Evaluation
Graph 4: Scikit-Learn Ecosystem
Graph 5: Tree-Based Models
Graph 6: Clustering Algorithms
3. Key Equations Summary
| Topic | Equation | Description |
|---|---|---|
| Linear Regression | Predicted value. | |
| Ridge Regression | L2 regularization. | |
| Lasso Regression | L1 regularization (sparsity). | |
| Logistic Regression | Sigmoid function for probabilities. | |
| Perceptron | Linear classifier. | |
| K-Means Inertia | Within-cluster sum of squares. | |
| Precision | Correct positive predictions. | |
| Recall | True positives found. | |
| R² Score | Variance explained. | |
| Standard Scaling | Normalizes features. | |
| Min-Max Scaling | Scales to [0, 1]. | |
| Polynomial Features | For , degree=2: | Generates interaction terms. |
4. Exam Tips
Pandas:
- Memorize
df.shape,df.isna().sum(),df.value_counts(). - Practice indexing (
iloc,loc) and querying (df.query).
- Memorize
Scikit-Learn:
- Know default parameters (e.g.,
RandomForestClassifier(n_estimators=100)). - Understand
fit,predict,scoremethods. - Recall preprocessing steps (scaling, imputation, encoding).
- Know default parameters (e.g.,
Algorithms:
- Linear Models: Focus on regularization (
alpha,C). - Tree-Based: Know
max_depth,min_samples_split,bootstrap. - KNN: Remember scaling and
n_neighbors. - SVM: Kernel trick and
Cparameter.
- Linear Models: Focus on regularization (
Evaluation:
- Classification: Precision, recall, F1, confusion matrix.
- Regression: R², MSE.
- Cross-validation: LOOCV vs. k-fold.
Clustering:
- K-Means: Inertia,
n_init, scaling. - Agglomerative: Linkage methods (
ward,complete).
- K-Means: Inertia,
Hyperparameter Tuning:
- Calculate total combinations for
ParameterGrid. - Example:
{'a': [1,2], 'b': [3,4]}→ 4 combinations.
- Calculate total combinations for
Special Cases:
DummyClassifier: Predicts majority class.DictVectorizer: For dictionary-to-feature matrix.PolynomialFeatures:include_biasadds intercept term.
Common Pitfalls:
- Forgetting to scale data for KNN/SVM.
- Misinterpreting
class_weight='balanced'. - Confusing
max_iter(SGD) withn_estimators(Random Forest).