Home / Past papers / MLF Quiz 1 / this paper
IIT M DIPLOMA AN EXAM QDD4 26 Oct 2025 - 26 Oct 2025
- Regression
- Classification
- Clustering
- Dimensionality Reduction
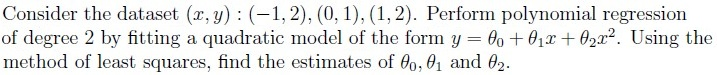



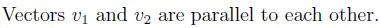
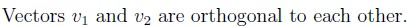
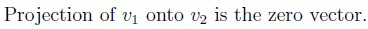
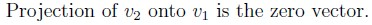
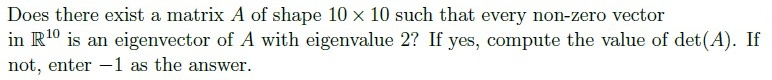
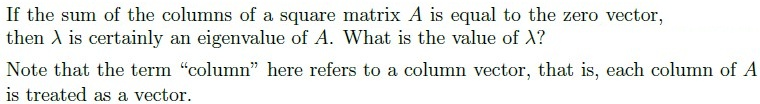
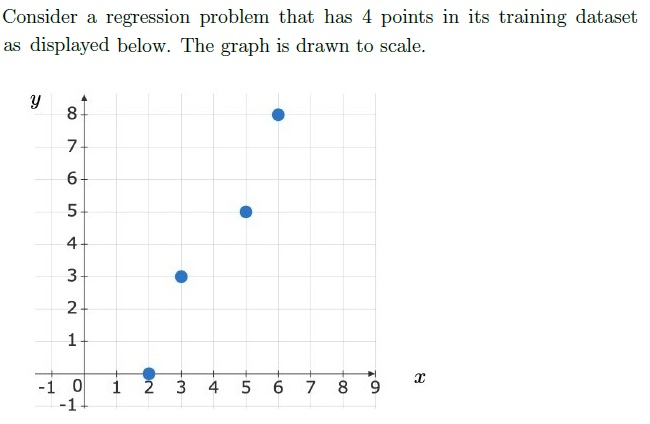
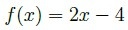


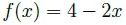
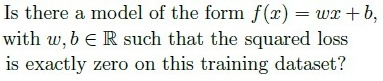
- No
- Yes
- Insufficient information to answer the question
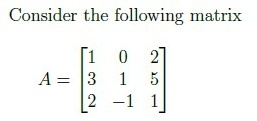
- {(1, 0, 2), (0, 1,−1)}
- {(1, 0, 2), (0, 1,−1), (0, 0,−1)}
- {(1, 0, 2), (0,−1, 1), (0,−1,−4)}
- {(0, 1,−1), (0, 0,−4)}
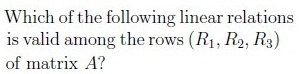
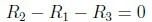
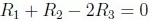
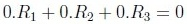
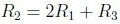
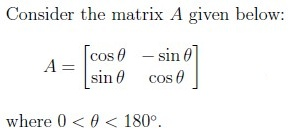
- A is an orthogonal matrix
- A is invertible
- A is symmetric
- A does not have real eigenvalues
- A has two distinct real eigenvalues
- A has two real eigenvalues, not necessarily distinct
- True
- False
- True
- False
- True
- False
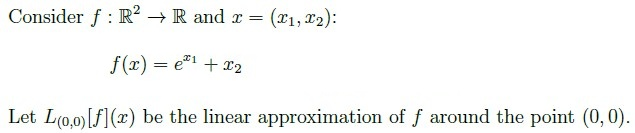


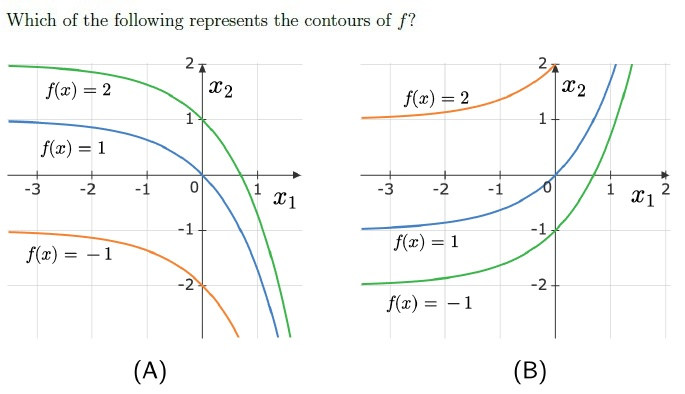
- (A)
- (B)
Answer key
- Q1 (MCQ, 1 marks): B
- Q2 (MCQ, 3 marks): A
- Q3 (MSQ, 2 marks): B, C, D
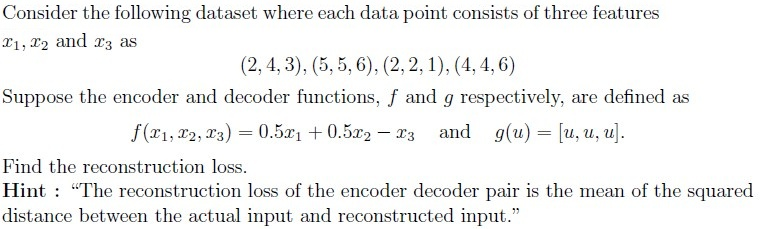
- Q4 (SA, 3 marks): 72
- Q5 (SA, 3 marks): 1024
- Q6 (SA, 2 marks): 0
- Q7 (MCQ, 3 marks): A
- Q8 (MCQ, 2 marks): A
- Q9 (MCQ, 3 marks): B
- Q10 (MCQ, 2 marks): C
- Q11 (MSQ, 2 marks): A, B
- Q12 (MCQ, 3 marks): A
- Q13 (MCQ, 2 marks): B
- Q14 (MCQ, 1 marks): A
- Q15 (MCQ, 2 marks): B
- Q16 (MCQ, 2 marks): A
- Q17 (SA, 2 marks): 1
- Q18 (MCQ, 2 marks): A
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations for the "Diploma Level: Machine Learning Foundations" exam, along with Mermaid knowledge graphs to visualize relationships.
1. Core Topics & Concepts
A. Machine Learning Fundamentals
1. Supervised Learning
Classification (Binary/Multi-class):
- Used for discrete outputs (e.g., loan approval: Yes/No).
- Algorithms: Logistic Regression, Decision Trees, SVM, k-NN.
Loss Functions:
- 0-1 Loss (misclassification error).
- Log Loss (Cross-Entropy) for probabilistic outputs.
- Hinge Loss (SVM).
Evaluation Metrics:
- Accuracy, Precision, Recall, F1-Score, ROC-AUC.
Regression:
- Used for continuous outputs (e.g., predicting house prices).
- Algorithms: Linear Regression, Ridge/Lasso, Polynomial Regression.
Loss Functions:
- Mean Squared Error (MSE):
- Mean Absolute Error (MAE).
2. Unsupervised Learning
- Clustering (e.g., k-Means, Hierarchical Clustering).
- Dimensionality Reduction (e.g., PCA, t-SNE).
3. Model Evaluation
- Train-Test Split, Cross-Validation.
Bias-Variance Tradeoff:
- Underfitting (High bias) vs. Overfitting (High variance).
- Regularization (L1/L2) to prevent overfitting.
B. Linear Algebra (Critical for ML)
1. Matrix Operations
- Matrix Multiplication, Transpose, Inverse.
- Determinant (for invertibility):
- Rank (dimension of column/row space).
2. Vector Spaces
Basis: Linearly independent vectors spanning a space.
- Example: For , a basis could be .
- Row Space / Column Space / Null Space.
3. Eigenvalues & Eigenvectors
- For a square matrix :
- Real Symmetric Matrices: All eigenvalues are real.
Diagonalizable Matrices:
- is diagonalizable iff it has n linearly independent eigenvectors (not necessarily distinct eigenvalues).
- If has n distinct eigenvalues, it is diagonalizable.
4. Special Matrices
- Orthogonal Matrix ().
- Symmetric Matrix ().
- Positive Definite Matrices (all eigenvalues > 0).
C. Probability & Statistics (Brief)
- Bayes’ Theorem (for Naive Bayes classifier).
- Maximum Likelihood Estimation (MLE).
- Gaussian (Normal) Distribution.
D. Optimization (For ML Models)
- Gradient Descent (for minimizing loss functions):
where = learning rate, = loss function.
2. Key Equations (Math-Focused)
| Concept | Equation |
|---|---|
| MSE Loss | |
| Log Loss (Binary) | |
| Linear Regression | |
| Logistic Regression | , |
| Eigenvalue Equation | |
| Matrix Inverse | |
| Determinant (2x2) | |
| Gradient Descent Update |
Graph 2: Linear Algebra Concepts
Graph 3: Model Evaluation & Optimization
4. Exam-Specific Insights
- Question 2 (Loan Approval) → Classification (Binary).
Questions 10, 12, 13, 15, 16 → Linear Algebra (Basis, Eigenvalues, Symmetric/Orthogonal Matrices).
- A matrix is orthogonal if .
- A matrix is diagonalizable if it has n linearly independent eigenvectors (not necessarily distinct eigenvalues).
- Questions 5, 6, 7, 18 → Likely basic matrix computations (determinants, traces, or simple arithmetic).
- Question 8, 9 → Regression Loss Comparison (MSE for linear regression).
- Question 14 → Diagonalizable ≠ Invertible (a matrix can be diagonalizable but singular if it has a zero eigenvalue).
5. Study Recommendations
| Topic | Focus Areas |
|---|---|
| Supervised Learning | Classification vs. Regression, Loss Functions, Evaluation Metrics. |
| Linear Algebra | Matrix Inverses, Rank, Basis, Eigenvalues/Eigenvectors, Diagonalization. |
| Optimization | Gradient Descent, Regularization (L1/L2). |
| Probability | Bayes’ Theorem, MLE (if included in syllabus). |
Final Tip: For math-heavy questions, practice matrix computations (determinants, eigenvalues, basis) and loss function derivations. For ML, understand when to use classification vs. regression.