Home / Past papers / MLF End Term / this paper
2023 Dec24: IIT M FN EXAM FDD2 - 24 Dec 2023
Elapsed 00:00
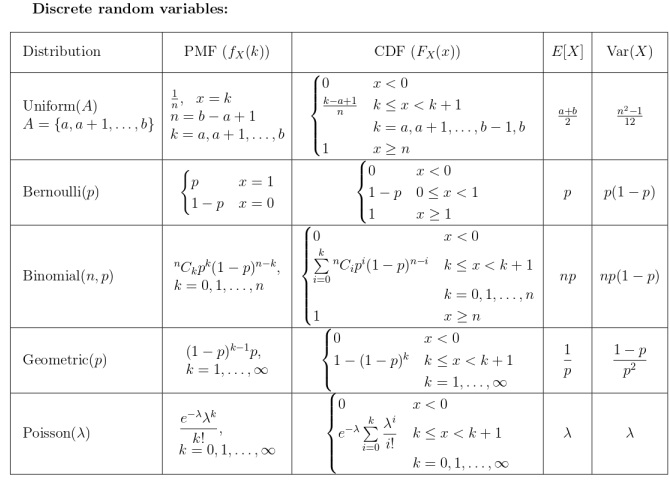
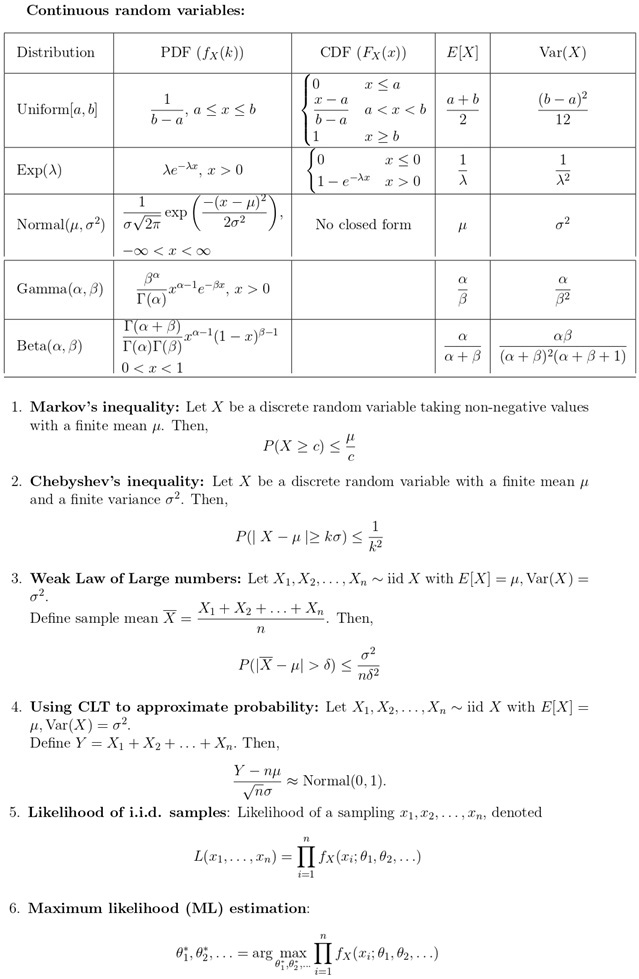
- Useful Data has been mentioned above.
- This data attachment is just for a reference & not for an evaluation.
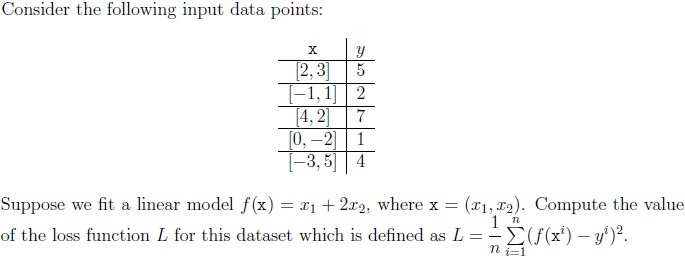
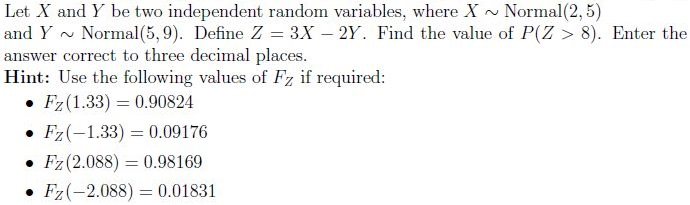
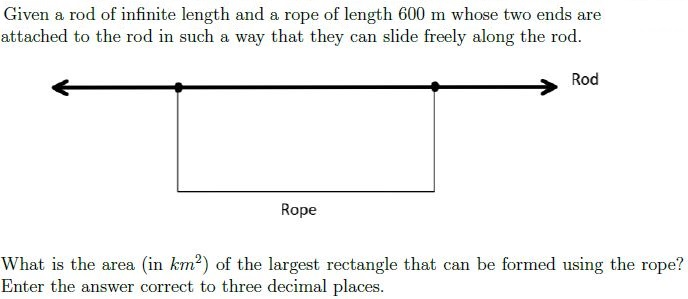
Which of the following functions is/are continuous?
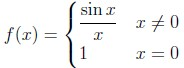
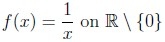
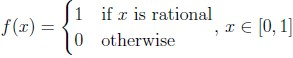
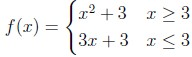
Let A be a n × n positive definite matrix. Then, which among the following are correct?
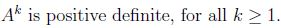
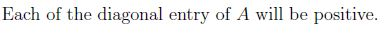
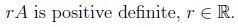
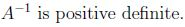
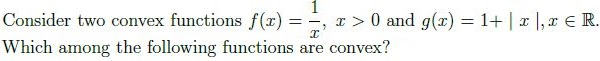


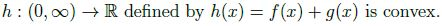
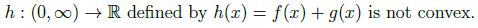
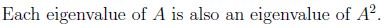
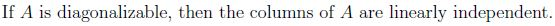
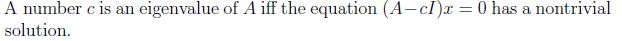
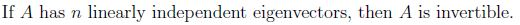
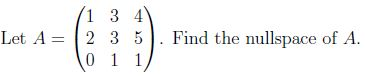
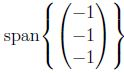
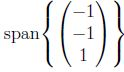

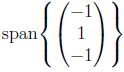
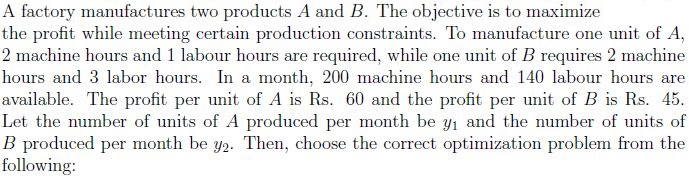
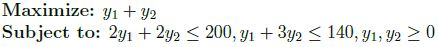
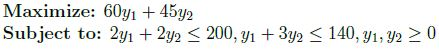
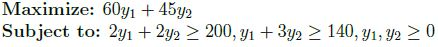
Comprehension passage - the questions below it refer to this
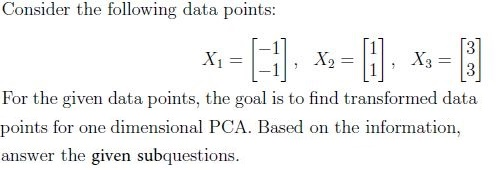
Which of the following represents the covariance matrix, C for the given data points?


What is the value of the projected variance? Enter the answer correct to two decimal places.
Answer key
- Q1 (MCQ, 0 marks): A
- Q2 (SA, 3 marks): 9
- Q3 (SA, 3 marks): 0.089 to 0.095
- Q4 (SA, 3 marks): 0.74 to 0.79
- Q5 (SA, 3 marks): 0.24 to 0.28
- Q6 (SA, 3 marks): 0.020 to 0.030
- Q7 (MSQ, 3 marks): A, B, D
- Q8 (MSQ, 3 marks): A, B, D
- Q9 (SA, 4 marks): 0.370 to 0.380
- Q10 (MSQ, 3 marks): B, C
- Q11 (MCQ, 2 marks): C
- Q12 (MCQ, 2 marks): B
- Q13 (MCQ, 2 marks): B
- Q14 (MCQ, 2 marks): C
- Q15 (SA, 2 marks): 5.30 to 5.37
- Q16 (SA, 2 marks): 10
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Concepts
1. Probability & Random Variables
Discrete Distributions
| Distribution | PMF () | CDF () | ||
|---|---|---|---|---|
| Uniform() | ||||
| Bernoulli() | (for ) | |||
| Binomial() | Cumulative sum of PMF | |||
| Geometric() | ||||
| Poisson() | Cumulative sum of PMF |
Continuous Distributions
| Distribution | PDF () | CDF () | ||
|---|---|---|---|---|
| Uniform() | ||||
| Exponential() | ||||
| Normal() | No closed form | |||
| Gamma() | Incomplete Gamma | |||
| Beta() | Incomplete Beta |
Key Inequalities & Theorems
- Markov’s Inequality:
- Chebyshev’s Inequality:
- Weak Law of Large Numbers (WLLN):
- Central Limit Theorem (CLT):
where and .
- Maximum Likelihood Estimation (MLE):
For Exponential():
2. Linear Algebra
Key Concepts
Positive Definite Matrices:
- is positive definite if for all .
Properties:
- All eigenvalues .
- is positive definite for .
- is positive definite.
- Diagonal entries (but not sufficient alone).
Nullspace:
- For matrix , nullspace = .
- Example: For , nullspace is .
Eigenvalues & Diagonalizability:
- is an eigenvalue of iff has a nontrivial solution.
- If has linearly independent eigenvectors, it is diagonalizable.
Optimization (Linear Programming)
- Standard Form:
- Example:
3. Machine Learning Basics
Linear Regression
- Model: .
- Loss Function (MSE):
(Note: Question 3 uses , but standard MSE is minimized.)
Principal Component Analysis (PCA)
Steps:
- Compute covariance matrix .
- Find eigenvalues and eigenvectors of .
- Project data onto top eigenvectors.
Projected Variance:
- For 1D PCA, variance = largest eigenvalue of .
- Example: For , projected variance .
4. Convexity
Convex Functions:
- is convex if .
- Examples: (convex for ), (convex).
Composition Rules:
- If is convex and non-decreasing, and is convex, then is convex.
- Sum of convex functions is convex.