Home / Past papers / MLF Quiz 2 / this paper
IIT M DIPLOMA AN EXAM QDD3 03 Aug - 03 Aug 2025
Elapsed 00:00
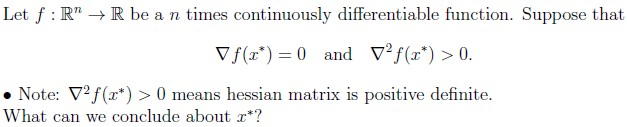
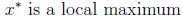
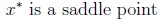
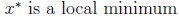
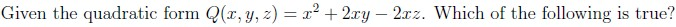
- Q is positive definite.
- Q is positive semi-definite.
- Q is negative definite.
- Q is negative semi-definite.
- None of these
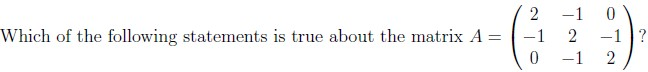
- A is positive definite.
- A is positive semi-definite.
- A is negative definite.
- A is negative semi-definite.
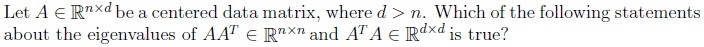
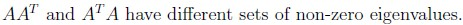
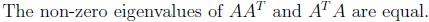
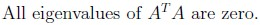
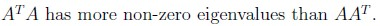
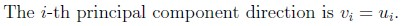
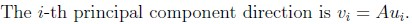
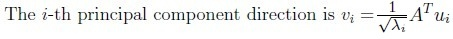
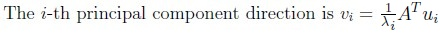
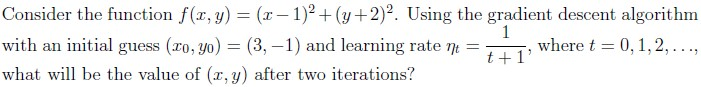
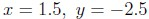
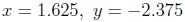
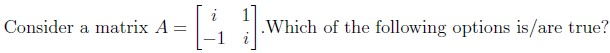
- A is a Hermitian matrix.
- A is a unitary matrix.
- All eigenvalues of A are not real.
- Eigenvectors corresponding to different eigenvalues of A are not orthogonal.
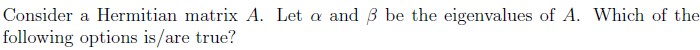
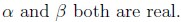
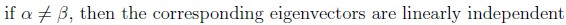
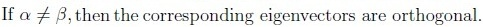
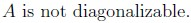
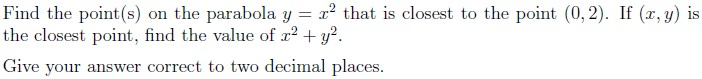
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
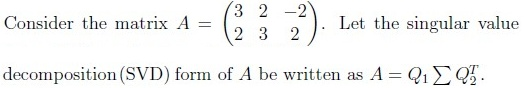
Which of the following options is/are true?
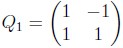
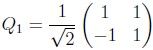
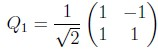
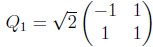
Which of the following options is/are true ?
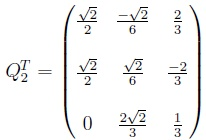
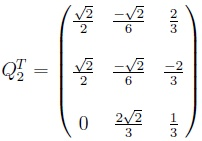
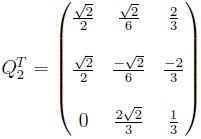
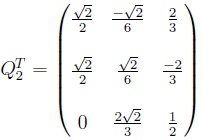
Which of the following options is true?
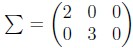
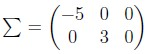
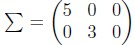
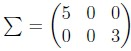
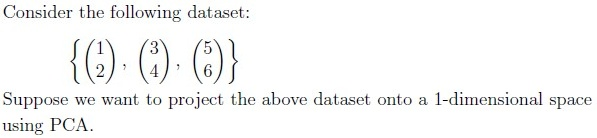
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
The sample covariance matrix C for the given dataset is
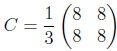
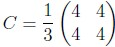
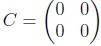
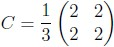
The eigenvalues of the covariance matrix are
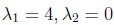
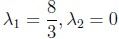
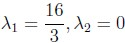
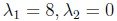
The first principal component is


Answer key
- Q1 (MCQ, 2 marks): C
- Q2 (MCQ, 2 marks): E
- Q3 (MCQ, 3 marks): A
- Q4 (MCQ, 3 marks): B
- Q5 (MCQ, 3 marks): C
- Q6 (MCQ, 3 marks): A
- Q7 (MSQ, 3 marks): C, D
- Q8 (MSQ, 3 marks): A, B, C
- Q9 (SA, 3 marks): 3.45 to 4.05
- Q10 (MCQ, 3 marks): C
- Q11 (MCQ, 3 marks): A
- Q12 (MCQ, 2 marks): C
- Q13 (MCQ, 2 marks): A
- Q14 (MCQ, 2 marks): A
- Q15 (MCQ, 3 marks): C
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Summary of Core Topics, Concepts, Principles, and Equations
1. Optimization and Critical Points
- Gradient and Hessian Matrix: For a function , the gradient and the Hessian matrix being positive definite indicate a local minimum.
- Quadratic Forms: Understanding positive definiteness, positive semi-definiteness, negative definiteness, and negative semi-definiteness of quadratic forms.
2. Matrix Properties
- Positive Definite Matrices: A matrix is positive definite if for all non-zero vectors .
- Eigenvalues and Eigenvectors: For a Hermitian matrix, eigenvalues are real, and eigenvectors corresponding to different eigenvalues are orthogonal.
- Singular Value Decomposition (SVD): For a matrix , SVD is given by , where and are orthogonal matrices, and is a diagonal matrix of singular values.
3. Principal Component Analysis (PCA)
- Covariance Matrix: The sample covariance matrix is used to find the principal components.
- Eigenvalues and Principal Components: The eigenvalues of the covariance matrix represent the variance in the direction of the corresponding eigenvectors (principal components).
4. Gradient Descent
- Gradient Descent Algorithm: Iterative method to minimize a function using the update rule , where is the learning rate.
5. Distance Minimization
- Distance Formula: The distance between two points and is given by .
Equations
- Gradient and Hessian:
- Quadratic Form:
- Positive Definite Matrix:
- Eigenvalues of and :
- Principal Component Direction:
- Gradient Descent Update:
- Distance Formula:
- Sample Covariance Matrix: