Home / Past papers / MLF End Term / this paper
IIT M IMPROVEMENT FN EXAM FDI2 24 Dec 2023 - 24 Dec 2023
Elapsed 00:00
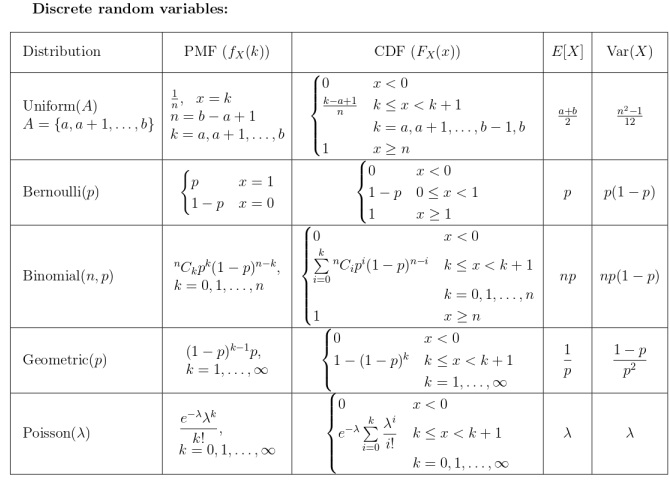
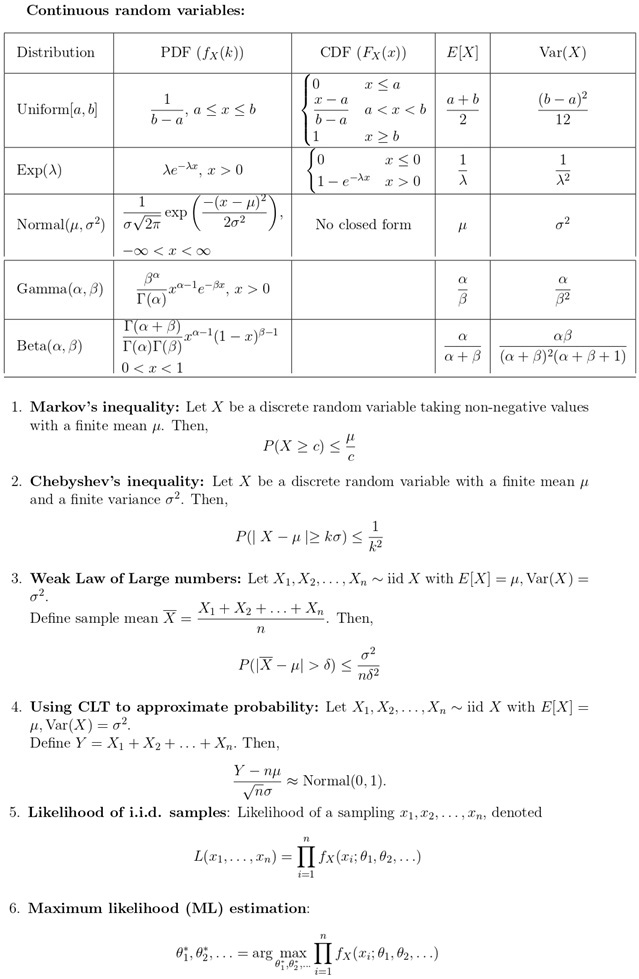
- Useful Data has been mentioned above.
- This data attachment is just for a reference & not for an evaluation.
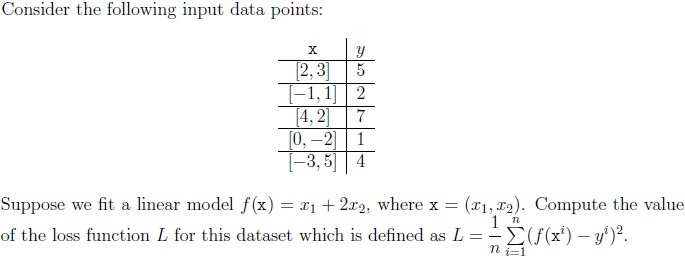
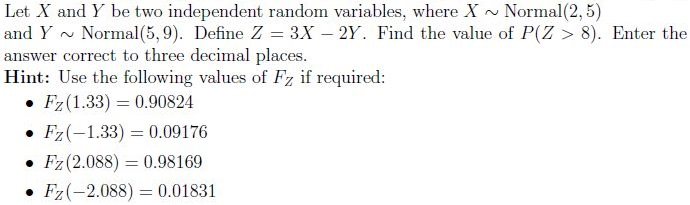
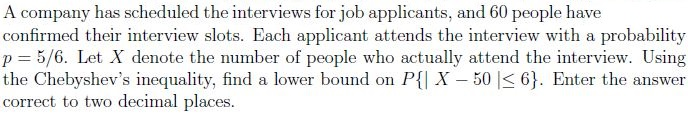
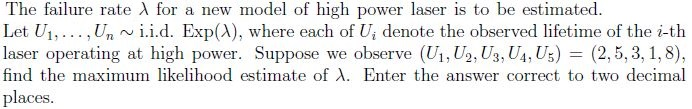
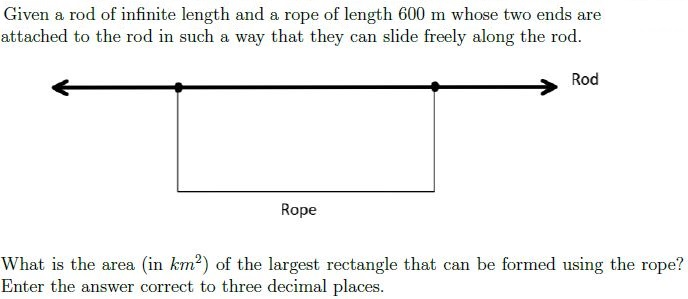
Which of the following functions is/are continuous?
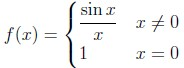
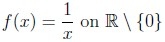
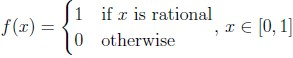
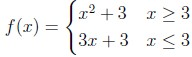
Let A be a n × n positive definite matrix. Then, which among the following are correct?
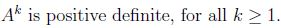
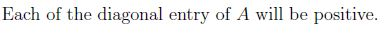
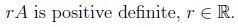
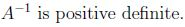
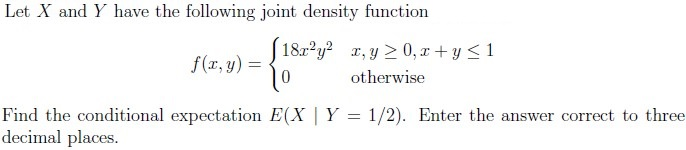
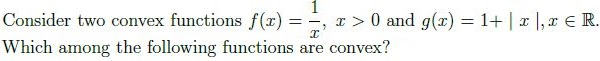


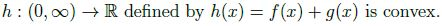
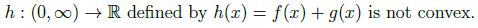
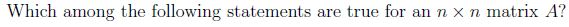
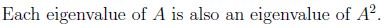
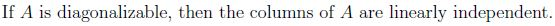
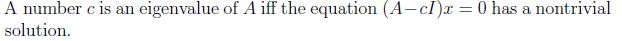
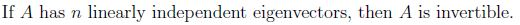
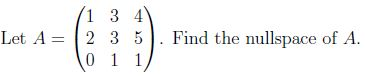
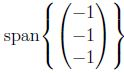
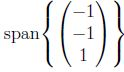

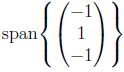
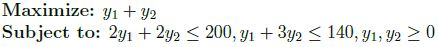
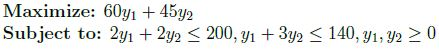
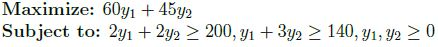
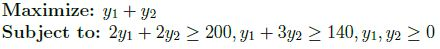
Comprehension passage - the questions below it refer to this
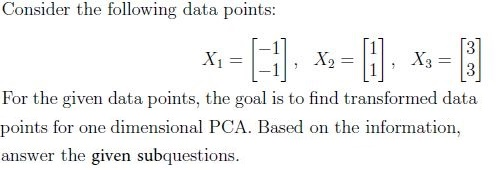
Which of the following represents the covariance matrix, C for the given data points?


What is the value of the projected variance? Enter the answer correct to two decimal places.
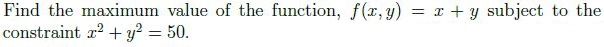
Answer key
- Q1 (MCQ, 0 marks): A
- Q2 (SA, 3 marks): 9
- Q3 (SA, 3 marks): 0.089 to 0.095
- Q4 (SA, 3 marks): 0.74 to 0.79
- Q5 (SA, 3 marks): 0.24 to 0.28
- Q6 (SA, 3 marks): 0.020 to 0.030
- Q7 (MSQ, 3 marks): A, B, D
- Q8 (MSQ, 3 marks): A, B, D
- Q9 (SA, 4 marks): 0.370 to 0.380
- Q10 (MSQ, 3 marks): B, C
- Q11 (MCQ, 2 marks): C
- Q12 (MCQ, 2 marks): B
- Q13 (MCQ, 2 marks): B
- Q14 (MCQ, 2 marks): C
- Q15 (SA, 2 marks): 5.30 to 5.37
- Q16 (SA, 2 marks): 10
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Concepts
1. Probability & Statistics
A. Random Variables & Distributions
Discrete Distributions:
- Uniform (Discrete): PMF, CDF, Mean, Variance.
- Bernoulli: PMF, CDF, Mean (
p), Variance (p(1-p)). - Binomial: PMF (
nCk p^k (1-p)^(n-k)), Mean (np), Variance (np(1-p)). - Geometric: PMF (
(1-p)^(k-1) p), Mean (1/p), Variance((1-p)/p^2). - Poisson: PMF (
e^(-λ) λ^k / k!), Mean & Variance (λ).
Continuous Distributions:
- Uniform (Continuous): PDF (
1/(b-a)), CDF, Mean ((a+b)/2), Variance ((b-a)^2/12). - Exponential: PDF (
λ e^(-λx)), CDF (1 - e^(-λx)), Mean (1/λ), Variance (1/λ^2). - Normal: PDF (
1/(σ√(2π)) e^(-(x-μ)^2/(2σ^2))), Mean (μ), Variance (σ^2). - Gamma: PDF (
β^α x^(α-1) e^(-βx) / Γ(α)), Mean (α/β), Variance (α/β^2). - Beta: PDF (
Γ(α+β)/(Γ(α)Γ(β)) x^(α-1) (1-x)^(β-1)), Mean (α/(α+β)), Variance (αβ/((α+β)^2 (α+β+1))).
- Uniform (Continuous): PDF (
B. Inequalities & Theorems
- Markov’s Inequality:
P(X ≥ c) ≤ μ/c(for non-negativeX). - Chebyshev’s Inequality:
P(|X - μ| ≥ kσ) ≤ 1/k^2. - Weak Law of Large Numbers (WLLN):
P(|X̄ - μ| > δ) ≤ σ^2 / (n δ^2). - Central Limit Theorem (CLT):
(Y - nμ) / (σ√n) ~ N(0,1)forY = ΣX_i(i.i.d.X_i). - Maximum Likelihood Estimation (MLE):
θ* = argmax_θ Π f_X(x_i; θ).
C. Joint & Conditional Distributions
- Joint PDF/PMF:
f_X,Y(x,y). - Conditional Expectation:
E[X|Y=y] = ∫ x f_X|Y(x|y) dx. - Covariance Matrix: For data points
X_i, compute mean, covariance, and eigenvalues for PCA.
2. Linear Algebra
A. Matrices & Properties
Positive Definite Matrices:
Ais positive definite ifx^T A x > 0for allx ≠ 0.Properties:
A^kis positive definite fork ≥ 1.- Diagonal entries of
Aare positive. A^-1is positive definite.rAis positive definite forr > 0.
Eigenvalues & Eigenvectors:
cis an eigenvalue ofAiff(A - cI)x = 0has a nontrivial solution.- If
Ahasnlinearly independent eigenvectors, it is diagonalizable.
- Nullspace: Solutions to
A x = 0.
B. Optimization & Convexity
Convex Functions:
f(x) = 1/x(convex forx > 0).g(x) = 1 + |x|(convex).Composition rules:
g ∘ fis convex ifgis convex and non-decreasing, andfis convex.- Sum of convex functions is convex.
Linear Programming:
- Maximize
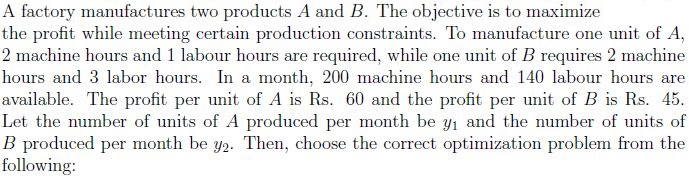
Z = 60y1 + 45y2subject to constraints (e.g., machine/labor hours).
- Maximize
3. Machine Learning & Optimization
A. Linear Regression
- Loss Function (MSE):
L = (1/n) Σ (f(x_i) - y_i)^2. Example: Forf(x) = x1 + 2x2, computeLgiven data points.
B. Principal Component Analysis (PCA)
Steps:
- Compute mean and covariance matrix
C. - Find eigenvalues and eigenvectors of
C. - Project data onto the eigenvector with the largest eigenvalue.
- Compute mean and covariance matrix
- Projected Variance: Largest eigenvalue of the covariance matrix.
C. Maximum Likelihood Estimation (MLE)
For Exponential Distribution (
Exp(λ)):- Likelihood:
L(λ) = Π λ e^(-λ u_i). - MLE:
λ* = 1 / (mean of samples).
- Likelihood:
4. Calculus & Continuity
Continuous Functions:
sin(x)/x(continuous atx=0if defined as1).- Piecewise functions (check limits at boundaries).
- Dirichlet function (discontinuous everywhere).
5. Geometry & Optimization
Maximizing Area:
- For a fixed perimeter, a square maximizes the area of a rectangle.
- Example: Rope of length
600m→ square with side150m→ area22500 m².
Constrained Optimization:
- Maximize
f(x,y) = x + ysubject tox² + y² = 50(use Lagrange multipliers or geometry).
- Maximize
Key Equations
| Topic | Equation | ||
|---|---|---|---|
| Binomial Mean | E[X] = n p | ||
| Binomial Variance | Var(X) = n p (1-p) | ||
| Normal PDF | f(x) = 1/(σ√(2π)) exp(-(x-μ)²/(2σ²)) | ||
| Exponential MLE | λ* = 1 / (mean of samples) | ||
| Chebyshev’s Inequality | `P( | X - μ | ≥ kσ) ≤ 1/k²` |
| CLT | (Y - nμ)/(σ√n) ~ N(0,1) | ||
| MSE Loss | L = (1/n) Σ (f(x_i) - y_i)² | ||
| PCA Projected Variance | Largest eigenvalue of covariance matrix | ||
| Convexity Composition | If g is convex and non-decreasing, and f is convex, then g ∘ f is convex. |