Home / Past papers / MLF End Term / this paper
IIT M DIPLOMA FN EXAM QDD2 13 Apr 2025 - 13 Apr 2025
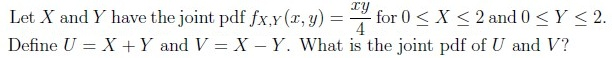
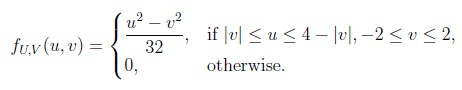
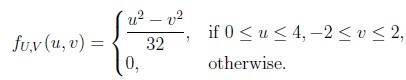
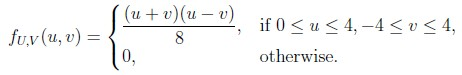
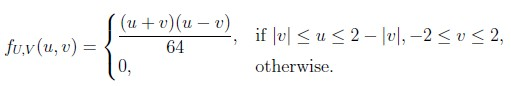
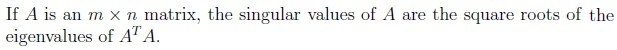
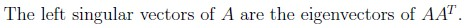
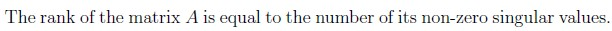
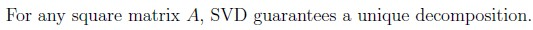
- PCA projects the original data onto a lower-dimensional subspace thatcaptures the maximum variance.
- The eigenvectors of the covariance matrix correspond to the directions ofmaximum variance.
- The principal components form a basis that is not necessarily orthogonal.
- The principal components obtained through PCA are always uncorrelated.
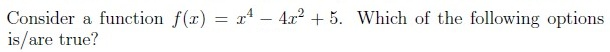
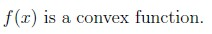
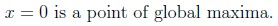
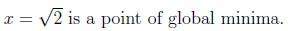
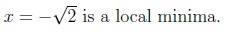
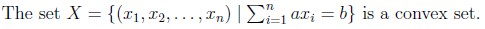
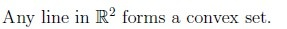
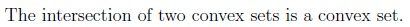
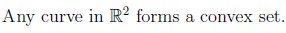
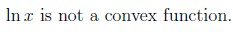
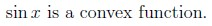
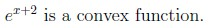
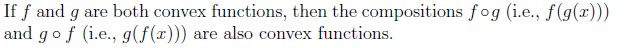
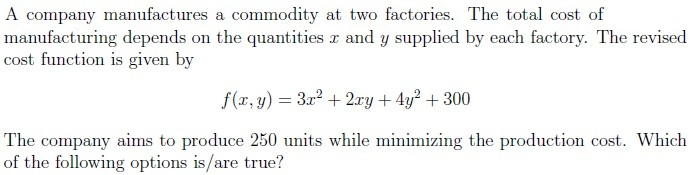
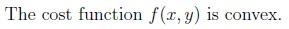
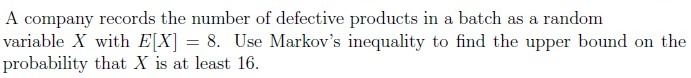
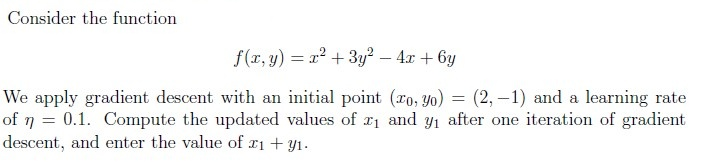



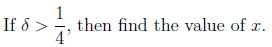
Answer key
- Q1 (MCQ, 3 marks): A
- Q2 (MSQ, 3 marks): A, B, C
- Q3 (MSQ, 3 marks): A, B, D
- Q4 (MSQ, 3 marks): C, D
- Q5 (MSQ, 3 marks): A, B, C
- Q6 (MSQ, 3 marks): A, C
- Q7 (MSQ, 4 marks): A, B
- Q8 (SA, 3 marks): 4
- Q9 (SA, 3 marks): 0.5
- Q10 (SA, 2 marks): 0.5
- Q11 (SA, 2 marks): 1
- Q12 (MSQ, 2 marks): A, C
- Q13 (MSQ, 3 marks): A, C
- Q14 (SA, 3 marks): 0.25
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations essential for the exam, followed by Mermaid knowledge graphs to visualize relationships.
Core Topics & Key Concepts
1. Probability & Statistics
Key Concepts:
Joint Probability Density Function (PDF):
- Transformation of random variables (e.g., , ).
- Jacobian determinant for change of variables.
- Support/range of transformed variables.
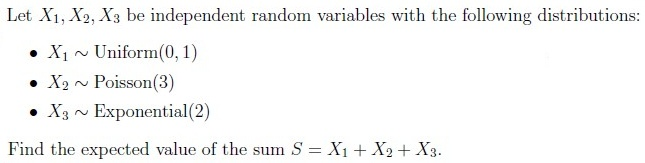
Expected Value & Linearity:
- .
Expected values for common distributions:
- Uniform(): .
- Poisson(): .
- Exponential(): .
Inequalities:
- Markov’s Inequality: .
- Chebyshev’s Inequality (not in questions but related).
Cumulative Distribution Function (CDF):
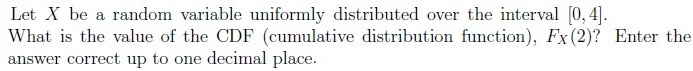
- For Uniform(): .
Key Equations:
- Joint PDF Transformation:
where is the Jacobian determinant:
- Markov’s Inequality:
- CDF for Uniform Distribution:
2. Linear Algebra & Matrix Decompositions
Key Concepts:
Singular Value Decomposition (SVD):
For matrix :
, where:
- : Left singular vectors (eigenvectors of ).
- : Right singular vectors (eigenvectors of ).
- : Diagonal matrix of singular values (square roots of eigenvalues of or ).
- Rank of = Number of non-zero singular values.
- SVD is not unique for square matrices (depends on sign flips in and ).
Eigenvalues/Eigenvectors:
- Used in PCA and SVD.
- .
Key Equations:
- SVD Relationships:
- Singular Values:
3. Principal Component Analysis (PCA)
Key Concepts:
- Goal: Project data onto a lower-dimensional subspace capturing maximum variance.
Steps:
- Center the data (subtract mean).
- Compute covariance matrix .
- Eigenvalue decomposition: .
- Principal components = eigenvectors sorted by eigenvalues (descending).
Properties:
- Principal components are orthogonal.
- Uncorrelated (if data is centered).
- First PC captures the most variance.
Key Equations:
- Covariance Matrix:
- Projection onto PCs:
4. Convex Optimization
Key Concepts:
Convex Sets:
- A set is convex if , for .
- Examples: Lines, hyperplanes, intersections of convex sets.
Convex Functions:
- is convex if:
Tests for Convexity:
- Hessian (positive semidefinite).
- First-order condition: .
Examples: , , (if domain is convex).
- Gradient Descent:
- Update rule:
Converges to minimum for convex with appropriate .
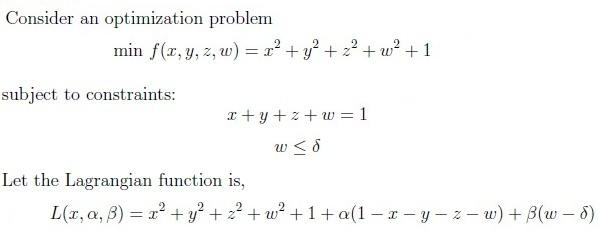
- Karush-Kuhn-Tucker (KKT) Conditions:
- Necessary for optimality in constrained optimization.
- For problem:
KKT conditions:
- Stationarity: .
- Primal Feasibility: , .
- Dual Feasibility: .
- Complementary Slackness: .
Key Equations:
- Gradient Descent Update:
- KKT Lagrangian:
- Convexity Condition (Hessian):
5. Function Analysis (Convexity, Extrema)
Key Concepts:
Convex/Concave Functions:
- convex any local minimum is global.
- concave any local maximum is global.
Critical Points:
- Find where .
- Classify using second derivative test (Hessian).
Global Extrema:
For :
- Find critical points: .
- Evaluate to determine minima/maxima.
Key Equations:
Second Derivative Test:
- If : local minimum.
- If : local maximum.
- Example Function:
Critical points: .