Home / Past papers / MLF End Term / this paper
Subject Name : 2023 Sep03: IIT M DIPLOMA ET1 EXAM - 03 Sep 2023
Elapsed 00:00
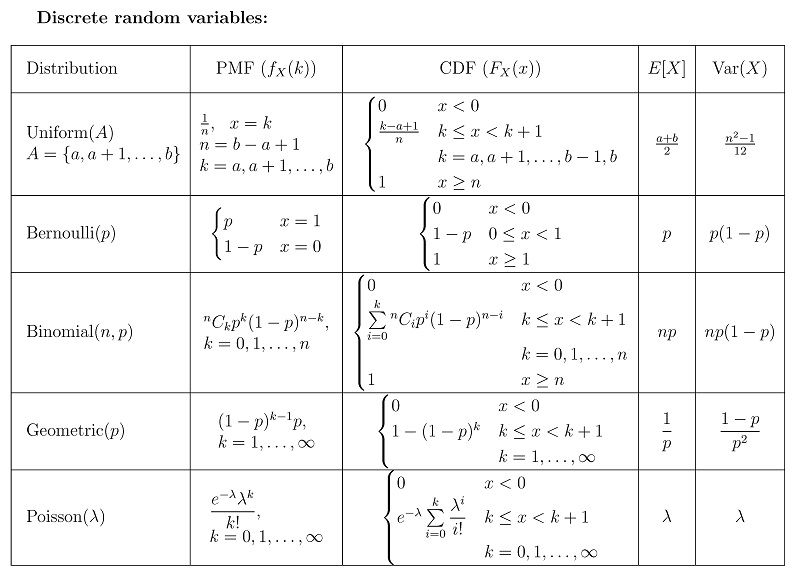
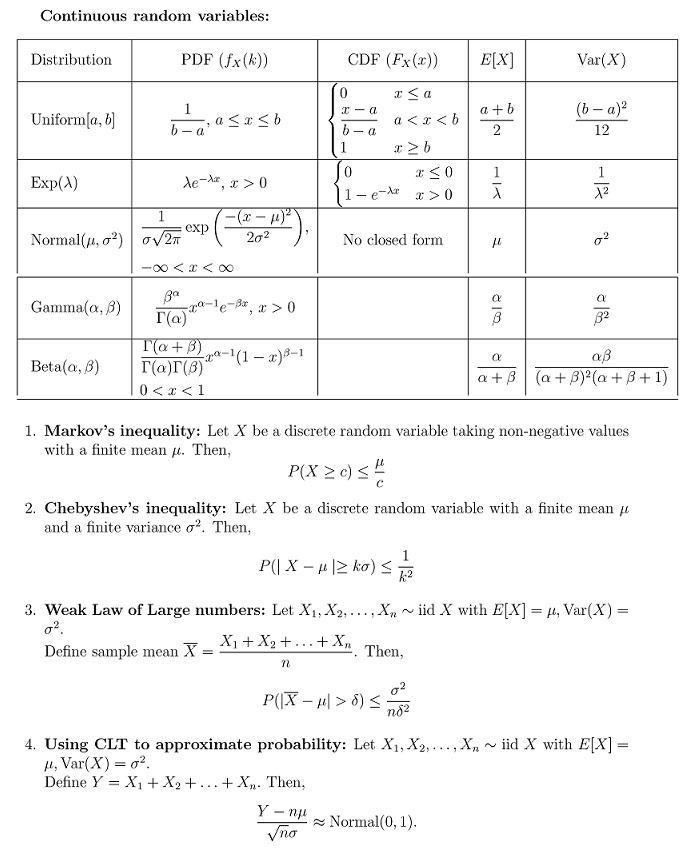
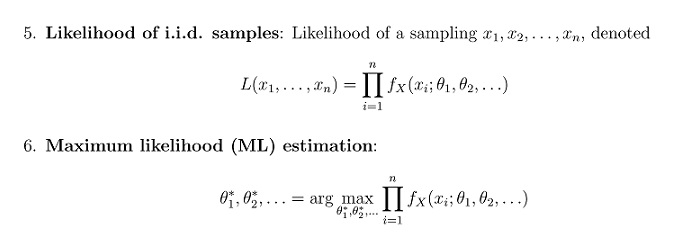
- Useful Data has been mentioned above.
- This data attachment is just for a reference & not for an evaluation.
Which of the following statements accurately describes the key difference between classification and regression models?
- In classification, the output variable is continuous and real-valued, while inregression, it is categorical.
- Regression models are used for predicting probabilities, whereas classificationmodels focus on predicting absolute values.
- Classification models aim to find decision boundaries to separate data intoclasses, while regression models seek to predict a numeric value.
- In regression, the commonly used loss function is mean squared error, whilein classification, 0 -1 loss is typically employed.
Comprehension passage - the questions below it refer to this
Based on the above data, answer the given subquestions.
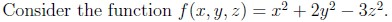
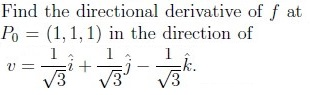
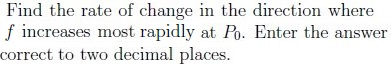
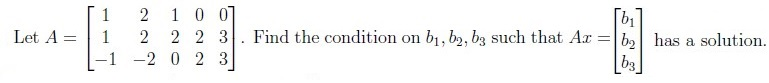
- b1 − b2 + b3 = 0
- b1 + b2 + b3 = 0
- 2b1 − b2 + b3 = 0
- 2b1 + b2 + b3 = 0
A consumer wants to maximize his utility subject to some constraints. He consumes two goods g1 and g2 and the utility function is the sum of g1 and g2. His budget is Rs.100. The per unit price of goods g1 and g2 are Rs.3 and Rs.4 respectively. Chose the correct optimization problem.
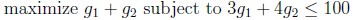
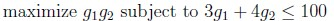
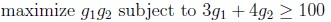
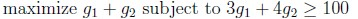
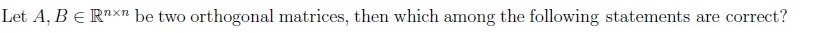
- A − I (where I is the identity matrix of the same size) is also orthogonal.
- Both AB and BA are orthogonal.
- An and Bn are orthogonal for every n > 1.
- A and B are also symmetric matrices.
Which of the following statements is/are true for a real symmetric matrix A?
- AT A and AAT have the same rank.
- AT A and AAT have the same eigenvalues
- AT A and AAT have the same eigenvectors.
- AT A and AAT have the same singular values.
Which of the following matrices is/are Unitary but not Hermitian?

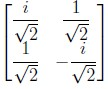
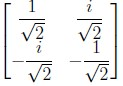

Which among the following is true for PCA?
- The first principal component represents the direction along which thevariance of the dataset is maximized.
- The first principal component represents the direction along which thevariance of the dataset is minimized.
- The first principal component is the eigenvector corresponding to the smallesteigenvalue of the covariance matrix.
- The first principal component is the eigenvector corresponding to the largesteigenvalue of the covariance matrix.
Which of the following statements regarding gradient descent is/are correct?
- If the step size is chosen as 1, we may “not always” arrive as close to theoptimal solution even after many number of iterations.
- Solution obtained for optimization problem is the local minimum of itsobjective function.
- Solution obtained for optimization problem is the global minimum of itsobjective function.
- Gradient descent converges to the global optimum in the case of convexfunctions.
- Gradient descent does not converge to the global optimum in the case ofconvex functions.
Suppose a fair coin is tossed twice. Let A denote the event that the first toss is a tail. Let B denote the event that the second toss is a tail. Let C denote the event that out of the first two tosses, either both are heads or both are tails. Which among the following options are true? Select all that apply.
- A, B and C are independent.
- A, B and C are dependent.
- A, B and C are pairwise independent.
- P(A) = P(B) = P(C) = 1/2
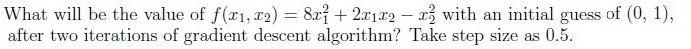
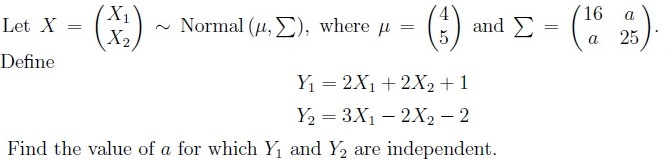
The average life (in years) of an electric bulb follows exponential distribution with parameter λ = 0.4. Using Weak Law of large numbers, find a lower bound on the probability that the mean life of a random sample of 50 such bulbs falls between 1.5 and 3.5 years. Enter your answer correct to three decimal places.
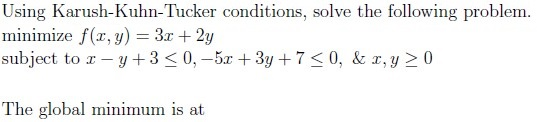


Answer key
- Q1 (MCQ, 0 marks): A
- Q2 (MSQ, 2 marks): C, D
- Q3 (SA, 2 marks): 0
- Q4 (SA, 1 marks): 7.44 to 7.52
- Q5 (MCQ, 3 marks): C
- Q6 (MCQ, 3 marks): A
- Q7 (MSQ, 4 marks): B, C
- Q8 (MSQ, 4 marks): A, B, D
- Q9 (MSQ, 3 marks): A, D
- Q10 (MSQ, 3 marks): A, D
- Q11 (MSQ, 3 marks): A, B, D
- Q12 (MSQ, 3 marks): B, C, D
- Q13 (SA, 2 marks): 225
- Q14 (SA, 3 marks): 1
- Q15 (SA, 3 marks): 40
- Q16 (SA, 3 marks): 0.870 to 0.880
- Q17 (MCQ, 4 marks): C