Home / Past papers / MLF End Term / this paper
IIT M IMPROVEMENT FN EXAM QDD2 01 Sep - 01 Sep 2024
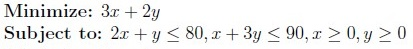
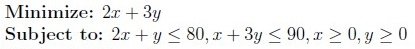
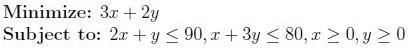
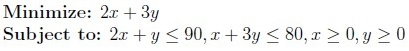
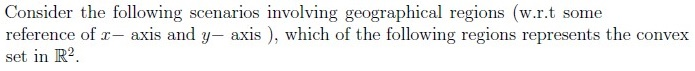
- A circular park with one side boundary is a circle of radius of 200 meters andanother side boundary is a circle of radius of 300 meters, both centered at the origin.
- City district defined by the region above the x-axis within a radius of 10 milesfrom the origin, forming a semicircle.
- A triangular region with vertices at (0, 0), (1, 0), and (0, 1).
- A path consisting of two connected line segments (forming the boundaries ofthe path on either sides) formed a “V” shape with vertices at (0, 0), (2, 2), and (2, 0)
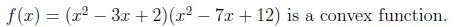
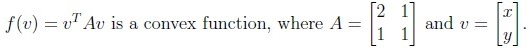
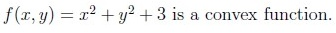
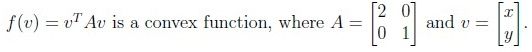
- Matrix A is symmetric matrix.
- Matrix A is Hermitian matrix.
- 1 + i is an eigenvalue of A.
- 2 − i is an eigenvalue of A.
- Matrix A is diagonalizable.
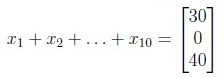
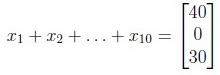
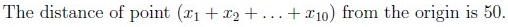
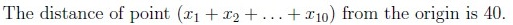
- PCA will transform the original data set onto a lower dimension subspace suchthat the variance of the project is maximized.
- PCA calculates the mean of each data set to determine its significance.
- PCA can be used to reduce the dimensionality of the dataset.
- PCA will transform the original data set onto a lower dimension subspace suchthat the reconstruction error is maximized.
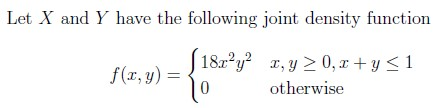
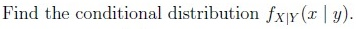
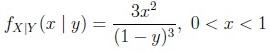
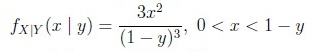
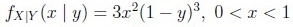
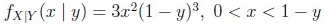
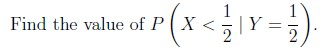
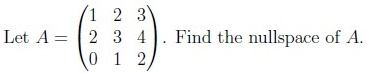
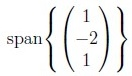

Answer key
- Q1 (MCQ, 2 marks): B
- Q2 (SA, 3 marks): 80
- Q3 (MSQ, 3 marks): B, C
- Q4 (MSQ, 3 marks): B, C, D
- Q5 (SA, 3 marks): 1800
- Q6 (SA, 3 marks): 0.25
- Q7 (SA, 3 marks): 4.2
- Q8 (SA, 3 marks): 0.262 to 0.268
- Q9 (MSQ, 4 marks): C, E
- Q10 (MSQ, 4 marks): B, C
- Q11 (MSQ, 2 marks): A, C
- Q12 (MCQ, 3 marks): B
- Q13 (SA, 2 marks): 1
- Q14 (MCQ, 2 marks): A
Concepts this paper tests
Auto-generated summary from the source site. Handy as a checklist; the lessons above explain each idea from scratch.
Here’s a structured summary of core topics, concepts, principles, and equations for the "Diploma Level: Machine Learning Foundations" exam, along with Mermaid knowledge graphs to visualize relationships.
1. Core Topics & Key Concepts
A. Linear Programming & Optimization
Primal Optimization Problem:
- Objective: Minimize/maximize a linear function subject to linear constraints.
Standard form:
Minimize: c₁x + c₂y
Subject to:
  a₁₁x + a₁₂y ≤ b₁
  a₂₁x + a₂₂y ≤ b₂
  x, y ≥ 0
Example (Q2, Q3):
- Cost function:
2x + 3y(P1: ₹2, P2: ₹3). Constraints:
- Labor:
2x + y ≤ 80 - Machine:
x + 3y ≤ 90
- Labor:
- Solution: Solve using graphical method or simplex algorithm.
- Minimum cost: ₹80 (when
x=40, y=0).
- Cost function:
Key Equations:
- Feasible region: Intersection of all constraints.
- Optimal solution: Vertex of the feasible region where the objective is minimized/maximized.
B. Convex Sets & Functions
Convex Set (Q4):
- A set
Sis convex if for anyx, y ∈ Sandλ ∈ [0,1],λx + (1-λ)y ∈ S. Examples:
- Semicircle (convex).
- Triangle (convex).
- "V" shape (non-convex unless filled).
- A set
Convex Function (Q5):
A function
fis convex if:f(λx + (1-λ)y) ≤ λf(x) + (1-λ)f(y) ∀ λ ∈ [0,1]Tests for Convexity:
Hessian Matrix:
∇²f ≥ 0(positive semidefinite).- For
f(v) = vᵀAv,Amust be PSD. Example (Q5B, Q5D):
A = [[2,1],[1,1]](PSD, eigenvalues > 0).A = [[2,0],[0,1]](PSD, diagonal entries > 0).
- For
- Quadratic Forms:
f(x,y) = x² + y² + 3(convex, Hessian =[[2,0],[0,2]]).
Key Equations:
Hessian for
f(x,y):H = [∂²f/∂x² ∂²f/∂x∂y] [∂²f/∂y∂x ∂²f/∂y²]
C. Probability & Statistics
Chebyshev’s Inequality (Q7):
Bounds the probability that a random variable
Xdeviates from its meanμ:P(|X - μ| ≥ kσ) ≤ 1/k²Example:
μ = 70,σ = 8,k = 2(since16 = 2σ).P(|X - 70| ≥ 16) ≤ 1/4 = 0.25.
Normal Distribution (Q9):
If
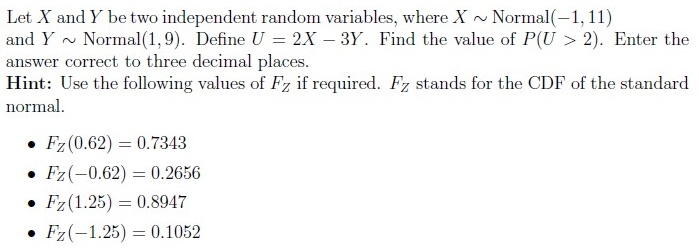
X ~ N(μ₁, σ₁²)andY ~ N(μ₂, σ₂²), then:aX + bY ~ N(aμ₁ + bμ₂, a²σ₁² + b²σ₂²)Example:
U = 2X - 3Y, whereX ~ N(-1,11),Y ~ N(1,9).U ~ N(2*(-1) - 3*1, 4*11 + 9*9) = N(-5, 125).- Standardize:
P(U > 2) = P(Z > (2 - (-5))/√125) ≈ P(Z > 0.63) ≈ 0.264.
Joint & Conditional Distributions (Q13, Q14):
- Joint PDF:
f(x,y) = 18x²y²forx + y ≤ 1. Conditional PDF:
f_X|Y(x|y) = f(x,y) / f_Y(y)Example (Q13):
- Marginal
f_Y(y) = ∫₀^(1-y) 18x²y² dx = 6y²(1-y)³. - Conditional:
f_X|Y(x|y) = 3x²/(1-y)³for0 < x < 1-y.
- Marginal
Conditional Probability (Q14):
P(X < 1/2 | Y = 1/2) = ∫₀^(1/2) f_X|Y(x|1/2) dx = 1.
- Joint PDF:
D. Linear Algebra
Eigenvalues & Diagonalization (Q10):
If
1is an eigenvalue ofA, then:- Trace(A) = sum of eigenvalues →
3 = 1 + λ₂ + λ₃. - Determinant(A) = product of eigenvalues →
2 = 1 * λ₂ * λ₃. - Possible eigenvalues:
1, 1±i(since complex eigenvalues come in pairs).
- Trace(A) = sum of eigenvalues →
- Diagonalizable:
Ais diagonalizable if it hasnlinearly independent eigenvectors.
Nullspace (Q15):
- Nullspace of
A: All vectorsxsuch thatAx = 0. Example:
For
A = [[1,2,3],[2,3,4],[0,1,2]], solveAx = 0:- Row reduce to find
x = t[1, -2, 1]ᵀ. - Nullspace:
span{[1, -2, 1]ᵀ}.
- Row reduce to find
- Nullspace of
E. Machine Learning Basics
Linear Regression & Loss Function (Q8):
- Model:
f(x) = w₁x₁ + w₂x₂ + w₃x₃(herew = [1, 2, 1]). Loss (MSE):
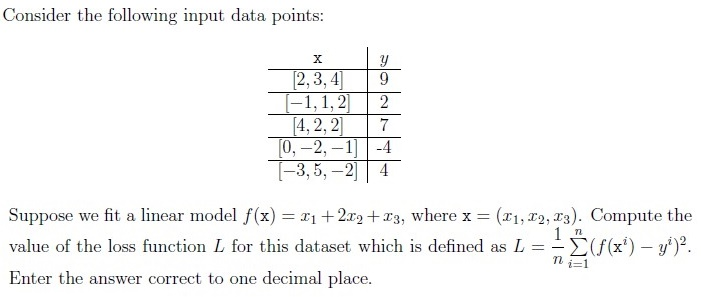
L = (1/n) Σ (f(xᵢ) - yᵢ)²Example Calculation:
- For
x = [2,3,4],f(x) = 2 + 6 + 4 = 12,y = 9→(12-9)² = 9. - Average over all points:
L = 4.2.
- For
- Model:
PCA (Principal Component Analysis) (Q12):
- Goal: Project data onto a lower-dimensional subspace to maximize variance (or minimize reconstruction error).
Steps:
- Center the data (subtract mean).
- Compute covariance matrix.
- Eigen decomposition to find principal components.
Key Points:
- PCA does not use the mean to determine significance (Q12B is false).
- Reduces dimensionality while preserving structure.
F. Optimization in Geometry (Q6)
Maximizing Area with Constraints:
- Problem: Fence a rectangular field along a river (3 sides fenced, 1 side river).
- Constraints:
2w + l = 120(fencing length). - Area:
A = w * l = w(120 - 2w). - Maximize: Take derivative
dA/dw = 120 - 4w = 0→w = 30,l = 60. - Maximum area:
30 * 60 = 1800.
G. Data Science (Q11)
Minimizing Sum of Squared Distances:
- Problem: Find point
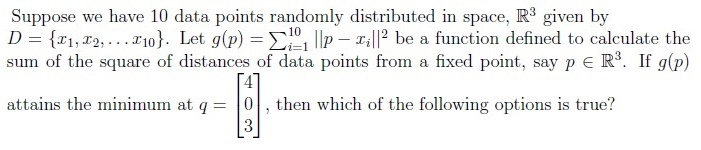
pthat minimizesg(p) = Σ ||p - xᵢ||². - Solution:
pis the mean of the data points. Example:
- Minimum at
q = [4, 0, 3]→ Mean ofxᵢis[40, 0, 30](10 points). - Distance from origin:
√(40² + 0² + 30²) = 50.
- Minimum at
- Problem: Find point
Graph 2: Convexity
Graph 3: Probability & Statistics
Graph 4: Linear Algebra
Graph 5: Machine Learning
Graph 6: Geometry & Optimization
3. Key Equations Summary
| Topic | Equation | ||||
|---|---|---|---|---|---|
| Linear Programming | Minimize c₁x + c₂y s.t. a₁₁x + a₁₂y ≤ b₁, x,y ≥ 0 | ||||
| Chebyshev’s Inequality | `P( | X-μ | ≥ kσ) ≤ 1/k²` | ||
| Normal Distribution | aX + bY ~ N(aμ₁ + bμ₂, a²σ₁² + b²σ₂²) | ||||
| Conditional PDF | `f_X | Y(x | y) = f(x,y)/f_Y(y)` | ||
| PCA Objective | Maximize Var(X_projected) or minimize ` | X - X_reconstructed | ²` | ||
| MSE Loss | L = (1/n) Σ (f(xᵢ) - yᵢ)² | ||||
| Eigenvalues | Trace(A) = Σ λᵢ, det(A) = Π λᵢ | ||||
| Nullspace | Ax = 0 → Solve for x | ||||
| Sum of Squares | `g(p) = Σ | p - xᵢ | ² (minimized at p = mean(xᵢ)`) |